A Primer on the History and Evolution of Incident Management to Today
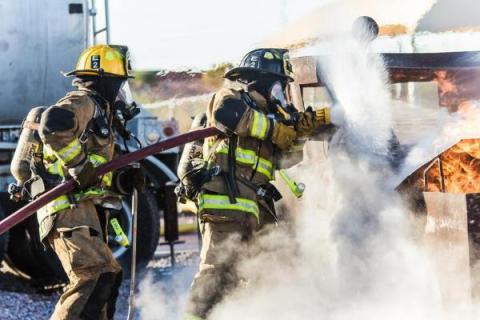
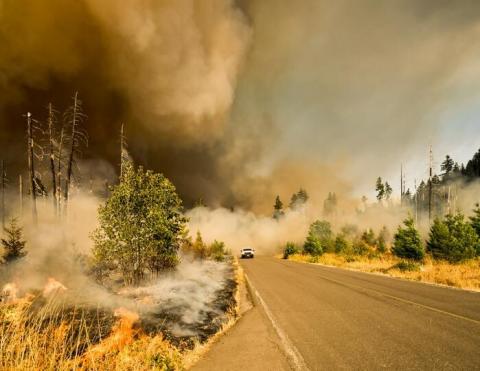
Many of the concepts SREs take for granted about incident management originated with efforts to fight fires in California in the 1970s.
The latest News and Information on Service Reliability Engineering and related technologies.
Many of the concepts SREs take for granted about incident management originated with efforts to fight fires in California in the 1970s.
Unlike traditional IT Ops, the role of the SRE isn’t simply focused on finding and solving technical problems. The big win for today’s SREs is supporting the organization’s strategic innovation initiatives. With the appropriate observability capabilities, it’s possible to quantify the value that software infrastructure contributes to this innovation effort.
An overview of major IT incidents and outages in 2021
The term Site Reliability Engineer (SRE) first appeared in Google in the early 2000s. In Google’s 2016 SRE Book, Benjamin Treynor Sloss wrote that, generally speaking, “an SRE team is responsible for the availability, latency, performance, efficiency, change management, monitoring, emergency response, and capacity planning of their service(s).” This means that the SRE teams at Google decide how a system should run in production as well as how to make it run that way.
A summary of the Log4j vulnerability, and key takeaways for SREs.
Automation takes repetitive tasks off professionals’ plates, empowering them to free up time to focus on more valuable activities. Moogsoft’s API-driven automation capabilities enable SREs to make better use of their time, leading to better results for the business.
Asking an IT engineer or SRE to define the purpose of observability is kind of like asking someone to explain the purpose of life: There are lots of different opinions out there, and no way of proving any of them right or wrong. You could argue that observability is just a buzzword that refers to what used to be called monitoring.
SREs face special challenges during the holidays. Here’s how to manage them.
An explanation of observability that highlights the role observability data play in supporting the active role of SREs as they reduce toil, improve uptime, and judiciously consume the error budget.