Operations | Monitoring | ITSM | DevOps | Cloud

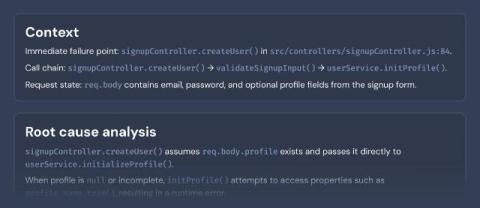
From Stack Trace to Probable Cause: AI Root Cause Analysis Is Here

You know the drill. An error fires, you get the stack trace, and then you spend the next 45 minutes tracing it backward through four services, two config files, and a deploy that happened three hours ago. You eventually find the root cause, but the path to get there was manual, slow, and entirely dependent on how well you already knew the codebase. We built AI-powered root cause analysis (RCA) for that kind of slog.
AI Factories Will Be Won on Efficiency: Why the Kubex + Rafay Partnership Matters

The early era for AI was defined by experimentation, standing up isolated environments, and finding the first practical use cases. Today, the conversation is different. Enterprises are no longer asking whether AI matters. They are asking how to scale it sustainably, securely, and economically. That shift is giving rise to the AI factory: a repeatable, governed, production-ready environment where data scientists, platform teams, and application teams can build, train, deploy, and operate AI at scale.

Optimizing the OpenTelemetry Python SDK for LLM Workloads

Agentic workloads thrive with precision tooling. Just like developers, they need the rich context, high cardinality, and fast feedback loops that allow them to ask exploratory open-ended questions of their code. But instrumentation is costly, and from the dawn of software, developers have tried to do the most possible with the least amount of resources.

Your AI Agents Are Only As Good As Your Data | Harness Blog

Every agent demo follows the same arc. The agent calls an API. A deployment triggers. A ticket gets created. The audience is impressed. Then someone asks a real question: "Which regions had the highest order failure rate this quarter, and are any of them linked to vendor SLA breaches?" That question crosses four entity types — orders, fulfillment records, vendors, SLA contracts.

Top 6 AI SRE Tools and Why Runtime-Grounded Reliability Is the New Standard

AI SRE tools accelerate incident detection, root cause analysis, and remediation across distributed production systems. They ingest telemetry signals, including logs, metrics, traces, alerts, and deployment history, to correlate anomalies, narrow fault domains, and reduce manual triage. This guide breaks down the top AI SRE tools in 2026 and helps you choose the right one based on your team’s biggest bottleneck, whether that is faster triage, deeper root cause analysis, or runtime-level validation.

Getting more out of Playwright CLI: a practical guide for QA and DevOps teams

If your team runs Playwright tests in CI, you already know the npx playwright test drill. It works fine until your suite crosses a few hundred tests. Then things get messy. Flaky reruns stack up. Debugging means downloading trace zip files and opening them on your laptop. Reports? Static HTML files that people stop checking after day 3.

Claude outage April 2026: what happened and how it was detected early

On April 9, 2026, Claude experienced a widespread but inconsistent outage that left many users unable to access or interact with the service. StatusGator detected the issue early and sent an Early Warning Signal 59 minutes before the provider officially acknowledged the outage. This incident highlights how early detection can provide critical lead time when official status pages lag behind real user impact.

How Agentic AI Powers Hybrid and MultiCloud Operations

Hybrid and multi‑cloud environments didn’t break operations—they simply outpaced the human ability to manage them. Gartner predicts that 90% of organizations will adopt a hybrid cloud approach through 2027, confirming that multi-vendor estates are now the permanent operating model. Yet, as environments grow more distributed, a “Complexity Gap” has emerged.