Operations | Monitoring | ITSM | DevOps | Cloud

Chaos Engineering: The Path to Reliability - Kolton Andrus

We’re all here for the same purpose: to ensure the systems we build operate reliably. This is a difficult task, one that must balance people, process and technology during difficult conditions. We operate with incomplete information, assessing risks and dealing with emerging issues. We’ve found Chaos Engineering to be a valuable tool in addressing these concerns. Learn from real world examples what works, what doesn’t, and what the future holds.
Identifying Hidden Dependencies - Liz Fong Jones

You don't need to write automation or deploy on Kubernetes to gain benefits from resilience engineering! Learn how Honeycomb improved the reliability of our Zookeeper, Kafka, and stateful storage systems through terminating nodes on purpose. We'll discuss the initial manual experiments we ran, the bugs in our automatic replacement tools we uncovered, and what steps we needed to progress towards continuously running the experiments. Today, no node at Honeycomb lives longer than 12 months, and we automatically recycle nodes every week.

Lead Times and Psychological Safety within the Five Ideals - Gene Kim

The biggest challenges engineering organizations face are not technical. They’re fundamental problems with how we think and go about doing work, and the environments that we work in. In this talk, Gene Kim will share the Five Ideals and how they relate to Chaos Engineering. He’ll also show how the Five Ideals help build stronger, better performing, and ultimately more reliable companies.

How many 9's are enough? Kolton Andrus  CTO Connection: Reducing engineering cycle time

How many nines of availability are enough? In this talk, Gremlin CEO Kolton Andrus shares insights from years at Amazon, Netflix, and now working with a wide array of customers across various disciplines and industries. He’ll describe what each level of availability looks like, the challenges faced at each stage, and the trade-offs required to achieve the next nine of uptime.

The Halo of Resilience Engineering  J. Paul Reed  Failover Conf 2020

Recent world-impacting events have caused us all to have to rethink the way we go about our daily work; in this talk, we'll look at how some of the pillars of Resilience Engineering might help you and your team deal with the changes we're all being forced to confront.

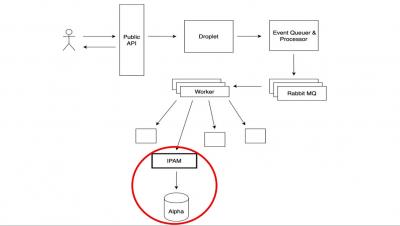
Improving a Distributed System Post-Incident Julius Zerwick Failover Conf 2020

In this session, we will dive into a case study of how a team can recover & improve a distributed system after a major incident. Distributed systems are more prone to failure than other systems due to their incredible complexity and scale, and incidents are a fact of life with these systems.