Operations | Monitoring | ITSM | DevOps | Cloud

Claude Opus pricing in 2026: every model, every rate, and whether it's worth it

Claude Opus pricing is $4 per million input tokens and $20 per million output tokens on Claude Opus 5.5, the current model, with cache reads at $0.20 and batch jobs at $2/$10. Opus 5 and the legacy 4-series bill at $5/$25. The 1M context window carries no surcharge. Every Opus model Anthropic shipped in 2026 held the same line: $5 in, $25 out, per million tokens. Opus 4.6 in February, 4.7 in April, 4.8 in May, Opus 5 in July. Four releases, one price. On September 22, 2026, the line broke.
Shipped: Project this month's AI cost before the invoice closes

The question comes up on the 10th, the 15th, and again on the 25th. Where is AI spend going to end up this month? The invoice won’t tell you until it’s closes, and by then there’s nothing left to forecast. “If I’m looking at this on the 15th, I want to know where we’re going to land.” That’s how a finance lead put it during a persona session in September, and it’sthe whole job. You have half a month of real usage behind you.

Reducing Android scope-sync overhead in Sentry Flutter

Our SDK adds work to the app that installs it. It records recent app activity as breadcrumbs and keeps user information and other diagnostic data up to date. Changes to that information are called scope updates. On Android, we send those updates to a worker isolate, which passes them to the Sentry Android SDK. We found that the calling isolate and the worker both normalized the same data. The encoding step also created a JSON string and an extra byte buffer that we could avoid.

AI is making software delivery less stable. DORA's Nathen Harvey on the fix | EVOLVE 2026

DORA's data shows that as AI adoption goes up, individual effectiveness rises, and so does software delivery instability: more rollbacks and more unplanned rework. Nathen Harvey of Google's DORA team explains why AI acts as an amplifier of whatever system you already have. He walks through the seven capabilities that separate teams getting real gains from teams drowning in downstream chaos. He also argues that the risks stopping you from shipping AI-built work should become your platform roadmap.

When AI agents ignore the code freeze: governance that holds | EVOLVE 2026

AI can write 1,100 lines of code for a loading spinner in five minutes. Your change board still meets once a week. Karthik Jayaraman, VP of Information Technology at Fiserv, explains what happens when code generation speeds up and everything downstream stays the same. He covers why "human in the loop" doesn't scale, why handing all review to AI backfires, and why an agent told not to touch production needs a boundary it can't cross, not just an instruction.

Run incident response in your FedRAMP High environment

Earlier this year, Datadog for Government achieved FedRAMP High certification, extending our GovCloud environment (US1-FED) to the federal government’s most sensitive civilian workloads. That certification now covers Datadog Incident Response, bringing paging, incident coordination, automation, and postmortem workflows into US1-FED. When a government system goes down, responders need to reach the right people, coordinate a fix, and keep stakeholders informed.

Define user actions on your web app with visual labeling in Product Analytics

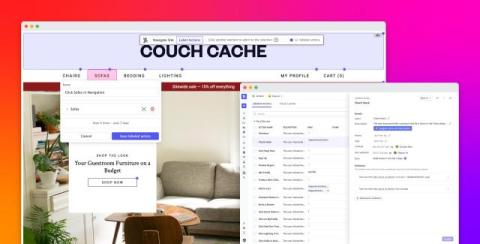
Adding or renaming a product event has traditionally meant creating an engineering ticket. Datadog Product Analytics uses the same SDKs and configuration as Real User Monitoring (RUM), and those SDKs autocapture actions such as clicks and taps. But an automatically generated action name describes the element rather than the user intent behind it.