Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on Cloud monitoring, security and related technologies.
How CFOs can control AI spend and prove AI's value

Neil Sawyer, Senior Vice President and Managing Director for HP Europe, Middle East and Africa, recently published “Scaling AI Without Losing Control” in Forbes Business Council. His starting point will be familiar to any finance leader. AI pilots looked affordable on pay-per-token and pay-per-query pricing, and that same pricing can get far more expensive at enterprise scale. Gartner forecasts worldwide AI spending will reach $2.7 trillion in 2026, up 49.5%.

AI infrastructure costs in 2026: what the stack is, what each layer costs, and how much to commit

AI infrastructure costs span four buying tiers in 2026: API-only teams spend hundreds to tens of thousands per month on tokens, GPU renters typically pay $2 to $10 per GPU-hour by chip class, committed-capacity buyers sign six-to-eight-figure reservation contracts, and owners spend millions per rack. The stack has six layers, and most budgets underestimate everything below the GPU line.

How to Avoid Cloud Vendor Lock-In: A Practical Guide for 2026

You avoid cloud vendor lock-in by keeping the parts that are expensive to move portable: the compute runtime, identity, data, networking, and deployment tooling. You accept proprietary services only where their value clearly exceeds the exit cost, so that leaving or adding a provider is a configuration change rather than a rewrite.

The Cheapest Personal Cloud Storage Offers 2026

Finding the cheapest personal cloud storage doesn’t mean compromising on privacy or security. In this guide, we compare the best and most affordable cloud storage options for personal use in 2026, covering free plans, monthly subscriptions, storage capacity, security features, and lifetime deals to help you find the best value for your needs.

Best open-source LLMs in 2026: ranked by cost to run

The best open source LLMs by family: DeepSeek V4 for frontier reasoning under MIT, Qwen3.8 and Gemma 4 for clean Apache 2.0 licensing, GLM-5.3 for coding, Kimi K3 for long context, Llama 4 for single-GPU scale. The real ranking depends on your deployment lane and token volume, and this guide prices all three lanes. At CloudZero, Bill Buckley, our SVP of Engineering, gives every engineer a $5,000 monthly AI token budget and published the math behind it.

Shipped: Find the GCP buckets with high cross-location read charges

You can now see which of your Multi-Region Cloud Storage buckets have cross-location read charges worth acting on, and start with the ones where a cache would save the most. It runs automatically for every organization with GCP Cloud Storage, so there’s nothing to set up. Google bills network data transfer when a Google Cloud service in one location pulls data from a Multi-Region bucket in another.

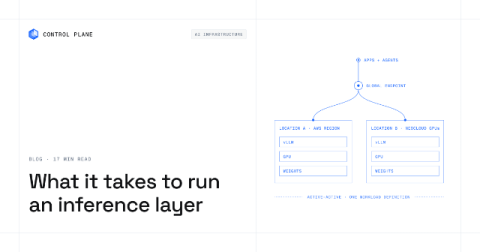
What Infrastructure Do You Need to Run an Inference Layer? A Production Guide

A production inference layer needs GPU compute sized to the model, a serving runtime such as vLLM or SGLang, orchestration that autoscales on queue depth, one endpoint with health-aware routing and failover, model weights cached near the GPUs, and observability, security, and cost controls.

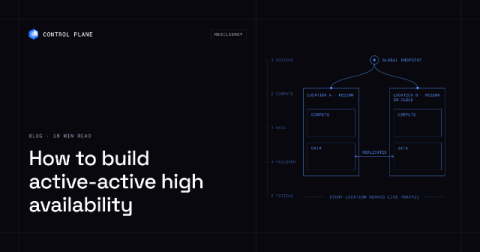
How to Build Active-Active High Availability Across Regions and Clouds

Active-active means two or more locations serve live traffic at the same time, with the application running in each and its data replicated across them, so no location sits idle waiting for a failover. You build it in five layers, and data is the hardest.