Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on DevOps, CI/CD, Automation and related technologies.

Keep OSS supply chain attacks off the menu: Tidelift catalogs + JFrog serve known-good components

How does your organization keep track of all of the open source components being used to develop applications and ensure they are secure and properly maintained? Our recent survey data shows that the larger an organization gets, the less confident they are in in their open source management practices. In companies over 10,000 employees, 39% are not very or not at all confident their open source components are secure, up to date, and well maintained.

Podcast: Break Things on Purpose | Jose Nino, Staff Software Engineer at Lyft

Get started with Gremlin's Chaos Engineering tools to safely, securely, and simply inject failure into your systems to find weaknesses before they cause customer-facing issues. Break Things on Purpose is a podcast for all-things Chaos Engineering. Check out our latest episode below. You can subscribe to Break Things on Purpose wherever you get your podcasts. If you have feedback about the show, find us on Twitter at @BTOPpod or shoot us a note at [email protected]!

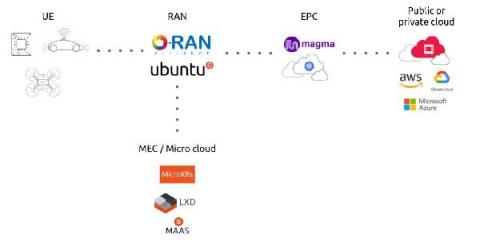
Introduction to open source private LTE and 5G networks

It’s so easy these days to set-up your own WiFi network. You order a router online, plug it into the electrical socket, define a password and you’re good to go. WiFi is fast, reliable and easy to use. But if you want to cover a wider area or connect hundreds of small devices it quickly becomes inefficient and expensive. Is the only way to go to your local mobile network operator and sign a contract? No! Thanks to open source technology, you can build your own LTE or 5G network.

WTF is Incident Management? Post-Panel Wrap-Up

That's a wrap! We hosted "WTF is Incident Management" on May 12, 2021. We invited four very knowledgeable panelists to discuss how they define incident management, what changes they'd make if they could start again from scratch, how to manage team stress after an incident, and other subjects. Our panelists were: host Matt Stratton (Staff Developer Advocate at Pulumi), Emily Ruppe (Incident Commander at Twilio), Alina Anderson (Sr.

A Day in the Life: Intelligent Observability at Work with our SRE, Dinesh

When I asked Charlie for permission to attend this year’s AICon (virtual, natch) I thought it would be a shoo-in; learning’s part of my OKRs after all. But he never makes things easy and his ‘yes’ came with a caveat that’s typical when dealing with him. This time, he claimed he didn’t have the budget for the ticket (a likely story!) and I’d have to find another way to get one.

Messy AWS Tags? Confidently Allocate Costs Without a Perfect Tagging Strategy

AWS tags are a bit like flossing your teeth every day — or getting eight hours of sleep a night. Everyone agrees they’re good habits that will make life easier down the road. But sometimes life gets in the way, and those habits fall a little short. Most teams set out with the intention to tag their infrastructure, but in our experience, it’s rare that companies have a perfect, thorough AWS tagging strategy.

Automating load tests for APIs

In most cases, when users start to access and use a new application or a new release, app performs pretty well. As the user base grows and usage increases, the app can outgrow its infrastructure. Users can start experiencing a dip in performance. Latency increases, bandwidth and memory get exhausted quickly, and some code architectures start to fail because they do not scale well with the increased amount of users.

SRE Availability Metrics

How available is your website, service, or platform? What must you monitor and measure to ensure availability? How do you translate uptime into availability? This chart has numbers that every Site Reliability Engineer (SRE) should know. Below the chart, you will find answers to commonly asked questions about SRE and associated metrics.