|
By Matt LeRay
Change one field in a.proto from double to string, and nothing complains. The code compiles, the deploy goes green, and a service still built from the old contract keeps answering with a double. Here’s what Go’s protobuf runtime does when a client on the new contract reads that answer: No error. risk_score comes back empty, and the nine bytes of the double are tucked away as unknown fields.
|
By Matt LeRay
Replay a GraphQL recording at the server that produced it, and every request comes back 200 OK. Here is one of those 200s, from a Session query whose recorded token has expired: A GraphQL server reports most failures inside a successful HTTP response, so any check that stops at the status code passes this request. And that is the second way GraphQL hides from URL-shaped tooling.
|
By Matt LeRay
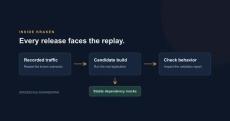
A readiness check should make a release safer. During one release validation, ours kept Kraken’s traffic replays stuck in Initializing until they timed out. The operator was asking Kubernetes for EndpointSlices. Its installed permissions did not allow that request. The code needed a real cluster, the generated permissions, and a replay trying to start before that mistake became obvious. Kraken put those pieces together during release validation.
|
By Alan Mon
On October 20, a power failure in one of Google Cloud’s three London zones disrupted Revolut, Lloyds, HSBC and others for hours. One zone failed, errors spread region-wide, and Google warned customers they might not be able to create new workloads to fail over to. Most teams find out how resilient they are during an outage, not before one. These five questions let you find out first.
|
By Matt LeRay
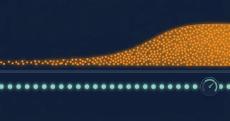
What happens to transaction posting when statement traffic gets expensive? That’s the question a bank’s platform team actually needs answered before a busy month-end. It’s also a question most load tests can’t ask, because they turn one dial for the whole recording. Statements get heavier, posting gets heavier, and the average latency across both looks fine right up until customers can’t move money.
Sponsored Post
|
By Matt LeRay
We shipped a chaos feature that never caused any chaos. Our mock server has had a fault-injection effect for years with a straightforward job: withhold the response entirely and see whether the caller copes. Last week I audited it against the actual code path. It had never withheld anything. The handler returned early without writing a response. Go's net/http then did what it is designed to do, which is synthesize a 200 OK and flush the recorded body. Every experiment anybody ever ran with that effect handed the application a perfectly good answer, and every one of them passed.
|
By Alan Mon
We made software development faster. Now we need to make validation faster, too. For the last decade we have shifted development left. Testing, security, performance, and CI/CD all moved closer to the developer. Observability mostly did not. It still starts after deployment (we covered the incident side of this in Your Observability Stack Found the Fire), which means the people writing the code rarely have meaningful production behavior to observe while they build.
|
By Ken Ahrens
Before you can answer whether checkout will survive Black Friday, you need a test you can rerun. In this demo, we used a coding agent and the Speedscale skills to record a Node app, mock its downstream API, and run a 30-second load test with 10 virtual users. That’s a small first step in holiday readiness. It gives you a working test and a result to inspect, with time left to fix what you find before a code freeze.
|
By Matt LeRay
The first PostgreSQL post ran on a laptop: a demo app, a Docker container, and the proxymock CLI. That is the fastest way to see the idea. It is also not where your database problems live. Your real query mix lives in the cluster, where a Java service with a connection pool, an ORM and a schema migration tool sends the statements nobody wrote by hand. This post deploys an open source banking app to Kubernetes and records the queries one of its services sends to PostgreSQL.
|
By Shaun Duncan
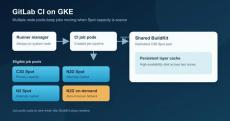
Here at Speedscale, our monorepo has 19 Go projects in CI. Fifteen produce container images for both amd64 and arm64; a few of those need CGO. We also publish cross-compiled CLI binaries for macOS, Linux, and Windows.
|
By Speedscale
Learn how to test your application's fallback mechanisms by intentionally injecting chaos and simulated dependency failures into recorded API traffic. Easily configure scoped rules to inject status code errors or delays during mock runs to verify your app handles failure gracefully. Learn more: speedscale.com.
|
By Speedscale
Learn how AI handles different types of testing, from simple unit tests to complex end-to-end setups. Discover where AI succeeds in writing test code and where human strategy is still needed. Learn more: speedscale.com.
|
By Speedscale
While AI coding agents increase initial build speed, they often lack context about real-world user behavior, leading to downstream production bugs. Watch to learn how to move beyond basic agent-on-agent reviews and set up a true "Quality Factory" using: Check out our demos or get started free: speedscale.com.
Test AI-Generated Code with Real Traffic#aiagents #devops #observability #shiftleft #softwaretesting
|
By Speedscale
AI can generate code in seconds, but testing it against real production behavior is where developers get stuck. Learn how capturing and replaying actual production traffic in development helps you catch bugs before you deploy!
|
By Speedscale
Learn how to quickly set up a load testing foundation for your Node app using the free ProxyMock tool combined with an AI coding agent. This walkthrough demonstrates how to record traffic, mock dependencies, and analyze latency distribution results in just a few simple steps. Learn more: speedscale.com.
|
By Speedscale
DevOps customers are rejecting standalone AI agents and web interfaces in favor of integrating context directly into their existing harnesses, such as Copilot or Claude. Rather than logging into separate tools, developers prefer combining models and technologies within a single context window to streamline software development and debugging. Learn more: speedscale.com.
|
By Speedscale
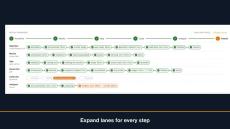
Learn how to track cluster performance in real time using the replay progress panel, which highlights key phases including provision, mock, app, load, analyze, and result. You will also discover how to easily troubleshoot failed runs by expanding component lanes to review specific step reasons and cluster events. Learn more: speedscale.com.
Feature Spotlight: Automatic Testing with Proxymock MCP Skills #aiagents #mcpserver #softwaretesting
|
By Speedscale
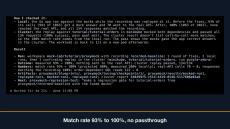
Learn how to integrate your AI coding agent with Speedscale using the MCP server to record, replay, tune mocks, and analyze reports directly within your workspace. Streamline your testing workflow by letting your agent automatically capture traffic, resolve failing responses, and optimize match rates. Learn more: speedscale.com.
|
By Speedscale
Learn how to resolve failed GraphQL session queries by updating expired tokens before replaying your snapshot. This video demonstrates how to find the GraphQL operation, edit variable values by path, and successfully pass replay checks. Learn more: speedscale.com.
Feature Spotlight: Import & Export to Load Testing Tools #api #postman #openapi #loadtesting #devops
|
By Speedscale
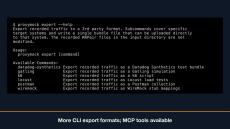
Proxymock allows you to import existing Postman collections, browser HAR files, and OpenAPI specifications to instantly create test requests and mock responses. You can also pull traffic directly from cloud storage buckets, or export your requests into load testing scripts for tools like K6, Gatling, and Locust. Coding agents can even manage these imports and exports using integrated MCP tools. Learn more: speedscale.com.
- October 2026 (29)
- September 2026 (18)
- August 2026 (20)
- July 2026 (24)
- June 2026 (26)
- May 2026 (19)
- April 2026 (27)
- March 2026 (20)
- February 2026 (20)
- January 2026 (30)
- December 2025 (15)
- November 2025 (12)
- October 2025 (14)
- September 2025 (16)
- August 2025 (14)
- July 2025 (8)
- June 2025 (1)
- May 2025 (4)
- April 2025 (16)
- March 2025 (10)
- February 2025 (1)
- January 2025 (7)
- December 2024 (13)
- November 2024 (9)
- October 2024 (24)
- September 2024 (13)
- August 2024 (10)
- July 2024 (4)
- June 2024 (4)
- May 2024 (2)
- April 2024 (5)
- March 2024 (4)
- February 2024 (3)
- January 2024 (1)
- December 2023 (3)
- November 2023 (3)
- October 2023 (4)
- September 2023 (2)
- August 2023 (13)
- July 2023 (2)
- June 2023 (4)
- May 2023 (2)
- April 2023 (2)
- March 2023 (7)
- February 2023 (6)
- January 2023 (4)
- December 2022 (3)
- November 2022 (4)
- October 2022 (2)
- September 2022 (3)
- August 2022 (5)
- July 2022 (5)
- June 2022 (2)
- May 2022 (4)
- April 2022 (4)
- March 2022 (4)
- February 2022 (14)
- January 2022 (6)
- December 2021 (3)
- November 2021 (4)
- October 2021 (5)
- September 2021 (5)
- August 2021 (6)
- July 2021 (5)
- June 2021 (6)
- May 2021 (6)
- April 2021 (2)
- March 2021 (5)
- February 2021 (2)
- January 2021 (2)
- November 2020 (1)
Continuous Resiliency from Speedscale gives you the power of a virtual SRE-bot working inside your automated software release pipeline. Forecast the real-world conditions of every build, and know you’ll hit your SLO’s before you go to production.
Feed Speedscale traffic (or let us listen) and we’ll turn it into traffic snapshots and corresponding mock containers. Insert your own service container in between for a robust sanity check every time you commit. Understand latency, throughput, headroom, and errors -- before you release! The best part? You didn’t have to write any scripts or talk to anyone!
Automated Traffic Replay for Every Stakeholder:
- DevOps / SRE Pros: Understand if your app will break or burn up your error budget before you release.
- Engineering Leads: Let Speedscale use traffic to autogenerate tests and mocks. Introduce Chaos testing and fuzzing.
- Application Executives: Understand regression/performance, increase uptime and velocity with automation.
Before you go to production, run the projection.