Ahmedabad, India
2010
  |  By Ramya Shah
With VoIP monitoring, you hear about a bad call before anyone opens a ticket. Voice handles trouble worse than most traffic on your network. When a file download drops packets, it just asks for them again. A live call has no time for that. A 2% burst of packet loss, which a download wouldn't notice, is enough for everyone on the call to hear a gap. Most of those problems start on the network path, which you can measure and fix.
  |  By Poonam Lalani
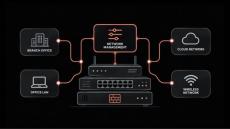
When a branch office can’t reach the ERP system and customer calls start dropping, who gets the call? It’s almost always the network administrator. What that person does the rest of the week is less clear, and a CIO, a CFO and the admin themselves would probably each describe it differently. Part of the reason is how much the network has grown. Ten years ago it was mostly switches, cables and one building.
  |  By Poonam Lalani
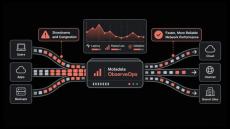
Why does everything crawl at peak hour, even though every switch looks fine? Calls break up and file copies stall. Then the tickets arrive, each one some version of "the network is slow." It's rarely one broken device. A WAN link maxes out for an hour with voice packets queued behind a backup job. Last week's config change hasn't been linked to any of it yet. Network optimization sorts this out one measured step at a time, starting with performance monitoring.
  |  By Ramya Shah
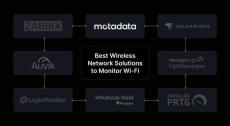
If your Wi-Fi keeps slowing down or dropping connections, checking whether your access points are online won't tell you much. You need to know what's causing the problem, whether it's weak signal strength, overloaded access points, or too many connected devices. Wireless network monitoring tools help you track these issues, monitor access point health, and spot problems before they affect more users.
  |  By Poonam Lalani
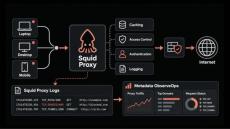
How long does it take your service desk to rule the proxy in or out when a user says a site won't load? The proxy carries every outbound web request in most companies, and it still tends to be checked last. So service desks guess, even though the proxy has already logged what happened to that request. For a lot of those companies, the proxy is Squid. It has cached pages and enforced web policy for close to three decades, and it logs every request it touches.
  |  By Poonam Lalani
Why does the help desk still hear about network problems before the network engineers do, even with every router and switch under monitoring? In most cases the alert does its job, and the hours go into what comes after it. Tracking down who last touched the config takes time, and so does checking the switch's vendor support and how close that branch link is to capacity. Networks also no longer behave like a single system.
  |  By Ramya Shah
NOC monitoring decides how fast a network problem turns into a fix. If your NOC watches the wrong layers, it misses the fault. If it alerts on everything, the real fault gets buried. According to Uptime Institute's Annual Outage Analysis 2026, 57% of operators said their most recent major outage cost more than $100,000. Most teams already collect plenty of data through network monitoring. The hard part is turning that data into a short queue of alerts that the right person acts on.
  |  By Poonam Lalani
When a critical flaw surfaces in the language behind a large share of your web applications, how quickly can your organization name every server that runs it? PHP2Shell puts that question in front of every IT leader who runs PHP. The answer decides how long the business stays exposed. Here's the short version. PHP2Shell covers two flaws in the PHP engine, and either one lets an attacker run code on a web server with no login at all.
  |  By Poonam Lalani
Why does a checkout or login take several seconds when CPU and memory look normal on every server? In microservices, one click can travel through a long chain of components before the user sees a response. Any one of them can hold the request up, and server graphs won't tell you which. Logs show what each service recorded. Metrics give you averages. What's missing is the path one request took and the place it lost time, and Jaeger tracing records exactly that.
  |  By Ramya Shah
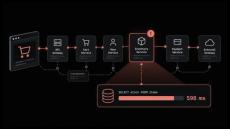
A checkout request leaves the browser and touches seven services before anything comes back. Seven dashboards light up. Every one of them reports a healthy number for its own service, and every one of them is telling the truth about a different slice of the work. Nobody measured the request. That gap is what pushed tracing in beside metrics and logs as a core signal of observability. In this blog, you will: By the end you will open a trace and say where the time went.
  |  By Motadata
A Kubernetes cluster emits more metrics than any team can read. Here is how to pick the ones that actually predict failure. In this video, you'll learn: Contact Us [email protected].
  |  By Motadata
Adding agents to handle rising ticket volume treats the symptom. Deflection asks why those tickets reach an agent at all. In this video, you'll learn: Contact Us [email protected].
  |  By Motadata
Discover the latest log management strategies for 2026 and learn how AI and automation turn raw logs into actionable insights. See how modern log management can reduce investigation time, improve incident response, control costs, and strengthen visibility across hybrid and multi-cloud environments.
  |  By Motadata
In this webinar recording, discover how ServiceOps and ObserveOps connect IT service management with deep observability. Learn how IT teams can identify root causes faster with unified visibility across incidents, metrics, logs, traces, applications, and infrastructure. Don't forget to like, share, and subscribe for more insights on ITSM, observability, AIOps, and IT operations.
  |  By Motadata
AI is transforming ITSM beyond co-pilots with autonomous AI agents that can understand, decide, and act. In this webinar, discover how AI agents are reducing manual workloads, accelerating incident resolution, improving service quality, and enabling intelligent service operations. Learn real-world use cases, key implementation strategies, and how organizations can move from reactive support to proactive, AI-driven IT service management. Watch now to explore the future of smarter, faster, and more efficient ITSM.
  |  By Motadata
Quantum computing is reshaping the future of cybersecurity. In this video, learn what a Cryptographic Bill of Materials (CBOM) is, why it matters for post-quantum security, and how it helps organizations identify vulnerable cryptography, prioritize migration, and improve cryptographic visibility. Perfect for security professionals, DevSecOps teams, IT leaders, and compliance teams preparing for the quantum era.
  |  By Motadata
Alert fatigue is one of the biggest reasons critical incidents get missed. In this video, learn what alert fatigue is, why it happens, and how reducing noisy, repetitive notifications helps IT teams respond faster to the alerts that actually matter. Whether you're an IT operations professional, SRE, DevOps engineer, NOC analyst, or IT manager, this video explains alert fatigue in simple terms and shares practical ways to reduce alert noise, prioritize critical issues, and improve incident response.
  |  By Motadata
In this video, you'll learn what a Configuration Item (CI) is, how it forms the foundation of a CMDB, and why connecting CIs helps IT teams understand dependencies, improve visibility, and resolve incidents faster. Discover how CIs transform scattered asset data into a complete, connected view of your IT environment. Whether you're an IT Manager, IT Administrator, Service Desk Analyst, ITSM Professional, Infrastructure Engineer, or IT Operations Leader, this video explains why Configuration Items are essential for effective IT Service Management.
  |  By Motadata
A website can look healthy on your dashboard and still fail when customers try to use it. So how do you catch problems before anyone notices them? In this video, you'll learn what synthetic monitoring is, how it works, and why IT teams use it to detect website and application issues before they impact real users. Discover how automated user journeys help you monitor availability, performance, and critical business transactions 24/7.
  |  By Motadata
A self-service portal is designed to reduce IT support tickets by enabling employees to solve common issues on their own. But if self-service is supposed to improve efficiency, why do so many portals remain unused while help desk queues continue to grow? In this video, you'll learn what a self-service portal is, why many organizations struggle with low adoption, and the three key factors that determine whether your portal actually reduces ticket volume.
  |  By Motadata
Log management can be seen as both challenge and as an opportunity, the key is to derive intelligence out of it.

Motadata is an IT monitoring and management software that derives business insights by real-time processing, correlation and intelligent visualization of IT network and security information data. It can collect data from multiple sources, in any format, and analyze it for insights. It unifies traditionally separate IT monitoring data from network devices, server instances, virtual machines, cloud deployments, applications and web servers of NOC and log analytics from SOC in a single powerful platform.

With the increasing complexity of today’s heterogeneous networks, it has become imperative for organizations to invest in a robust IT Operations platforms that not only Monitors, Tracks, Analyses but also Resolves issues even before they impact the end users. Motadata offers a unified product suite consisting of Network Monitoring, Bandwidth Monitoring, Log Management, Configuration Management, Asset Management, Helpdesk, Servicedesk & more under one single platform.

Unified Product Suite for IT Operations and Big Data Analytics:

  • IT Service Management Platform: The ITIL Compliant ITSM platform organizes information, automates workflow, eliminates manual/back-end complexities and encourages self-service for maximum productivity and superior user experience for servicedesk or helpdesk.
  • Infrastructure Intelligence Platform: Motadata’s Infrastructure Intelligence Platform (IIP) proactively monitors & optimizes all network devices, servers, and applications across IT infrastructure to manage network for fault and performance for maximum uptime with network monitoring.
  • Data Analytics Platform: Analyse your machine data to identify trends and unleash undiscovered insights from the vast untouched machine data with Elastic search precision with our bandwidth monitoring & log management in data analytics platform.

Complete Visibility Across Your Dynamic Infrastructure with Wholesome Network Monitoring.