Operations | Monitoring | ITSM | DevOps | Cloud

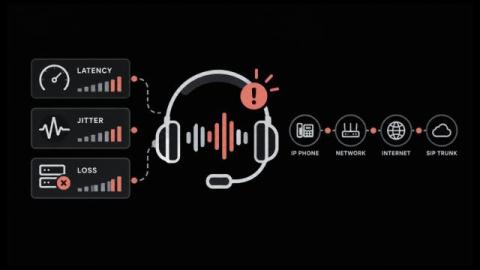
VoIP Monitoring: Metrics, Tools and How to Fix Poor Call Quality

With VoIP monitoring, you hear about a bad call before anyone opens a ticket. Voice handles trouble worse than most traffic on your network. When a file download drops packets, it just asks for them again. A live call has no time for that. A 2% burst of packet loss, which a download wouldn't notice, is enough for everyone on the call to hear a gap. Most of those problems start on the network path, which you can measure and fix.
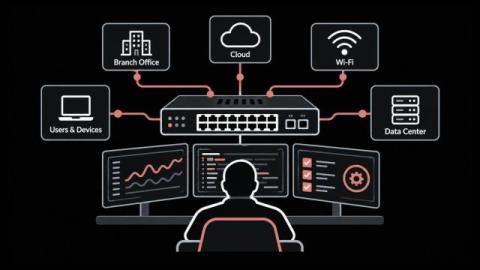
What Does a Network Administrator Do? Skills and Faster Fixes with Network Observability

When a branch office can’t reach the ERP system and customer calls start dropping, who gets the call? It’s almost always the network administrator. What that person does the rest of the week is less clear, and a CIO, a CFO and the admin themselves would probably each describe it differently. Part of the reason is how much the network has grown. Ten years ago it was mostly switches, cables and one building.

Network Optimization Guide With 10 Top Ways to Cut Slowdowns and Downtime

Why does everything crawl at peak hour, even though every switch looks fine? Calls break up and file copies stall. Then the tickets arrive, each one some version of "the network is slow." It's rarely one broken device. A WAN link maxes out for an hour with voice packets queued behind a backup job. Last week's config change hasn't been linked to any of it yet. Network optimization sorts this out one measured step at a time, starting with performance monitoring.

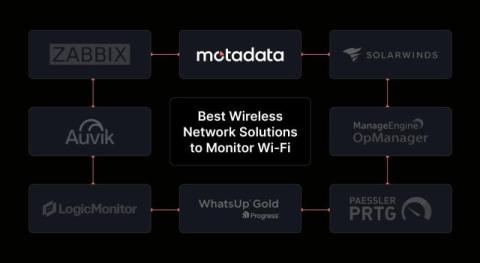
8 Best Wireless Network Solutions to Monitor Wi-Fi in 2026

If your Wi-Fi keeps slowing down or dropping connections, checking whether your access points are online won't tell you much. You need to know what's causing the problem, whether it's weak signal strength, overloaded access points, or too many connected devices. Wireless network monitoring tools help you track these issues, monitor access point health, and spot problems before they affect more users.

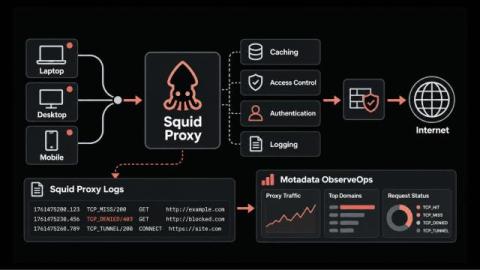
What Is Squid Proxy and How to Keep It Fast, Secure and Observable

How long does it take your service desk to rule the proxy in or out when a user says a site won't load? The proxy carries every outbound web request in most companies, and it still tends to be checked last. So service desks guess, even though the proxy has already logged what happened to that request. For a lot of those companies, the proxy is Squid. It has cached pages and enforced web policy for close to three decades, and it logs every request it touches.

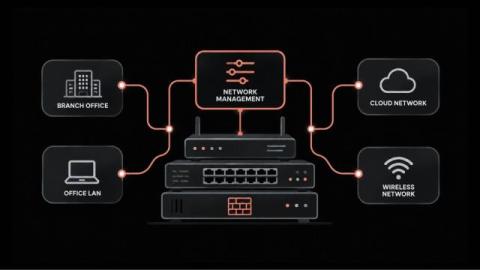
What Network Infrastructure Management Involves and How It Keeps Every Site Running

Why does the help desk still hear about network problems before the network engineers do, even with every router and switch under monitoring? In most cases the alert does its job, and the hours go into what comes after it. Tracking down who last touched the config takes time, and so does checking the switch's vendor support and how close that branch link is to capacity. Networks also no longer behave like a single system.

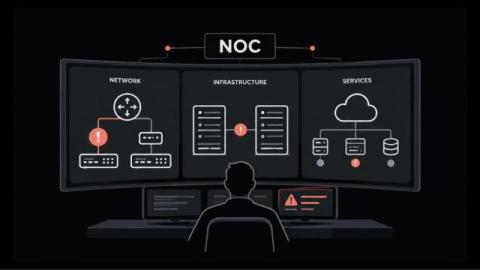
NOC Monitoring: What a Network Operations Center Tracks and How

NOC monitoring decides how fast a network problem turns into a fix. If your NOC watches the wrong layers, it misses the fault. If it alerts on everything, the real fault gets buried. According to Uptime Institute's Annual Outage Analysis 2026, 57% of operators said their most recent major outage cost more than $100,000. Most teams already collect plenty of data through network monitoring. The hard part is turning that data into a short queue of alerts that the right person acts on.

How to Patch PHP2Shell Across Every Server and Prove Each Fix to Auditors

When a critical flaw surfaces in the language behind a large share of your web applications, how quickly can your organization name every server that runs it? PHP2Shell puts that question in front of every IT leader who runs PHP. The answer decides how long the business stays exposed. Here's the short version. PHP2Shell covers two flaws in the PHP engine, and either one lets an attacker run code on a web server with no login at all.

What is Jaeger Tracing and How does It Locate Slowdowns Across Microservices

Why does a checkout or login take several seconds when CPU and memory look normal on every server? In microservices, one click can travel through a long chain of components before the user sees a response. Any one of them can hold the request up, and server graphs won't tell you which. Logs show what each service recorded. Metrics give you averages. What's missing is the path one request took and the place it lost time, and Jaeger tracing records exactly that.

What is Distributed Tracing? How a Request Becomes a Trace

A checkout request leaves the browser and touches seven services before anything comes back. Seven dashboards light up. Every one of them reports a healthy number for its own service, and every one of them is telling the truth about a different slice of the work. Nobody measured the request. That gap is what pushed tracing in beside metrics and logs as a core signal of observability. In this blog, you will: By the end you will open a trace and say where the time went.

How to View, Filter and Manage Docker Logs Without Losing Them or Filling the Disk

Why does a container fail, restart and leave behind almost nothing useful when you go looking for the cause? Docker logs are the first place most engineers check during an incident, and they work well right up until the output goes missing. Sometimes it is buried under thousands of lines, and sometimes it is deleted along with the container. The docker logs command itself is simple. The difficulty comes from the settings around it, starting with the logging driver and where its files live on disk.

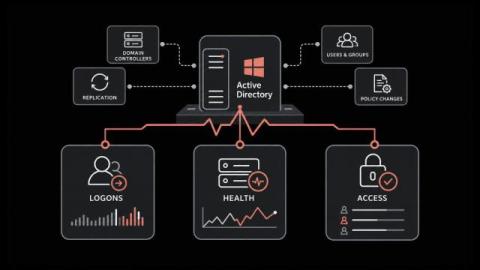
What to Monitor in Active Directory to Keep Logons Fast and Access Under Control

Why do logons crawl at one branch while headquarters is fine, or an admin group gain a member nobody approved, and no alert says a word? Trace any of those back far enough and you usually reach Active Directory. Since email, VPN, file shares and line-of-business software all lean on it for credentials, a directory fault rarely looks like itself and tends to show up as a network outage or a bug in some other application. Most of these faults creep in.

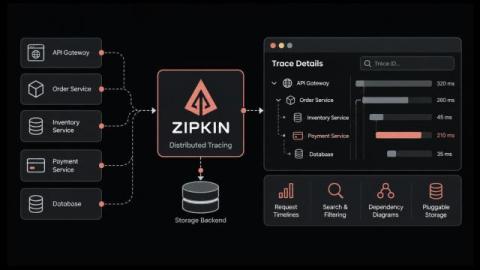
What is Zipkin and How does Distributed Tracing Speed Up Incident Resolution

If a checkout slows down or an API call fails, why can the cause stay hidden for so long while every service dashboard looks fine? One customer click in a microservices setup may hit a gateway and a few backend services first, then a queue or a database. Every hop logs its own events, yet none of those logs points back to the original request. Distributed tracing was created to solve exactly this. Zipkin arrived early, as one of the first open-source tracers.

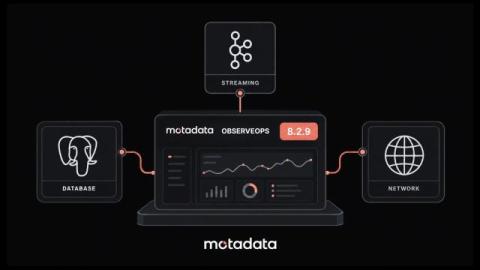
What's New in Motadata 8.2.9 as ObserveOps Expands Database, Streaming and Network Coverage

How often does a lagging replica or a bad network link reach users before your monitoring flags it? The problem grows when every layer has its own tool. Warning signs then show up in different places, often too late to act on. Motadata 8.2.9 came out on October 5, 2026, with eight updates to Motadata ObserveOps. Four of them focus on the network. The other four deal with databases, data streaming, alerting and SEBI compliance reporting. A few add support for technologies Motadata did not cover before.

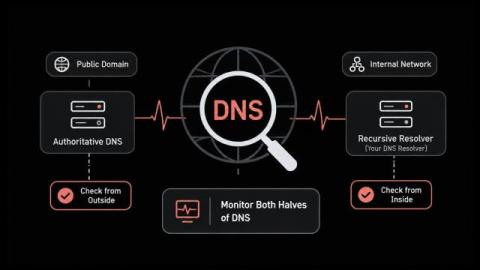
DNS Monitoring: What to Track and Where to Watch It From

DNS monitoring asks your name servers the same question on a timer and checks the answer that comes back. Most teams aim it at their public domain and stop there. That covers half the problem. Your public domain and your internal resolver fail in different ways. A check from outside the building never sees the second one. In this blog, you'll see: By the end you'll know which half of your DNS nobody is watching. A DNS check sends a query and reads the reply. The reply can fail three ways.

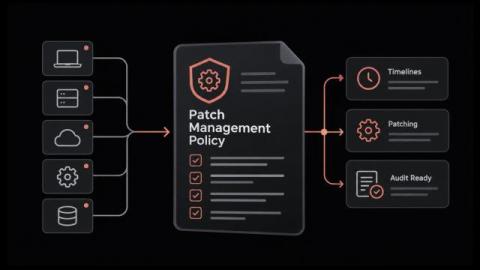
What a Patch Management Policy Should Contain to Keep Systems Secure and Audit-Ready

Who decides how fast a critical patch goes out, and who signs off when a production server can't be restarted? For many IT groups, the answer is a mix of one senior admin's judgment, an old ticket and a shared spreadsheet. It holds up fine right until an auditor asks for proof, or that admin leaves. A written policy replaces that guesswork with rules people have agreed to. Owners are named, deadlines are fixed, and there's a plan for the system that can't be patched on time.

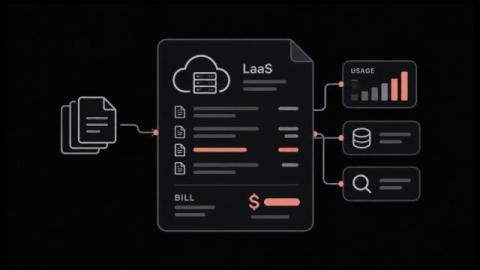
Logging as a Service (LaaS): What It Costs and When It Fits

Logging as a Service moves your log management to a provider. They collect, parse, store and search your logs for a monthly fee. The fee is where it goes wrong. Providers meter five different things, and the one written into your contract decides whether ordinary growth doubles your bill. In this blog, you'll see: By the end you'll know which meter your workload lands on. Logging as a Service is a cloud-delivered model for collecting and searching logs.

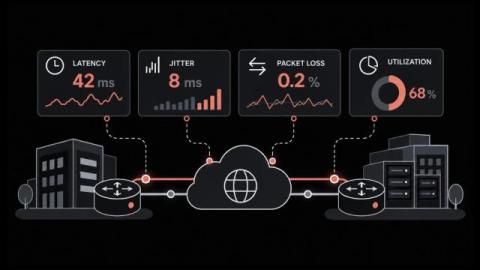
WAN Link Monitoring for Faster Branch Troubleshooting

Why do users at a branch complain about choppy calls and stalled apps when every WAN circuit on the dashboard still shows up? A link can be reachable without being healthy. Delay and packet loss can rise for hours on a live circuit, and a simple up-or-down check will report nothing unusual the whole time. WAN link monitoring checks the quality of each site-to-site connection by having routers send their own test packets and time the replies.

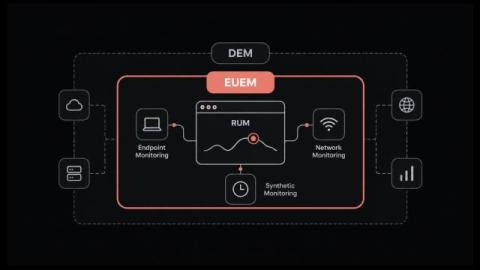
What is End User Experience Monitoring (EUEM)? How It Relates to RUM and DEM

Why do tickets about a slow application keep arriving while every server, link and service check reports normal? That mismatch is the problem end user experience monitoring exists to solve. A healthy server is one thing, but the business notices something else: whether people can finish their work or complete a purchase without delays or errors. Monitoring in most IT operations groups was built to watch the systems from the inside, so it reports CPU load, memory and uptime.

How Alert Suppression Pauses Alerts During Planned Work Without Losing Visibility

How many pages did your on-call engineer get during the last planned firmware upgrade on a core switch? The device stops responding and every dependent check fails. Soon the on-call phone is buzzing with alerts for a change that was approved last week. Alert suppression is a time-limited pause on alerts for a condition you already know about, such as planned work or an issue under investigation. And what is alert suppression from the engineer's side of the console?

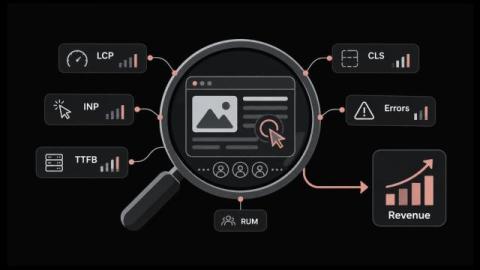
RUM Metrics That Matter for User Experience and Revenue

Why does a page that scores well in testing still draw complaints from customers about slowness? A lab test runs on one fast machine over a stable connection. Customers use older phones, congested mobile networks and browsers loaded with extensions, so their experience can only be measured on their own devices. Real user monitoring captures that experience, and it produces a long list of measurements.

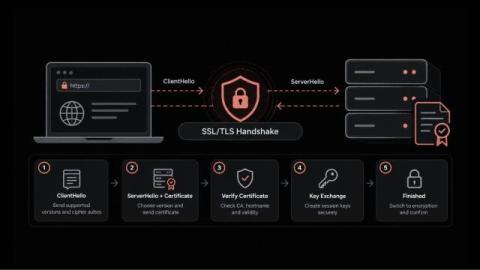
SSL Handshake Guide Covering Each Step and the Fixes That Prevent Outages

Why would a website that passes every uptime check still show customers a security warning? In most cases, the server is running and the network is healthy. The failure happens earlier, during the brief exchange in which the browser and the server agree on how to communicate securely. That moment is the SSL handshake. If it goes wrong, users get an error page while your dashboards stay green. Maybe a certificate expired; maybe a routine change left both sides on different protocol versions.

What Is RMM (Remote Monitoring and Management)?

RMM lets one small team look after thousands of machines nobody will ever physically touch. It grew up inside managed service providers. The whole category runs on agent-based monitoring, which means a small program sits on every endpoint and phones home on a schedule. That agent is also why attackers have taken such an interest lately. In this blog, you'll see: By the end you'll know what the category covers and where it stops. RMM stands for remote monitoring and management.

7 Best SQL Server Monitoring Tools for 2026

A slow query can affect an application before the database team knows what is causing it. A blocked session, failed job, or growing database file can create more problems if no one spots it early. That’s where SQL Server monitoring tools come in. They help you track database performance, find slow queries, monitor waits and locks, and see what changed before a problem occurred.

7 Best Network Sniffing Tools for 2026

Ever wondered what is actually using your network when it suddenly slows down? It could be a device sending too much data, a backup running at the wrong time, or an application taking too long to respond. Without visibility into network traffic, finding the real cause can take hours. That’s where network sniffing tools can help. They let you inspect network traffic, capture packets, and see what is happening between devices, servers, and applications.

9 Best Help Desk Software for Small Business in 2026

Why is your network slow or failing even when your devices seem to be working? Finding the cause of a network problem can take time. You may need to check packet loss, trace the network path, find a busy link, or see why an application is not connecting. A simple ping test can tell you whether a device responds, but it cannot always show what is causing the problem. Network diagnostic tools help you narrow down the cause by checking devices, ports, routes, packets, traffic, and link performance.

8 Best Network Diagnostic Tools for 2026

If your team manages a network across several offices and cloud systems, finding the cause of a slow or failed connection can take time. You may run into problems such as: As your network grows, a quick test from one computer may not show where the problem started or when it first appeared. Network diagnostic tools help you check devices, ports, routes, packets, and link performance.

10 Best Database Monitoring Tools for 2026

If your company relies on multiple databases and applications, keeping track of database performance can become difficult. You may face challenges such as: As your database environment grows, identifying the cause of performance issues becomes harder without the right monitoring in place. I get why database monitoring tools have become an important part of managing database performance. They help you monitor database activity, spot performance issues, and find what is causing a slowdown.

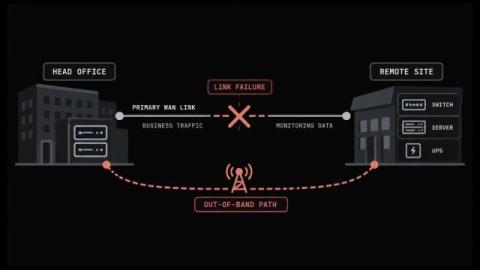
Remote Infrastructure Management: How to Run Sites With No IT Staff

Most IT teams now look after more sites than they have people to visit. Remote infrastructure management covers that gap, and it works differently from the IT infrastructure management you run inside a building where somebody can walk over and look at whatever broke. The technology rarely causes the trouble. Trouble starts when a site goes quiet and there's nobody standing there to look at it.

ISO 27001 Compliance: What Auditors Require and When You Need the Certificate

ISO 27001 compliance means running your information security the way ISO/IEC 27001 sets out. Most teams meet the standard when a customer sends over a security questionnaire. It lands as one more line on a cybersecurity compliance checklist. That framing hides the decision underneath it. You can follow the standard without ever being certified against it. The two routes cost very different amounts. In this blog, you will: You will finish able to decide whether you need the certificate, and what it takes.

10 Best AI Help Desk Software for 2026

Are your support teams spending too much time handling tickets and answering repetitive questions? As support requests increase, teams spend more time reading conversations, assigning tickets, finding relevant information, and preparing replies. These tasks can take attention away from complex issues that require human support. AI help desk software can help reduce this workload. It can answer common questions, summarize tickets, suggest replies, route requests, and assist with support tasks.

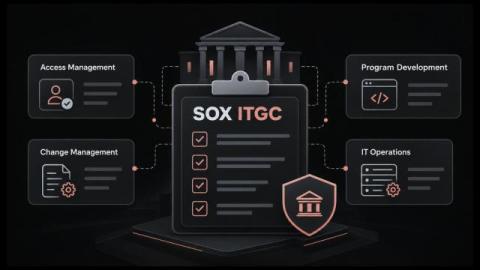
SOX ITGC Controls Checklist for IT Service Management and Year-Round Audit Readiness

How much of your SOX audit season goes into rebuilding proof of work that was already done? Access was approved, the change went through review, the backup ran, yet the evidence lives in email threads, chat messages and a spreadsheet someone updated last quarter. When an auditor asks for a complete list of production changes, IT staff have to pull records from several places against a deadline.

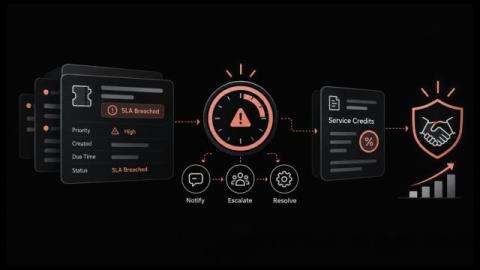
What Happens When an SLA is Breached and How to Recover Customer Trust

What does your organization owe a customer when a priority ticket misses its resolution target by forty minutes? For most service providers and internal service desks, the answer stays unclear until the customer asks for a credit or a manager asks why the monthly SLA report shows a miss. By then, the facts that decide the outcome, such as when the clock started, whether it paused and who was told, are scattered across tickets, emails and chat threads.