Operations | Monitoring | ITSM | DevOps | Cloud

Monitor Databricks with Datadog

Earlier in this series, we covered key metrics for monitoring performance in Databricks and discussed Databricks’ native resources for accessing those metrics and other key observability data, such as logs and data lineage. In this post, we’ll cover using the Databricks integration to bring that data into Datadog and monitor your Databricks analytics and AI/ML workloads alongside the rest of your end-to-end data pipelines and distributed infrastructure. We’ll show you how to.
Databricks' native monitoring resources

In the first part of this series, we cataloged key metrics for Databricks data engineering, analytics, and Model Serving workloads. In this post, we’ll discuss how to collect those metrics and other telemetry data from Databricks and Apache Spark, which powers Databricks under the hood. We’ll cover collecting and querying telemetry data via system tables, as well as the other primary sources of visibility into.

Monitor warehouse data quality beyond pipeline health

You get a Slack message from the VP of Sales: They have asked an AI agent connected to Snowflake for the past quarter’s revenue and the numbers look wrong. First, you verify the agent’s query and, when that looks fine, check the pipelines that populate the underlying table. All jobs completed, the data is recently refreshed. Then it’s time to check the logs for errors. Nothing.

Extend Datadog RUM and Product Analytics to Shopify and Salesforce

Many revenue-critical interactions, such as ecommerce checkouts and customer portals, run on Shopify and Salesforce. But engineering teams have less control over the frontend runtime on these platforms, and this lack of control can make user monitoring difficult to implement and maintain. These monitoring limitations can leave gaps in visibility across important parts of the user journey.

Using TypeSafe's Jev for evals in Datadog Agent Observability

TypeSafe AI released Jev in September 2026 to do one thing: make decisions. Give it a state (a string or a JSON object) plus a set of typed questions, and it returns typed answers with probabilities. It never explains itself, and that constraint is the whole idea. Evaluation pipelines have spent the last two years asking text generators for yes/no verdicts, wrapping the reply in a JSON schema, and paying generation prices for what amounts to a single bit.

Configure RUM SDKs remotely from Datadog

Datadog Real User Monitoring (RUM) SDK settings live in your application code, so changing how the SDK collects RUM data has traditionally required shipping a new application version. These configuration changes can include adjusting sampling rates, enabling Session Replay, or changing which events the SDK collects. For mobile teams, this means that updates often sit in app store review for days or weeks before users start adopting the new version. Full user adoption can take weeks or months longer.

Find answers in your logs faster with Datadog's Tap to Parse

Logs are easiest to investigate when the values that matter are already captured as attributes. When those values are buried in a log message, even a straightforward question such as filtering on a status code, graphing the duration of a request, or following a unique transaction across a set of logs requires writing complex regular expressions or Grok patterns.

Cut AI agent cost and improve accuracy with Code Execution in the Datadog MCP Server

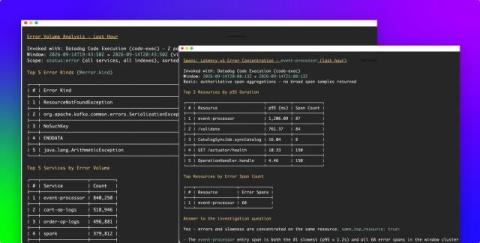
Observability investigations rarely follow a straight line. A latency question might cause an AI agent to start with a metric, pivot into traces, compare a deployment window, and finish by reducing thousands of logs to a few patterns. Each individual query is easy, but propagating context throughout an entire investigation can be tricky and expensive.

When users don't click thumbs up: Inferring agent feedback from Datadog telemetry

Collecting high-quality user feedback on agents, like from thumbs-up or thumbs-down buttons, is an important part of agent development. User feedback is needed for everything from basic gut checks on whether your agents are behaving well to planning and creating robust eval sets. It’s a critical part of Datadog’s Agent Observability, which provides explicit end-user feedback features for collecting and analyzing it.