Operations | Monitoring | ITSM | DevOps | Cloud

Best Storage Monitoring Software: 10 Tools Compared

Storage rarely fails loudly. A pool fills. Latency climbs on one LUN. The first to notice is a user whose application timed out. The best storage monitoring software catches it earlier. It watches capacity, IOPS, latency and drive health across your arrays, which is what storage resource monitoring is for. In this blog, you will see: By the end you will know which one fits. Storage monitoring software tracks the health, capacity and performance of your IT storage.

What is Network Visibility and How do you Achieve It?

What happens when the segment that failed was never reporting to anything? The incident stops being a diagnosis and turns into a search, and the cost of that search lands on the business rather than on the network team. Network visibility measures how much of your environment can account for itself under pressure. Most teams assume their coverage is broadly complete because their monitoring platform reports thousands of healthy objects.

10 Top Hyper-V Management Tools for Single Hosts, Clusters and Hybrid Infrastructure

An application slows down every month-end. You open Hyper-V Manager, the virtual machine looks healthy, and the ticket closes without a cause. Next month it happens again. Native consoles show live state and keep no history behind it, so nobody can prove whether the fault was the guest, the host, or a storage path shared with nine other workloads. That gap sets what a Hyper-V deployment costs to run, measured in unplanned downtime and in engineering hours spent guessing. This guide covers.

Top 9 AIOps Tools to Cut Alert Noise and Speed Up Root Cause Analysis

During your last major outage, several monitoring tools raised alerts and every one of them was correct. What none of them could say was which alert explained the others, so the opening stretch of the incident went on assembling a picture the systems already held between them. That time shows up in your availability numbers, your SLA credits, and your board report. AIOps platforms close that gap by grouping the alerts caused by the same failure and handing your team one incident with context attached.

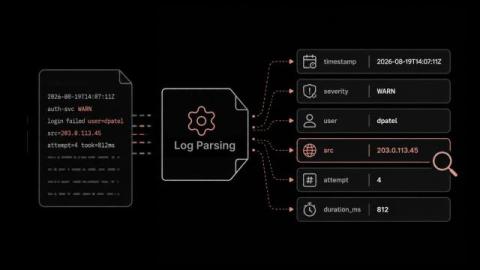
Log Parsing: How Raw Logs Become Searchable Fields

A log file full of raw text is close to useless when an incident is running. You can grep it. What you cannot do is ask how many failed logins came from one address in the last ten minutes. That is usually the question in front of you. Log parsing closes that gap, and a log parser is the software that does the work. In this blog, you will see: Log parsing is the process of reading a raw log line and extracting its values into named, structured fields.

How Does a Telemetry Pipeline Work?

Telemetry passes through several stages before anyone can use it. Searching it, charting it, and alerting on it all come later. Each stage makes one decision about the data. Their order separates a pipeline that saves money from one that adds a hop. Most teams meet this layer late, usually after a monitoring bill jumps. Here is how a telemetry pipeline works, stage by stage: By the end you can map your own telemetry flow against the five stages, and see which one is costing you.

How to Survive SOX Compliance Season Without Rebuilding Your Records

Why does SOX season turn into a hunt for screenshots and forwarded approval emails? The controls were almost certainly running all year. The record of them running is scattered across a ticketing tool, an identity directory, a backup console, and someone's inbox. SOX compliance puts financial reporting under a legal standard, and the IT team ends up carrying a large share of the proof. Change approvals, user access lists, backup jobs, and batch schedules all become audit evidence.

What Backup Monitoring Software Should Track to Protect RTO and RPO

How many backup jobs completed successfully in your environment last night, and how many of those systems could you bring back inside the window the business agreed to? Most backup consoles answer the first question well. They report job status, completion time and volume written, then roll it into a reassuring compliance summary. The second question needs different evidence, usually missing from that screen. The distance between those answers shows up during the recovery attempt.

A Practical ClickHouse Monitoring Guide Built Around Failure Modes

Why does a ClickHouse cluster report every node as healthy while inserts start failing and dashboards go stale? Most often the failing subsystem was never represented in the metrics anyone had on screen. A node answers its health check while its replication queue has been growing for hours. ClickHouse breaks in specific, repeatable ways. Parts accumulate faster than background merges can consolidate them. Coordination drops quorum and every replicated table quietly turns read-only.

How Network Documentation Software Keeps Network Diagrams Current

When did anyone last open your network diagram and trust what it showed? A diagram drawn in a static drawing tool is accurate on the day it is saved. One quarter, two circuit upgrades and a hardware refresh later, it describes a network that no longer exists. Nothing warns you that this has happened. The file still opens, still prints, and still gets attached to change requests, which is what makes it risky during an incident.