Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on Containers, Kubernetes, Docker and related technologies.

Why haven't UK organizations moved off the hyperscalers?

Two-thirds of UK IT leaders say they would switch cloud providers to take back control. Fifteen percent have actually done it. That is the headline from Civo's Digital Sovereignty Revolution 2026, a survey of 1,000 UK IT leaders. The intent is loud and getting louder. The movement is almost silent. It would be easy to call that apathy. It is not. UK organizations are staying on hyperscale infrastructure they no longer fully trust for four very specific reasons. Three of them are structural.
Plug Qovery Into the Kubernetes Cluster You Already Run

BYOK on EKS, GKE and Kapsule now runs through the Qovery Operator: install it once with Helm on a cluster you already run, and deploy Qovery's component updates from the Console. Now in Preview, for clusters without cert-manager, ExternalDNS or Envoy Gateway. Pierre is a staff engineer on the Qovery platform team. He works on the Qovery Operator and the platform catalog that install and update Qovery on Kubernetes clusters.

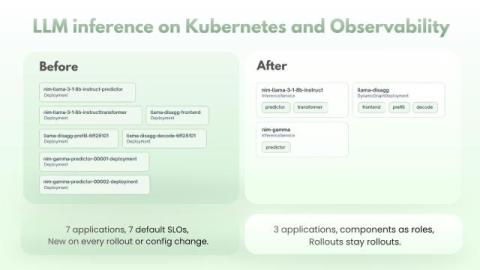
LLM inference on Kubernetes and observability

Running an LLM on Kubernetes is rarely just a Deployment with vLLM in it anymore. A whole layer of frameworks and operators has grown up for it: KServe, NVIDIA Dynamo, Ray Serve, Kthena, llm-d. Each one adds its own custom resource that describes a model deployment, with routing, autoscaling and the split of a model across pods built in, and each one turns that resource into ordinary Kubernetes objects in its own way.

What Is Agentic Operations and Why Ops Teams Are Adopting It

AI coding tools have changed how fast software ships. They haven’t changed who runs it. Every extra release, alert and incident still lands on the same SRE, Platform and DevOps teams, and 78% of technology leaders report more incidents since adopting AI-generated code. So operations teams are turning to agents too. Six in 10 enterprise leaders are piloting, deploying or evaluating automated incident response, according to Caylent.

Can One Building Hold a Country Full of Experts? | Civo Navigate London 2026

AI factories don't sell floor space. They produce tokens, the currency of intelligence, and every jump from Hopper to Vera Rubin packs in up to 4x the density. Training wants one giant site. Inference wants to be as close to you as physics allows. So the panel maps out what comes next: edge data centres of 5 to 50MW, handing work between your watch, your phone and the cloud at the lowest possible latency.
Featured Post

From Signal to Action: Instrumenting Decision Latency in Kubernetes Incident Response

An alert fires. Checkout latency has crossed an error-budget threshold, the Prometheus rule is correct, and the page reaches an on-call engineer in under a minute. Then recovery stalls while the responder works through different questions. Which rollout changed? Who owns the failing path? Is the payment dependency degraded? Is rollback safe? Who needs to approve it? How do we know the system recovered?

Britain's schools are adopting AI, but who controls the infrastructure behind it?

Four in five UK teachers now use artificial intelligence for work. That is an extraordinary level of adoption for a technology that, just a few years ago, most people outside the technology industry had barely encountered. But there's another figure from the same research that I find considerably more interesting. Only 35% of teachers using AI say they're actually working fewer hours because of it.

The Migration Takes 2 Weeks. Deciding to Do It Takes 6 Months. (Webinar Replay)

Replay and recap of our October 20 live session: why the decision to migrate takes longer than the migration itself, the five human blockers behind it, two customer migrations, and three ways to cut decision time. Chapters, timestamps and key takeaways. Romaric founded Qovery to make Kubernetes accessible to every engineering team. He writes about platform strategy, developer experience, and the future of cloud infrastructure.

Removing decommissioned clusters from Icinga for Kubernetes

Clusters get retired. A test cluster is torn down, a workload moves to a new environment, a provider contract ends. Icinga for Kubernetes does not know about any of that. Since v0.3.0, several clusters can write into one shared database, and Icinga for Kubernetes Web shows them side by side. But stopping or uninstalling the daemon for a cluster leaves all of its data in place.

Let's Encrypt Is Shortening Certificate Lifetimes

Let's Encrypt is cutting its certificate lifetimes in half, from 90 days down to 45 days by 2028. If your team still has a calendar reminder that says "renew the certs," this is the nudge to finally retire it. The change isn't purely a Let's Encrypt decision. It's part of an industry-wide shift driven by the CA/Browser Forum, and every publicly trusted certificate authority is heading the same direction.