Apache Kafka simply explained
Aiven for Apache Kafka® Learning Apache Kafka doesn’t have to be difficult. Read on to get a friendly explanation of the Apache Kafka fundamentals.


So here we are…the final chapter. In Part 2 of this series, we started to drill down into some of the concepts that make Kafka great. We concluded that although terminology between MQTT and Kafka was similar (for example topics), they behaved quite differently under the hood. We also took a brief overview of Kafka Connect and how we can use some of the enterprise connectors to stream our data to other platforms. Yet we did learn that Kafka does have some shortfalls.
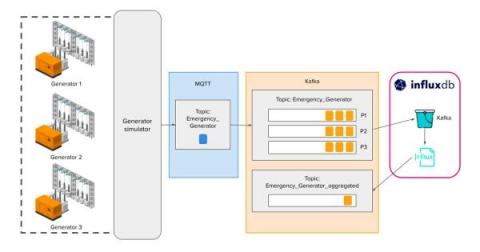
Hulu, the entertainment streaming platform, needed a solution to scale up its internal application and infrastructure monitoring platform as it grew beyond 1 million metrics per second. The solution it created combines two open source tools— InfluxDB, a time series database, and Kafka, an event-streaming platform. It’s not just global enterprises like Hulu that have access to world-class tools and infrastructure to achieve their business goals.
What if Aiven doesn’t provide the Apache Kafka® connector you want? Read on to learn how to use an external connector, to gather Twitter messages into Kafka.
We noticed this new announcement for Kafka users which may be worth looking into: “Instaclustr is pleased to announce the immediate availability of a new Kafka add-on, Karapace Schema Registry, in public preview, on our managed platform. This follows our earlier announcement of Karapace as part of our comprehensive Apache Kafka support solutions in mid March.