Operations | Monitoring | ITSM | DevOps | Cloud

AI agent cost: what agents really cost to run

AI agent cost in 2026 is mostly a consumption bill, not a subscription. Running an agent costs anywhere from fractions of a cent for a simple routed task to $5 or more for a complex multi-step job, because one request can trigger 3 to 10 model calls behind the scenes. Average production deployments land between $3,200 and $13,000 per month in operational spend. Here is where that money actually goes.
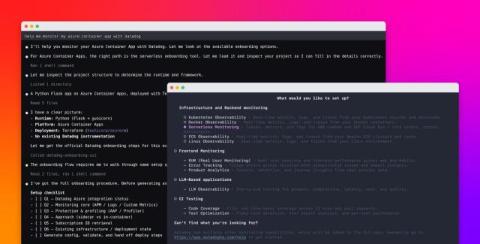
Instrument serverless apps with agentic onboarding

Serverless platforms like AWS Lambda, Google Cloud Run, and Azure Container Apps let teams run applications without managing infrastructure. However, getting full visibility into those workloads has traditionally required a lot of manual setup. A single team may deploy serverless applications across multiple clouds by using tools such as Terraform, AWS SAM, AWS CDK, and the Serverless Framework. Each of these platforms, runtimes, and deployment tools requires its own instrumentation steps.

Best AI Image Generators (2026)

If you still think that creating high-quality images must take a lot of time and resources, think again, because in 2026, that is no longer the case. Now, AI image generators can instantly help you turn simple ideas into impressive visuals in just a few seconds. It doesn't matter if you want to create content for social media, design more complex marketing materials, or just bring your most random ideas to life; there's probably an AI image generator that can help you achieve exactly what you need.

From Incident Data to Operational Knowledge: A Safer Role for Generative AI in IT Ops

IT operations teams produce an enormous amount of information. Alerts, logs, incident messages, deployment records, support tickets, runbooks and post-incident reviews all contain operational knowledge. The problem is that much of this knowledge remains fragmented and difficult to reuse. Generative artificial intelligence can help organise and transform this information, but its safest role is not unrestricted control over production infrastructure. Its strongest initial use cases involve reading, summarising, classifying and drafting information for an engineer to review.

What are AI tokens? The unit your AI bill is written in

AI tokens are the small chunks of text, roughly four characters or three quarters of a word each, that language models read and generate. Every prompt and every response is measured in tokens, and AI providers bill per million of them. That makes the token the base unit of AI spend: 1,000 tokens is about 750 words, and every AI feature you ship is a token meter running.

Ai4 2026: Measuring AI spend is solved. Now it's time to prove its worth.

CloudZero had a full team on the ground at Ai4 in Las Vegas during the first week of August 2026. The team included CTO Erik Peterson, who spoke on a panel about AI cost economics. The same problem surfaced everywhere we went: teams can see what they’re spending, but not whether it’s working. DIY cost tooling that fails time and time again, agent sprawl, and a widening gap between finance and engineering kept coming up throughout the week.

AI-Related Outages Are Reshaping On-Call in 2026

AI-related outages just moved from a fringe worry to a mainline reliability problem, and the on-call rotation is where that shift lands first. A new StackGen analysis of nearly 178,000 public status-page records found that incidents disclosed by AI model and AI application companies now account for more than one in ten reported outages, a sixfold jump from 1.7 percent in 2023 to 10.7 percent so far in 2026.

Inference Optimization Techniques. Ray vs. vLLM vs. KubeRay

Serving large language models at scale is fundamentally a distributed systems problem. A single GPU, or even a single node, is rarely enough once you need multiple models, multiple replicas, tensor-parallel sharding across GPUs, or high-availability rollouts. Kubernetes solves general container orchestration well, but it has no native concept of a GPU-aware, actor-based compute cluster.

GPU Cloud security: Isolation, multi-tenancy, and protecting sensitive training data

GPU cloud security tends to get discussed as if it's the same problem as general cloud security. It isn't. GPUs sit between processes in ways CPUs don't. Training data passes through them in patterns that create specific exposure. Model weights derived from sensitive data are themselves sensitive material in ways most procurement processes don't recognize. And the multi-tenant nature of public GPU cloud creates failure modes that don't exist in CPU-only environments.