Operations | Monitoring | ITSM | DevOps | Cloud

Creating a private 5G network

Private 5G networks are dedicated cellular systems delivering ultra-reliable low-latency communication, massive IoT connectivity, and customized security for enterprises undergoing digital transformation. Private 5G subsumes advantages of both public and non-public networks, offering unified connectivity, optimized services, and customized security within a defined area.
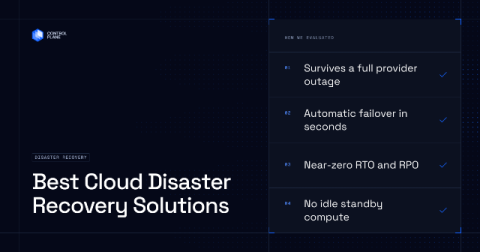
Best Cloud Disaster Recovery Solutions for 2026

Most disaster recovery plans are designed to survive infrastructure failures — a zone goes down, a region becomes unavailable — but assume the cloud provider itself stays up. That assumption fails more often than engineering teams expect, and when it does, the gap between a team that keeps running and a team writing incident reports isn’t luck: it’s whether DR was an architectural default or a runbook nobody has tested.

AI Agent Infrastructure: Where to Run Agents in Production

Run production AI agents on infrastructure with hardware-level isolation, sub-second sandbox restarts, and a compliance posture that already covers PCI DSS, HIPAA, and GDPR, so a single misbehaving agent can’t touch another workload or your audit trail. Control Plane runs every agent workload in a Kata Containers sandbox on a per-workload Firecracker microVM, with Capacity AI packing resources and scaling workloads dynamically to cut compute cost 30-50%.

How to Make an Email Without a Phone Number with Internxt Mail

Creating an email account usually seems simple until you’re asked for a phone number. If you’d rather keep your number private, don’t have access to one, or simply want to keep your accounts separate, you may be wondering if there’s another option. The good news is that Internxt lets you create an account without phone verification with an Ultimate Internxt plan, or create temporary emails for free with no phone number or other personal details required.

Introducing the Harness Connector for OpenAI: Bring software delivery into ChatGPT and Codex

Harness Connector for OpenAI: Bring CI/CD Context to ChatGPT & Codex A pipeline fails while you are working through a change in ChatGPT or Codex. To understand what happened, you need the execution details, the failed step, and the relevant pipeline configuration. Gathering that context can interrupt the work you were doing before you can even begin to solve the problem. The Harness Connector for OpenAI brings that delivery context into your AI workflow.

What tools detect and resolve Kubernetes resource contention automatically?

Table of Contents Resource contention happens when workloads compete for more capacity than a node or cluster can provide. For CPU and memory, the symptoms are familiar: CPU throttling, OOM kills, and noisy neighbors slowing latency-sensitive services. These are largely solved problems, addressed by accurate requests and limits, Quality of Service classes, and autoscalers like VPA and HPA that adjust sizing and replicas as demand changes. GPU contention is different, and far more expensive to get wrong.

What platforms support container auto-scaling and policy-driven resource management?

Table of Contents Autoscaling and policy-driven resource management are two sides of the same coin. Autoscaling adjusts capacity as demand changes, while policies define the boundaries it operates within: who can use how much, which workloads can be changed, and what safeguards must be respected. Without autoscaling, clusters are either overprovisioned or overwhelmed. Without policies, autoscaling can create runaway costs, noisy neighbors, or disruptive changes to critical services.

Cost per AI outcome: tying AI spend to results

Cost per AI outcome is your total attributed AI spend divided by the business results it produced: resolved tickets, converted leads, merged pull requests. It includes the cost of failed attempts, sits at the top of the AI unit-cost ladder, and it's the number that makes vendor outcome pricing, ROI claims, and build-versus-buy decisions comparable.

Shipped: Don't ask an AI agent what its work will cost

If you set the budget for your team’s AI agent work, or answer to someone who does, you need a rough idea of what a job will cost before it starts. That’s hard to get. Stanford researchers found the same agent, given the same task, can use up to 30 times more tokens from one run to the next, and you usually find out afterward. Most developers just run the job.