Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on DevOps, CI/CD, Automation and related technologies.

What to expect in a Gremlin workshop

Gremlin workshops give your team hands-on training with Gremlin so they can get real results and dramatically improve your reliability. Full transcript:  The goal of our workshops is really to accelerate you and the team in your reliability journey. Whether you're starting out for the first time, or you're a more advanced user, this workshop is really designed for you to take you to the next level.
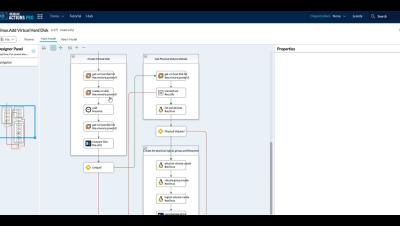
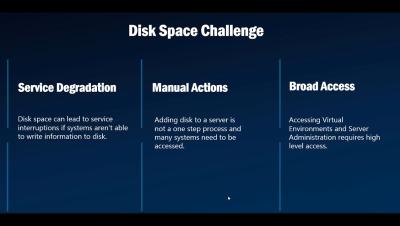
Automating Linux Disk Expansion with Resolve: Add & Extend VM Disks in Minutes!

Running into disk space issues on your Linux servers or virtual machines? In this step-by-step demo, we show how Resolve’s powerful automation platform can help you automatically add and expand disk space on Linux systems, eliminating manual processes, reducing human error, and improving operational efficiency. In this video, you’ll learn how to: Technologies Featured: Whether you're a system admin, IT operations engineer, or automation specialist, this demo highlights how to streamline critical disk management tasks that normally require elevated access and technical knowledge.

Automate Disk Space Management on Windows with Resolve

Struggling with managing disk space issues on your servers or virtual machines? See how you can use Resolve to automate disk space addition and expansion on Windows systems, saving time, reducing manual errors, and eliminating the need for high-level administrative access. In this video, you'll learn how Resolve automates the process of: Whether you’re a system admin, IT operations engineer, or automation enthusiast, this demo highlights how you can streamline infrastructure tasks using intelligent automation.

Use Telegraf Without the Prometheus Complexity

Every system needs observability. You need to know what your CPU, memory, disk, and network are doing, and maybe keep an eye on database query latency or Redis connection counts. But setting that up isn’t always simple. You start with a couple of shell scripts. Then come exporters. Then Prometheus. Before long, you’re managing scrape configs, tuning retention, and watching dashboards fail under load after two days of data.

Maximizing Peering Through Flow Analysis

Discover how to use flow data to pinpoint your most valuable traffic, identify missing peer opportunities, and make smarter peering choices across your internet exchanges. In previous peering blogs, we’ve shared how you can maximize the value of your connection to an IX by peering with the IX route servers, and identify and contact specific peers via bilateral sessions.

Upgrading to Puppet 8 - What You Need to Know

Discover how Puppet 8 takes performance, modernization, and automation to the next level! This video offers a comprehensive overview of all the latest changes and benefits, including faster catalog compilation, streamlined agent execution, and improved debugging capabilities with enhanced logging and error messages. Key Moments in This Video:· Importance of Using PDK Explore key upgrades like these and see how tools like PDK empower your team by identifying and resolving compatibility needs quickly.

What's Driving Traffic in Rural America - Broadband, Wireless & DCI for AI

s consumers continue to shift away from traditional cable broadcasting towards streaming video services such as Netflix, Disney+, Hulu, and Paramount+, this will continue to drive the demand for robust middle mile solutions. This growth in data traffic demands not only enhance rural provider’s Internet infrastructure but also fortify their needs for data center interconnectivity (DCI) to metropolitan hubs. In this context, rural markets require connectivity solutions that can support 100G and even 400G connections to efficiently handle rising bandwidth needs tied to cloud applications and content delivery networks.

Measure your reliability risk, not your engineers

Do you know the current reliability risk of your systems? Do you know right now how your services will react to common failures like a dependency going down? Sadly, most organizations don’t have answers to these questions, relying on QA tests and the skill of their engineers to deploy code they assume won’t break. But this is a process problem, which means you can’t hire your way out of it.