Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on APIs, Mobile, AI, Machine Learning, IoT, Open Source and more!

Sponsored Post

How to cut AI infrastructure spending without reducing GPU capacity

Every infrastructure leader running AI workloads is staring at the same problem: GPU spending keeps climbing, the finance team wants a justification, and the operations team is caught between proving the infrastructure is necessary and explaining why the returns aren't keeping pace with the investment. The instinctive response is to either procure more capacity to handle growing demand or cut back on what's already deployed. Neither actually solves the problem.
Test PostgreSQL With the Queries Your App Actually Runs

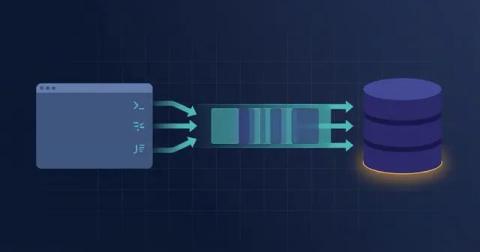
The first number from my local PostgreSQL 16 test was roughly 1,600 statements per second. It looked impressive. It was also the least useful result in the run. The useful part was the workload. It came from queries the demo app had actually sent: the same prepared statements, parameters, reads and writes. A synthetic benchmark tells you how PostgreSQL handles a synthetic workload. It does not tell you whether your migration just broke the UPDATE your app depends on.

AlmaIQ in practice: when AI solves productivity problems in minutes

In a market where new tools and technologies are constantly emerging, it is easy to get carried away by features. The real differentiator, however, lies in the impact a solution has on operations. That is what stands out most about Almaden’s solutions. More than a Digital Employee Experience (DEX) platform, it turns data into decisions. It enables IT teams to anticipate problems, act proactively, and improve the user experience.

How does fragmented telemetry affect an AI system's ability to reason what's really happening?

Fragmented telemetry limits what AI can understand. When logs, metrics, and traces remain siloed, AI sees individual signals instead of the full story. That can lead to incorrect conclusions and unexpected outcomes. This is where AI observability matters. Virtana connects telemetry across the stack, giving AI the context it needs to correlate signals, understand dependencies, and identify what is really happening.

Who Is Actually Qualified to Oversee AI

Who should actually be trusted to oversee AI? As frontier AI systems become more powerful, the question isn't just whether we need more oversight — it's who is actually qualified to provide it. Adam Arellano, Martin Reynolds, and Bryan D. Payne debate whether governments, third-party evaluators, academics, former frontier-lab employees, or independent organizations can realistically hold companies like OpenAI and Anthropic accountable.

Introducing Selector Foundry: Agentic NetOps

Network operations teams have heard plenty about AI this year. Most of it answers the alert in front of it, then hands the rest of the incident back to an engineer. Someone still has to correlate the evidence, find the cause, prepare the fix, and prove it held. This week, we announced Selector Foundry, the agentic NetOps solution built into the Selector platform. Foundry adds a team of specialized AI agents on top of the full-stack observability and AIOps foundation our customers already run.

You made coding faster. Guess where the bottleneck went next.

Somewhere in the last year, your team's code output went up. Pull requests are opened faster. The backlog of small fixes and routine changes started clearing quicker than it used to. If delivery still feels roughly as slow as it did before, that's what happens when you speed up one part of a process without touching anything downstream of it.

We stopped asking an LLM how much its own work would cost

There’s a specific kind of measurement problem worth naming precisely rather than dramatizing: this month we found that our model-routing agent was assigning a token budget to every unit of work, and that budget was noise in the strict sense. Fixing it meant improving a system that’s mostly right, not tearing one down.