Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on Service Reliability Engineering and related technologies.

A Day in the Life: Intelligent Observability at Work with our SRE, Dinesh

When I asked Charlie for permission to attend this year’s AICon (virtual, natch) I thought it would be a shoo-in; learning’s part of my OKRs after all. But he never makes things easy and his ‘yes’ came with a caveat that’s typical when dealing with him. This time, he claimed he didn’t have the budget for the ticket (a likely story!) and I’d have to find another way to get one.
SRE fundamentals 2021: SLIs vs. SLAs. vs SLOs

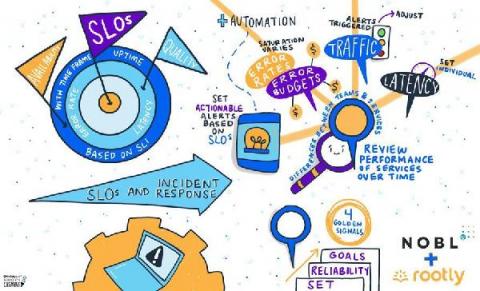
A big part of ensuring the availability of your applications is establishing and monitoring service-level metrics—something that our Site Reliability Engineering (SRE) team does every day here at Google Cloud. The end goal of our SRE principles is to improve services and in turn the user experience. The concept of SRE starts with the idea that metrics should be closely tied to business objectives. In addition to business-level SLAs, we also use SLOs and SLIs in SRE planning and practice.

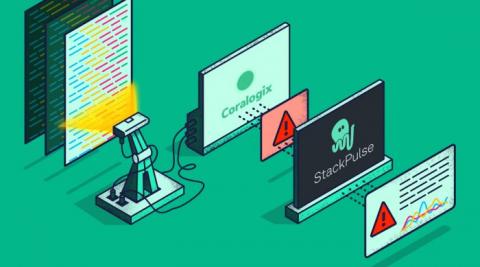
Using Coralogix + StackPulse to Automatically Enrich Alerts and Manage Incidents

Keeping digital services reliable is more important than ever. When something goes wrong in production, on-call teams face significant pressure to identify and resolve the incident quickly – in order to keep customers happy. But it can be difficult to get the right signals to the right person in a timely fashion.

Creating Custom Slack Commands

Site Reliability Engineers are expected to know everything that’s happening, all of the time. That’s a lot of things! To help you sift through the noise, we’ve developed a feature that lets you find accurate data about your organization on-demand. You can do this by sending custom-designed commands to FireHydrant directly from your integrated Slack account.