When You Do DevSecOps, Don't Forget the SREs
It's time to break down the silos separating SREs from security engineers.


The latest News and Information on Service Reliability Engineering and related technologies.
It's time to break down the silos separating SREs from security engineers.
4 best practices for breaking down silos and establishing a culture of shared responsibility toward reliability.
In my past experience as an SRE I’ve learned some valuable lessons about how to respond and learn from incidents. Declare and run retros for the small incidents. It's less stressful, and action items become much more actionable. Decrease the time it takes to analyze an incident. You'll remember more, and will learn more from the incident. Alert on pain felt by people — not computers. The only reason we declare incidents at all is because of the people on the other side of them.
Rootly is on a mission to create a world where maintaining reliability is frictionless, delightful, and accessible to anyone. Making resolving and learning from incidents every organizations superpower.
From network problems to computer failures, a variety of incidents can disrupt operations for systems in outer space.
Our fourth annual SRE Report launched last week. I had the good fortune to be involved in writing and editing it this year for the first time alongside our very own driving force Leo Vasiliou and the brilliant Eveline Oehrlich at DevOps Institute (check out Eveline’s take on the report’s Key Takeaways here), in addition to a number of folks at VMware Tanzu.
From chaos engineering to monitoring and beyond, SREs rely on several key types of tools to do their jobs.
This year’s SRE from Anywhere (SREFA) brought together hundreds of registrants from around the world to gather virtually, share experiences, and network around all things SRE. We were thrilled to see so many friendly faces!
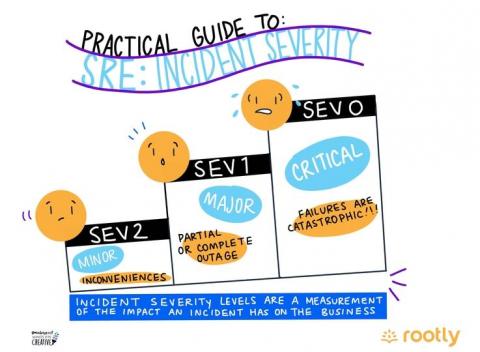
Incident severity levels are a measurement of the impact an incident has on the business. Classifying the severity of an issue is critical to decide how quickly and efficiently problems get resolved.