The Role of SREs in Observability
Although conversation about observability often ignores SREs, SREs have a central role to play in observability success.


The latest News and Information on Service Reliability Engineering and related technologies.
Although conversation about observability often ignores SREs, SREs have a central role to play in observability success.
Site reliability engineers (SREs) are involved in scaling systems and making them reliable and efficient for organizations. But SREs often fail to build system resiliency when they do not have the right tools at their disposal. In this post, we’ll uncover five leading tools that SREs can use to drive the reliability and stability of computing systems. It also examines how SREs can use the tools to improve operations tasks and infrastructure processes.
Even seemingly minor math bugs in software code can have outsize consequences.
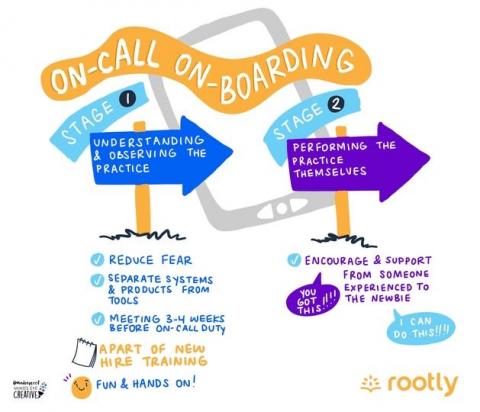
Maintenance of your incident management practice is as important as creation - find out what you can do to keep your engineering organization strong and consistent year over year.
Site Reliability Engineer (SRE) is one of the fastest growing jobs in tech, with Linkedin reporting 34% growth YoY in 2020 and over 9000 openings in their Emerging Jobs Report. If you’re new to SRE and exploring it as a career path, understand that it can be a challenging but rewarding experience. Here are some quick tips on how you can get started with SRE and jump-start a rewarding career.
The Four Golden Signals of monitoring and observability get a lot of things right. But they could be even better.
A look at outages and disruptions to the IT systems that power the Olympics, from 1996 to today.
Although the fundamental concepts of site reliability engineering are the same in any environment, SREs must adapt practices to different technologies, like microservices.
Site Reliability Engineering (SRE) and Operations (Ops) teams heavily rely on notifications. We use them to know what’s going on with application workloads and how applications are performing. Notifications are critical to ensuring SREs and Ops teams can resolve errors and reduce downtime. They’re also crucial when monitoring environments — not only when running in production but also during the dev-test or staging phase.