Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on DevOps, CI/CD, Automation and related technologies.

SRE Incident Management: Overview, Techniques, and Tools

In the world of a site reliability engineer (SRE), failure is not only an option, but also expected. Systems, web applications, servers, devices, etc., are all prone to performance issues and unexpected outages at some point. It is an unavoidable fact. These unexpected failures can lead to huge revenue losses, customer trust and depending on the industry, maybe fines. Fortunately, SRE incident management is one of the core practices used to limit the disruption caused by unexpected issues.
Share your failures, fix them faster with shareable activities

When you’re working with a Continuous Delivery workflow, you rely on building and deploying your websites in such a way that any improvements can be released into production any time. Identifying and fixing failures quickly is key to enabling rapid development cycles. But what happens when you’re looking into a failed build step, with no clue as to how to address it? You can now share links to specific lines within the activity logs.

Estimating Your Cloud Costs is EASY. Do it in Just 3 Clicks.

One of our customers recently got their first bill after moving their Linux and Windows workloads to Azure. Their bill was astronomical! They struggled to answer the question, “how much will it cost?” and their initial cost assessments were vague at best. Here’s what they did.

How to Delete Pods from a Kubernetes Node

When administering your Kubernetes cluster, you will likely run into a situation where you need to delete pods from one of your nodes. You may need to debug issues with the node itself, upgrade the node, or simply scale down your cluster. Deleting pods from a node is not very difficult, however there are specific steps you should take to minimize disruption for your application.

Elastic Observability 7.16: Ad hoc analytics and CI/CD pipeline visibility

Elastic Observability 7.16 introduces curated data exploration views for ad hoc analysis and further extends visibility into complex and distributed systems with the general availability (GA) of dozens of prebuilt Elastic Agent data integrations, observability tooling for continuous integration and continuous delivery (CI/CD) pipelines, and a new native data source integration with Amazon Web Services (AWS) FireLens. These new features allow customers to.

DevOps State of Mind Podcast Episode 4: How to Build With Confidence with LaunchDarkly

Today we're joined by CTO and Co-founder of LaunchDarkly, John Kodumal. LaunchDarkly is a feature management platform that gives developers total control of their code so that they can ship quicker, reduce risk, and reclaim their nights and weekends. We're going to talk about why having tools that help devs build with confidence is essential to a successful DevOps culture and John's top tips for enterprises who are early in their DevOps adoption.

Sponsored Post

Service Mocks: Scaling a SaaS Demo with Traffic Replay

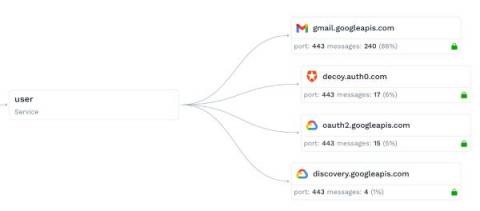
Building, running and scaling SaaS demo systems that run around the clock is a big engineering challenge. Through the power of traffic replay, we scaled our demos in a huge way. A few weeks ago we launched a new demo sandbox. This is actually a second generation version of our existing demo system that I built a few months ago (codename: decoy). Because the traffic viewer page shows the most recent data by default, you need to constantly be pumping new data in there. Any type of real-time SaaS system is going to have a similar requirement. So this needs to be planned.