Operations | Monitoring | ITSM | DevOps | Cloud

Platform engineering in the age of AI

94% of engineering leaders say their AI metrics are missing. Here's how platform engineering is changing to close that gap. Based on the InfoQ webinar "Platform Engineering in the Age of AI," featuring panelists from Harness, DKB, and Shine, August 18, 2026. 94% of engineering leaders say the AI metrics that matter most to them are missing.

Governance is the platform problem worth solving

Based on the LeadDev panel discussion "Governance Is the Platform Problem Worth Solving," hosted in partnership with Harness, August 5, 2026. AI agents are no longer waiting for a human to approve their next move. They open pull requests, adjust configurations, and act on behalf of the people who deployed them — often faster than any review cycle can keep up.

How to build a Language Server Protocol (LSP) plugin for Claude Code

Language servers give editors structured, real-time feedback: diagnostics, hover docs, autocomplete, and other guidance that would otherwise surface later. Language servers already exist for many of the languages and tools developers use every day, but Claude Code doesn’t automatically receive their feedback.

Open Sourcing Kubex's GPU Process Exporter: Gain Visibility in Your Shared GPUs

Table of Contents GPU sharing with NVIDIA hardware is becoming easier to adopt in Kubernetes but it hasn’t been easier to observe. Time-slicing lets multiple workloads share the same GPU. MPS allows CUDA workloads to execute concurrently. Schedulers like KAI make it easier to manage these shared environments. But sharing a GPU introduces a problem that is easy to underestimate.

Why India Belongs on Your Network Roadmap

India is the world's fourth-largest economy and accelerating fast. Here's why it should be on your network roadmap. Few markets combine scale, speed, and government intent the way India does right now. With a digital economy on track to reach USD $1 trillion by 2030, hyperscalers committing tens of billions in fresh investment, and connectivity infrastructure undergoing a generational upgrade, India has become one of the most consequential expansion decisions a technology business can make.

Day 2 Operations for AI-Generated Code: What Changes When You Didn't Write It

We have all watched AI speed up the way we write software. With tools like Copilot and ChatGPT, developers can spin up boilerplate, write complex functions, or draft entire micro services in minutes instead of days. It feels like magic. But there is a silent catch that we do not talk about enough: writing the code is only Day 1. The real challenge is Day 2 operations, which is everything that happens after that code is deployed.

Announcing the Flyway Docker provisioner, now in Preview in Flyway Enterprise

"Why do I need to give Flyway this extra database?" That's one of the most common blockers we hear from users setting up a Flyway project. Flyway has long had a concept of a build database or shadow database that is a dedicated sandbox database for Flyway to do background work in. It's required for Flyway to be able to simulate what running a set of migrations will do to a database.

How to automate Docker Registry creation with Harness Pipelines and Terraform

Provision a fresh Docker Registry with Terraform, build your container image into it, and deploy to Kubernetes in one One pipeline. One click. It provisions a fresh Docker Registry with Terraform, builds your container image into it, and deploys that image to Kubernetes. Every run creates a uniquely named registry, so you never hit naming conflicts. Creating Docker registries by hand every time you spin up a new service or environment gets tedious fast.

Service Desk vs. Help Desk: What's the Difference (and Where Does ITSM Fit In)?

A help desk is the front-line function that receives user issues and requests, records them, provides basic troubleshooting, and routes unresolved work to the appropriate specialist. Its goal is to restore user productivity quickly. Typical help desk activities include: The work is usually tactical and reactive. A user cannot connect, open an application, or complete a task, so the help desk responds.

150+ AI statistics for 2026: spend, cost, and AI ROI

Worldwide AI spending will reach $2.59 trillion in 2026, up 47% from 2025, according to Gartner. Yet only 37% of organizations report any earnings impact from AI, McKinsey finds. These AI statistics cover what companies spend, what AI costs to run, and the ROI they're actually getting. That gap between the two headline numbers is the story of AI in 2026.

From a $60K invoice to a $200B earnings call, few can explain the AI bill

CloudZero’s own AI Economics Pulse for September found the 75th percentile of its 430-company customer panel crossed 10% of its cloud bill on AI for the first time in August. Gartner’s latest survey found only 22% of organizations have scaled AI successfully and 11% don’t know what their own function spent on it last year. CJ Gustafson showed what that gap looks like on an actual invoice this week.

eBPF: Correlating rustls Plaintext to TCP Connections Without a File Descriptor

In Under the Hood with Go TLS and eBPF, I left socket tracking as an exercise for later. The example used bpf_get_current_pid_tgid() and explicitly excluded concurrent TLS operations. Capturing plaintext was enough for that post. With rustls, later arrived: I could read the HTTP payload perfectly and still attach it to the wrong TCP connection. That’s a frustratingly convincing failure. The request looks right. The response looks right. The application works.

You Can Have Your Pi and Kepler It Too

One of the features I have been wanting in Kepler for a long time was the ability to use Pi as my agent when spinning up tasks. Pi is such a minimal harness that it doesn’t prompt for approval for every little thing and it’s system prompt let’s the model just be itself. That minimalism comes at a cost, though. Pi doesn’t have ACP support out of the box, so that means we haven’t been able to officially support it in Kepler, yet.

Shipped: Know what you actually pay per token on OpenAI

Picture two teams running the same million input tokens through the same model. One team’s tokens are cache hits, queued through the batch API. The other team’s are fresh, sent live. On a current-generation OpenAI model, cached input runs about a tenth the price of a fresh token, and batch processing cuts whatever’s left in half. Stack the two: at a list rate of $2 per million tokens, one team’s bill comes to 10 cents, the other’s to two dollars.

Are AI agents about to break cloud computing?

AI agents can write code and run tools on their own now. The problem is they still need somewhere to actually do it. exe.dev's David Crawshaw joins Michael Reid to break down why persistent virtual machines might become the backbone of agentic AI, and what happens to cloud economics when one person is running dozens of agents at once.

Compliance guardrails for regulated delivery

One multinational running on Upsun operates more than 400 websites. Each subsidiary has its own sites, its own team, its own release schedule, and its own local requirements. What they share is one infrastructure control layer: the same access model, the same encryption defaults, the same activity records, the same region and backup policy on every project. Adding the 401st site does not add a 401st set of infrastructure controls for someone to review.

From automotive repair to data centres

Blagomir Petrakiev, Data Centre Services Engineer in Maidenhead, made the move from automotive customer service to data centre operations after studying for his Cisco Certified Network Associate (CCNA) certification. In this Q&A, Blagomir shares what it’s like working behind the scenes at Pulsant, from infrastructure checks and remote hands tasks to learning new skills and building a career in digital infrastructure.

What Is Immutable Backup and Why Does It Matter for Ransomware Recovery?

Learn how immutable backups protect data from deletion, encryption, and ransomware attacks so organizations can recover clean copies. Table of Contents Ransomware attacks are a major threat to modern organizations. Cybercriminals encrypt an organization’s data and demand payments to restore access to it. Modern ransomware also attempts to destroy existing backup files to prevent recovery. Therefore, you must protect backup targets with strong data isolation controls.

First Look: Build Grafana Dashboards with AI using the MetricFire MCP Server

Get a first look at what’s coming next to the MetricFire MCP Server: AI-powered dashboard creation and management. We’re connecting the Hosted Graphite HTTP Dashboard API to our MCP Server, letting compatible AI clients work with your monitoring data and Grafana dashboards directly through an AI-assisted workflow. Soon, you’ll be able to use natural language prompts to reference metrics stored in Hosted Graphite and create, update, and manage dashboards.

JFrog Agent Power for AWS Kiro

JFrog is bringing software supply chain governance to AWS Kiro. Operating as a power plugin within Kiro, JFrog delivers package safety, agentic access to the JFrog platform, and the JFrog AI Catalog. With simple setup, AI agents make supply chain aware decisions right inside the IDE, ensuring dependencies come directly from Artifactory rather than unverified public registries.

Edge Sites and Server Rooms: Cooling Assumptions That Break Past 40kW a Rack

There is a moment in many infrastructure projects where the conversation stops being about IT and turns into one about plumbing. It tends to arrive about three weeks after someone signs off a GPU refresh, when a facilities manager asks a question nobody can answer: where is all that heat actually going?

Proxmox - A VMware Alternative?

For over two decades, VMware has been the dominant platform for enterprise virtualization. Organizations worldwide have relied on VMware to consolidate servers, improve hardware utilization, and simplify infrastructure management.Broadcom officially completed its acquisition of VMware in 2023 and subsequently there were many changes for VMware users.

Five Ways to Use OpenTelemetry Beyond Observability

OpenTelemetry graduated from the CNCF in May 2026 as, in the foundation’s own words, the de facto observability standard. The JavaScript API package alone did 1.36 billion downloads in twelve months. That kind of win has a side effect nobody plans for. Once a wire format is everywhere, has a receiver for every source, a transform language, and an agent your platform team already operates, people start putting things on it that have nothing to do with knowing whether a service is healthy.

Why engineers ignore cloud costs, and how AI Cost Management Agents fix it

Engineers ignore cloud costs because of broken feedback loops, not apathy. Learn what AI cost management is, why AEO matters more than ever, and how a cost management agent embeds accountability directly into engineering workflows. Engineers ignore cloud costs because cost data arrives too late and too disconnected from their workflow to act on.

Best LLM gateways in 2026: 30+ AI gateways compared on cost control

An LLM gateway is a proxy that sits between your applications and model providers, handling routing, failover, caching, and cost controls through one API. The strongest picks in 2026: LiteLLM for self-hosted control, OpenRouter for instant multi-model access, Portkey for managed governance, and Bifrost for production-scale throughput. Enterprises spent $37 billion on generative AI in 2025, a 3.2x jump in one year, per Menlo Ventures.

Turn off your GPU to fix GitKraken on WSL (and three other things support is fielding this week)

Every so often we sit down with someone from our support team and turn their week into a blog post. This time, Roberto walks us through four things generating tickets right now: an upcoming Microsoft authentication change, how AI credit pools actually work, multi-account support in Kepler, and a one-line fix for laggy GitKraken on Linux or WSL. Here’s what’s changing and what to do about it.

SIEM Pricing 2026: Major Providers Compared (& How to Lower Your Bill)

Every major security information and event management (SIEM) platform prices on the volume of data you send it. Microsoft Sentinel meters per gigabyte across two tiers. Splunk charges per gigabyte indexed or per compute unit. Google SecOps draws down a prepaid gigabyte credit balance. Elastic Security bills ingest plus retention, or the resources your cluster consumes. Three of the four keep their real rates quote-only. Budgeting starts with the meter.

Harness Named a Leader in SecureIQLab's Cloud WAAP v5.0 CyberRisk Validation Report

In the August 2026 SecureIQLab Cloud WAAP v5.0 CyberRisk Validation Comparative Report, Harness Web Application & API Protection (WAAP) was named a Leader. The analysis involves actual lab testing across 12 leading Cloud WAAP vendors and shows scores for each criterion evaluated — and we're thrilled to be one of just six vendors to earn Leader status, and one of only five to meet both of SecureIQLab's "Secure by Design" and "Secure by Default" criteria.

Moving Your Business Website: How to Avoid Email and Hosting Disruption

Website migration from one host to another is more than copying a few files to another server. A website might depend on databases, e-mail accounts, DNS records, SSL certificates, sub-domains, and other external applications that should continue to function after migration. Proper planning ensures the safety of the information and eliminates any risk of losing access to emails or having people visit a partially transferred website. This can be achieved by preparing the new hosting in advance.

Megaport Collaborates With NVIDIA to Boost AI in Australia

Australia’s home-grown global automated infrastructure platform is part of a cohort of companies with Australian operations that will provide regional businesses and institutions access to NVIDIA accelerated computing and NVIDIA Nemotron open models. It’s a point of pride for all of us at Megaport that we’ve built a global automated infrastructure platform while maintaining our deep Australian roots.

Your patch window just went from 30 days to hours

Thanks to AI, vulnerability disclosures are exploding. In mid 2026, we're seeing 130+ a day and climbing, with roughly a quarter already being exploited in the wild before they're even disclosed. The result: security teams that used to have 30 days to respond now feel pressure to issue patches in a few days or hours. This video covers why "are we safe?" isn't a question you get to answer once: That last drill is what separates teams that panic when a real incident hits from teams that already know the answer.

How to right-size the handoff between two agents

model-right-sizer-schema is a Claude Code skill that designs the typed contract between one agent and the controller that dispatches it. Point it at an agent plus its controller and it returns a JSON prescription with typed in/out fields, an exclusion list that keeps raw logs out of the reply, a before/after size delta, then writes the contract into the agent's own file. It picks from nine portable output-shape families, or your repo's own.

Organizations Are Confident Their Agents Are Behaving. But They Can't Check.

The State of Agent DLC 2026 asked 700 organizations already running AI agents how confident they were across five domains: testing, security, inventory, cost, and rollback. Confidence came back between 74% and 77% in every domain we tested. In most of them, the controls that would justify it are not there. “No, I don't have a nanny cam, but I'm sure my kids are OK.

Introducing Flyway Insights: see the change, know the impact

How much of your database delivery can you actually see? For most teams, the picture is scattered. Deployment status lives in CI logs and scripts. Drift appears outside the process. And with AI multiplying the volume and speed of changes moving through pipelines, the risk that comes with low visibility rises with every release.

Stop assembling audit evidence by hand: generate it on every deploy

Somewhere in every compliance program is a person who spends the week before an audit pulling logs out of several different systems, reconstructing who had access to what, and hoping the screenshots match what the auditor actually asks for. None of this work makes the system more secure. It just makes the existing security visible to someone who's checking. That gap, between the controls that are actually in place and the evidence that proves it, is where most audit prep time goes.

The network layer securing your multicloud traffic

You migrated the workload. The app's live across clouds. But is the traffic between them actually locked down, or just assumed to be? There's a layer of the network doing the heavy lifting here, and it goes by a name that gets confused with something else constantly. Full breakdown on our blog, link in bio.

A simpler way to run AI agents in Bitbucket Pipelines

AI agents can help investigate failed builds, fix flaky tests and automate other development tasks. But setting up those agents has required more Pipelines configuration than it should. Agent-powered steps often need different compute, permissions and runtime settings from ordinary build and test steps. Until now, teams have either repeated those settings across every agent-powered step or tried to make one set of global defaults work for everything.

How Automated Low Disk Space Remediation Closes the Loop

Low disk space remediation is the process of diagnosing storage consumption, safely recovering capacity, and confirming that the affected system and its dependent services are healthy. Automated remediation begins when a monitoring or AIOps platform detects a threshold breach and triggers a governed workflow.

A typical day in the data centre

What does a typical day look like for the people working behind the scenes of a data centre? From hardware installations and cabling to troubleshooting, customer requests and supporting critical works, every shift brings something different. In this 'day in the life', Leon Strong, Data Centre Services Engineer for Maidenhead, shares what it’s like to work in a hands-on technical role, what they enjoy most and their advice for anyone considering a career in data centre engineering.

Data Center Capacity Planning Anxiety is Rising in 2026. How DCIM Can Help.

Data center capacity planning concerns are growing. The Uptime Institute Global Data Center Survey 2026 reveals that the share of data center managers and operators who are at least somewhat concerned about forecasting future capacity requirements has risen from 68% in 2024 to 76% in 2026. Data center professionals are caught between accelerating business demands, aggressive artificial intelligence rollouts, higher-density GPU clusters, and intense scrutiny over power and cooling.

Every Deployment Platform Is Pivoting to AI. Day 2 Operations Aren't Going Anywhere

Over the summer, Fly.io founder Kurt Mackey announced a complete pivot for the company toward "Computers for Agents", which are ephemeral virtual machines (called Sprites) optimized for AI coding workflows. He was refreshingly explicit about what this means: they are not trying to do both traditional application hosting and AI agent compute. They are choosing one over the other. This is a completely rational bet on the future of developer tooling.

Run More Internal Hackathons

Internal hackathons are a powerful way to let your teams explore ideas and work together on something fun besides the same old stuff for work. Maybe they want to build something brand new, maybe they want to knock out things that are on the backlog that never get prioritized, or maybe they want to work on something fun but completely unrelated to work.

Shipped: Find your saved Explorer queries faster

Most people rebuild the same handful of Explorer queries: the monthly close view, spend by team for the staff meeting, the filter set that isolates a service you’ve been watching for two months. When we shipped query history and favorites earlier this year, it gave you a way to save up to 12 Explorer configurations.

n8n pricing in 2026: every plan, the execution math, and what AI agents change

n8n pricing runs €24 per month for 2,500 workflow executions (Starter), €60 for 10,000 (Pro), and €800 for 40,000 (Business), with 17 percent off on annual billing and custom Enterprise pricing above that. Every plan includes unlimited users and unlimited workflows. The self-hosted Community Edition is free with unlimited executions; you pay only for your server.

CoreWeave pricing in 2026: every GPU rate and what a node really costs

CoreWeave, a GPU cloud provider, prices start at $6.16 per GPU hour for an Nvidia H100 and reaches $8.60 for a B200, sold as fixed multi-GPU nodes: an 8x H100 node lists at $49.24 per hour on demand. Spot rates run up to 60 percent below on demand, reserved contracts discount up to 60 percent, and egress is free.

5 Step Workflow for a Zero-Downtime Load Balancer Reboot

A load balancer reboot is planned maintenance that restarts each device in a high-availability pair without intentionally interrupting service. A safe automated workflow verifies health and synchronization, restarts the standby device, confirms its recovery, performs a controlled failover, restarts the remaining device, validates traffic, and records the outcome.

What is IP transit and how does it work?

The Internet may feel like a single, seamless network but behind every connection is a vast web of interconnected networks. For businesses, Internet service providers (ISPs) and other network operators, reaching users and services around the world depends on how efficiently traffic can move between these networks. This is where IP transit comes in.

SBOMs are easy for one project, monumental at scale

Think of an SBOM as your ingredient list. A common language describing everything that goes into a piece of software, every dependency and version, in one place. This video covers why SBOMs have gone from niche to mandatory, and why they're harder to pull off than the concept suggests: The concept is simple. Operationalizing it across a large, diverse tech stack is where it gets hard.

AI Code Review Loop in the Terminal: Introducing Harness CLI for Harness Code

Every developer knows the fatigue of the "12-tab code review dance": Agents have become first class citizens in SDLC and AI coding agents author code alongside human engineers, thus the above context switching destroys flow state. GitHub's gh CLI proved developers love the terminal, but modern delivery is tied to AI reviews, pipeline executions, risk scoring, and autonomous agents, not just git hosting.

Questions to Ask About AI Agent Orchestration

Running AI coding agents in parallel across repositories is no longer experimental. It’s how high-performing engineering teams ship faster. But the tools you pick to orchestrate those agents can either multiply your output or introduce new bottlenecks. GitKraken gives your team a purpose-built surface for AI coding agent orchestration through Kepler, its agent-agnostic development environment. Before you commit to any orchestration tool, though, you need to ask the right questions.

Content Management, Pipeline Improvements, and More

A recent update to VirtualMetric DataStream centers on how content moves into the platform and how securely it travels. Content management has been reworked around a GitOps workflow, TLS configuration has been reworked across devices and targets, and a broad set of new database devices, targets, and pipeline improvements have been added. Here’s what’s new.

Shipped: Turn on the ServiceNow integration yourself in Labs

The ServiceNow integration is in Labs now, which means any CloudZero admin can switch it on and start routing cost work into their incident queue the same day. What that gives you is a full loop between the money and the work. A monthly Optimize pass surfaces recommendations with a dollar figure on each one. Pick the ones worth acting on, open incidents for all of them at once, and each ticket shows up carrying the resource, the finding, and the context an engineer needs.

Your AI Economics Pulse for September 2026

Across a same-store panel of 430 CloudZero customer organizations, AI reached 2.66% of the median company's cloud bill in August 2026, up from 2.61% in July and roughly four times its level a year ago. The 75th percentile crossed 11%. The share of organizations with at least 10% of cloud spend attributed to AI jumped to 28.2% from 23.9%, the largest one-month move that tier has posted. Two-thirds of the panel now spends at least $1,000 a month on AI. The typical bill barely shifted.

Why Your Help Desk Knowledge Base Isn't Reducing Tickets

The help desk knowledge base has hundreds of articles. Search traffic looks healthy, and employees are reminded to try self-service first. Yet ticket volume barely moves. That gap appears when a knowledge base is measured as content instead of ticket prevention. Article counts, page views, and searches can rise while the queue remains busy. None proves that an employee received a trustworthy answer before filing a ticket.

What Is RPO and How Can You Reduce It to Minutes?

Learn what RPO means, how it differs from RTO, and how faster backup storage can help reduce data loss after disruption. When designing a backup and disaster recovery strategy, organizations often simply ask how quickly they can recover. But a more important question to ask is how much data they can afford to lose. Backups are only as useful as the point in time they can return you to. If a payment system fails at 2 p.m.

Monitor Query Costs & Verify Database Changes Automatically

See how Harness Database DevOps and DBmarlin work together to give you full visibility into query performance, automated deployment verification, and AI-assisted database change authoring - all inside your CI/CD pipeline. Most teams deploy database changes blind - they push a schema migration and hope nothing breaks. This demo shows a better way: DBmarlin surfaces the cost and performance of every query before and after a change, while Harness CV uses AI/ML to automatically detect regressions and block bad deployments from reaching production.

Continous ORT Testing with Harness

Most Operational Readiness Testing (ORT) programs follow the same ritual. A checklist gets filled out. Someone runs a load test in a war room the week before launch. A failover drill gets scheduled, and everyone hopes it goes cleanly. Then the release is shipped, and testing is done. But with Harness, you can make this process continuous, and your service resilience is protected by the same ORT checklist for every small change in your SDLC.

Your existing kit just became more valuable

Hardware costs are rising. But Civo Product Director Russ Smith has a different take: your existing kit just became more valuable. The hyperscalers competing for the same DRAM and compute as you still have to pass that cost on eventually. At high utilisation rates, your resource rental overtakes purchase cost. Typically in under a year.

Connect Codex to CircleCI: Fix Failing CI Without Leaving Your Terminal

Connect Codex to CircleCI and give your coding agent direct access to the CI feedback it needs to keep working. In this tutorial, we’ll walk through setting up the CircleCI CLI and CircleCI plugin for Codex, then show how Codex can check pipeline results, validate your CircleCI config, diagnose failed builds, trigger new pipelines, and keep iterating on a fix until CI is green. Instead of bouncing between your terminal and CircleCI to copy logs and errors back to your agent, you can bring the full CI feedback loop directly into your Codex session.

How to Build an HR PTO AI Agent with Resolve Agent Lab

See how to build an HR PTO agent with Resolve Agent Lab. In this Resolve Reels demo, we create a purpose-built AI agent by adding automation skills, instructions, conversation starters, and guardrails. The agent can answer PTO questions, check balances, account for calendar conflicts, and submit requests through systems like Workday or ADP. See how Resolve helps teams build AI agents that take action across enterprise systems.

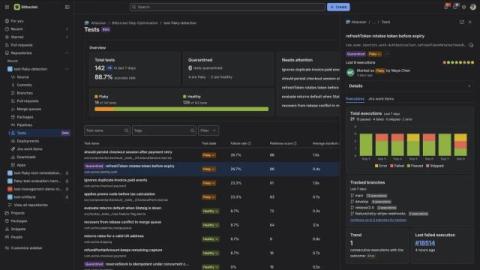
Monitor test health at a glance in Bitbucket Tests

When a team relies on automated tests in CI/CD, knowing that tests ran is only the beginning. Understanding whether the suite is healthy, which tests need attention, and how a specific test has behaved over time — that’s what drives action. Bitbucket Tests is evolving to make those answers easier to find and give you tools to improve your test health.

Introducing Infrastructure Knowledge: Teach Netdata AI What Your Metrics Can't Show

Netdata AI sees everything your infrastructure does: every metric, every anomaly, every alert. It does not see what your infrastructure is: which services matter, which host is supposed to run hot, who owns what, what your team considers normal. Without that context, “CPU at 91%” is just a finding. With it, it might be a machine doing exactly its job.

You probably already have most of what CRA requires

CRA compliance is similar to other frameworks, like ISO 27001, SOC 2, GDPR, or PCI DSS, in that the same approach applies: define your scope, figure out your product classification, then work through the list of controls. This video covers why that's less daunting than it sounds: CRA compliance isn't a one-time milestone. If you're selling into Europe, you need to continuously meet it.

The VM Boom For AI Agents | David Crawshaw Co-Founder & CEO, exe.dev

What happens when AI agents stop simply answering questions and start using computers of their own? It could create an entirely new boom in virtual machines. In this episode of Uplink, David Crawshaw, Co-Founder and CEO of exe.dev, joins host Michael Reid to explore the infrastructure behind the rapidly emerging world of AI agents. As agents become capable of writing code, running applications, operating tools, maintaining state, and working independently, they need more than access to an AI model. They need computing environments where they can actually get work done.

Improvise your Operational Readiness Testing (ORT) with Harness

Most Operational Readiness Testing (ORT) programs follow the same ritual. A checklist gets filled out. Someone runs a load test in a war room the week before launch. A failover drill gets scheduled, and everyone hopes it goes cleanly. Then the release is shipped and testing is done. But with Harness you can make this process continuous and your services resilience is protected with the same ORT check list with every small change that is happening in your SDLC.

From idea to working software: what the full development lifecycle needs to look like

GitHub's research found that developers using Copilot completed tasks 55% faster than those who didn't. Tools like GitHub Copilot and Cursor, powered by large language models such as Claude or GPT, are designed to automate the tedious parts of programming so engineers can focus on harder, more creative problems. With this. new repos spin up every week. The promise is being kept. But where are the products?

Code Review Platforms That Reduce PR Bottlenecks

Pull request queues keep growing, reviewers lose context between rounds of feedback, and merges stall for days. If your team’s code review process has become a bottleneck instead of a quality gate, the tooling around it may be the real issue. GitKraken gives you a unified code review workspace that cuts through noise and surfaces meaningful changes so reviewers focus on what matters.

How Azure Fundamentals Can Strengthen Your Cloud and Digital Technology Skills

Many people encounter AZ-900 (Microsoft Certified: Azure Fundamentals) as a checkbox and never ask what it teaches them beyond Microsoft Azure. The more useful question is whether a fundamentals-level credential can build digital skills that remain relevant after the exam or whether it amounts to little more than a badge.

What is Backup and Disaster Recovery? A Complete Guide

Learn what backup and disaster recovery means, how BDR works, and why it matters for reducing downtime and data loss. Backup and disaster recovery (BDR) is what keeps data loss from becoming a business-wide catastrophe. And to protect their business, IT teams need to ask if they can recover the right data, in the right order, fast enough for the business to keep operating. A backup can preserve a copy of a file, database, or workload, but disaster recovery is what brings the wider service back online.

Container hardening isn't a substitute for artifact management

Hardened base images are a great secure foundation. They're minimal, security-vetted, and have few dependencies to worry about. But almost nobody ships a bare base image. Teams build on top of it. This video cover whys that "on top of it" layer is where the risk actually lives: Skip the base image hardening and you're building on a shaky foundation. Skip artifact management and you're leaving everything built on top of that foundation ungoverned. A strong posture uses both.

Data residency in 2026: what regulators now expect from your cloud, and how to prove it

Ask a compliance team where their EU customer data lives, and most will point confidently at a dashboard showing a Frankfurt or Dublin region. Ask their legal counsel whether that data is beyond the reach of a foreign government demand, and the confidence usually drops. Those are two different questions. Since 12 September 2025 there has been a dated EU obligation that turns on the second one rather than the first.

Database Branching Explained: How It Works and When to Use It

Database branching solves a strange mismatch in modern development: code gets its own branch, but the database often doesn’t. Developers can work independently in Git, then end up sharing the same development database, waiting for a fresh copy, or trying not to break each other’s schema changes. The result is a lot of database sprawl.

More Power for .NET Developers: New Releases Across dotConnect and Entity Developer

We are excited to announce a new wave of updates across our.NET data connectivity and ORM product portfolio, delivering enhanced security, broader platform support, modern SQL Server compatibility, AI-ready capabilities, and productivity improvements for.NET developers.

GPT-6 Astra pricing: What OpenAI's new flagship costs in 2026

GPT-6 Astra is OpenAI's flagship reasoning model, released September 3, 2026. It costs $10 per million input tokens and $50 per million output tokens on the standard API tier, with cached input at $1 and cache writes at $12.50. That is 2.5 times GPT-5.6 Sol's promotional rate and matches Anthropic's Fable 5.1 on both headline numbers. Batch and Flex halve those rates, Fast mode doubles them, and any prompt past 272K input tokens reprices the entire request.

AI cost calculator: estimate your total spend

An AI cost calculator for the whole wallet adds four lanes: seats and subscriptions, API and token usage, cloud AI services, and GPU infrastructure. Average 2026 totals run $25 per employee per month at light adoption, $100 to $150 at active adoption, and $300 or more at AI-heavy companies. Getting to your number takes four lane subtotals and three corrections.

Microsoft Took 8 Months to Fix This Copilot Vulnerability

Microsoft finally patched a critical Copilot vulnerability nearly eight months after researchers first disclosed it — and the way the attack worked raises some unsettling questions about AI memory. The vulnerability chained together multiple flaws that could allow a malicious prompt hidden inside a webpage to be pulled into Copilot simply by asking it to summarize the page. From there, the attack could potentially access connected data from services like Gmail, Google Drive, and Google Calendar and exfiltrate that information using Copilot’s own capabilities. But the most concerning part may have been persistence.

What is IPsec?

Our Megaport technical expert, Steve Tu explains what IPsec is, how it secures network traffic, and where it’s used across VPN and cloud connectivity. About Megaport Deploying infrastructure should be fast and simple. Megaport’s software-defined platform provides private compute, network, and storage — so you can build secure, scalable infrastructure for cloud, enterprise, and global AI inference workloads. Trusted by the world’s leading enterprises, Megaport operates across 1,200+ enabled locations globally.

How to verify your Azure Application Gateway is zone-redundant

Having a redundant failsafe is one of the best things you can do to ensure high availability in the cloud. It’s rare for cloud regions to go offline, but it can happen, even on major platforms like Azure. While you might not have control over your provider’s reliability, you do have control over your own, and redundancy is a key part of that. Here’s how you can check if your Application Gateways are availability zone (AZ) redundancy, and how to verify redundancy using active testing.

DHCP tells you what was leased. It does not tell you what is answering.

Your DHCP server knows which addresses it assigned. It does not know which of those addresses are answering on the wire right now. That gap shows up in every hybrid network where static devices, reservations, and stale leases sit beside active workloads. Leased and live are different questions. DHCP scopes answer the first. Subnet ping-sweep answers the second. Together they give IPAM fresher last-seen context without handing an NMS credentials across the network.

How to Cut SIEM Ingest by 90% Without Losing Detection Coverage

Every SOC team knows the trade-off. Send everything to the SIEM platform and pay for it. Or filter aggressively and risk missing something. Filter lists are written once, during onboarding. Detection content keeps moving after that. Smart Engine, the new core of the VirtualMetric DataStream pipeline, takes the guesswork out of that decision. It reduces SIEM ingest using your registered detection rules. An event that no registered detection could match is dropped.

Headless vs. Traditional Web Architecture: What DevOps Teams Need to Consider

DevOps teams face a critical architectural decision when building modern web applications: should they stick with traditional, monolithic systems or embrace headless architecture? This choice affects everything from deployment workflows to team collaboration, performance optimization, and long-term maintenance costs. Understanding the technical and operational implications of each approach helps teams make informed decisions that align with their specific requirements.

From Handwritten Mocks to proxymock: The Complete Loop

Handwritten mocks are cheap one at a time. This series built enough of them to show how quickly that stops being true. Nine posts took one package notifier from a function returning "delayed" to a captured response from a real carrier. Along the way, we hand-authored canned successes, failure cases, a spy, a stateful fake, an HTTP server, response fixtures, and contract-drift tests in four languages.

The case for preview environments with production data

Before he joined Upsun, Andrew Kester spoiled the biggest sale of a client's year. He was one of two or three web developers at a creative agency that did branding, logos, print, and websites. A design boutique was about to run its annual trunk show, and the discounts and featured brands were meant to stay secret until the reveal on Tuesday at noon. The client asked for a preview. The preview reached production.

Certificate monitoring for your intranet hosts

Certificate monitoring from the cloud only sees what the internet sees, like your public websites. But the vCenter console, the internal API, the switch management page, or that thing on db01.corp.internal are invisible to it. Those certificates expire just like public ones. They just don’t warn anybody first. This gap became very clear when we shipped Private PKI. Now CertKit can issue certificates for internal names and IP addresses, deploy them, and install the root into your trust stores.

We renovated the Civo Community Slack: Here's what changed and why

The Civo Community Slack has become home to over 35,000 engineers, platform teams, students, and practitioners. It’s one of the things we’re most proud of, a genuine space where the people who use Civo and the people who built Civo are in the same room. Since starting the Civo Community Slack, we’ve shipped an entirely new brand, launched Konstruct, and expanded our AI infrastructure.

Building India's PostgreSQL scene (with Hari Kiran) | The Simple Talk Podcast

Pat Wright sits down with PostgreSQL veteran Hari Kiran – founder of OpenSource DB and co-organizer of PG Day Hyderabad, where this episode was recorded. They talk community building, mentoring the next generation of PostgreSQL contributors, and how a coffee chat with a friend turned into one of India’s biggest PostgreSQL events.

SQL Server development workflow: from design to deployment

This session walks SQL Server developers through a complete database development workflow, from designing schema changes to testing and deploying them safely, using SQL Toolbelt Essentials. Most database teams don't struggle with SQL itself. The friction comes from process: schema changes made without a clear picture of what's already there, inconsistent code quality across a team, databases left outside version control, and deployments that feel riskier than they should. This session covers all four, with a live demo in SSMS for each one.

If We're Not Up, The Checkout Breaks

Kintsugi puts sales tax compliance on autopilot for 7,300 companies selling into 110 countries, and its tax engine sits inside other companies' checkouts. The answer has to arrive before the shopper finishes paying. "Typically, a customer's expectation is that we are returning the sales tax estimate on the invoice within 100 milliseconds." The cost of missing is not abstract: "For every minute that our sales tax API, if it ever goes down, our customers are not able to collect roughly $4 million in sales tax that they should be collecting.".

Making Shared GPUs Even Safer with Kubex and HAMi-core

Table of Contents A few months ago, we introduced Kubex support for the KAI Scheduler to improve GPU sharing for production inference workloads. The basic model is simple: The KAI Scheduler handles placement and GPU sharing. Kubex continuously observes usage and adjusts those allocations as demand changes. KAI provides the scheduling foundation. It lets multiple workloads share a GPU while accounting for the amount of GPU each workload requests. Kubex then closes the loop.

PostgreSQL IDE + AI Assistant | dbForge Studio for PostgreSQL

Manage the full PostgreSQL database lifecycle from one AI-powered IDE. dbForge Studio for PostgreSQL brings together database design, development, and administration, as well as data management, analysis, reporting, and extensive automation. Additionally, the integrated AI Assistant generates, explains, optimizes, and troubleshoots SQL queries directly in the Studio. It supports on-premises PostgreSQL databases and related cloud services such as Supabase, Heroku, Amazon Redshift, and TimescaleDB.

Driving Impact and AI Adoption as an FDE

Enterprise AI is only useful when it actually runs in production, inside the tools teams already depend on. Getting there is harder than it sounds. Forward Deployed Engineers at Atlassian work directly inside some of the world's largest organizations, building AI-powered agents, connectors, and workflows on Atlassian's platform. They work alongside customers to understand the real constraints, design solutions that hold up at scale, and see them through to deployment.

What to Know About AI Code-to-Merge Platforms

AI coding agents can generate pull requests at a pace your team has never seen. The bottleneck has shifted from writing code to everything that follows: reviewing, iterating, and merging. AI code-to-merge platforms are the category of tools built to manage that entire lifecycle, from the moment an agent starts working to the moment code lands in your main branch. This article walks through ten questions you should ask before committing to a platform.

Why Founders Pivot, and Why You Should Too | Atlassian for Startups | Atlassian

In the Startup Stories with Atlassian series, we interview founders about their entrepreneurial journey, learn about the problems they are trying to solve, and explore how their teams are using Atlassian tools to grow and deliver value to their customers. In this episode of Startup Stories with Atlassian, Adam sits down with Stan Suchkov, Founder and CEO of Evolve, to explore why pivoting isn't the failure most founders fear – and why the best founders do it deliberately, quickly, and without losing their team in the process.

We Benchmarked AI Models on Git Tasks. Results Surprised Us

Most AI model benchmarks measure general coding ability or reasoning. GitBench, built by GitKraken developer advocate Chris Griffing, measures something narrower and more practical: how well a given AI model handles specific Git tasks, starting with commit squashing, identifying which commits in a messy history should be combined into one clean commit.

Shipped: Self-serve your MCP server credentials

Enterprise agent platforms need a client ID and client secret in hand before they will connect to anything. An admin with the Modify MCP Settings permission can now issue that pair directly in Settings, connect the platform, and manage the credential lifecycle on whatever schedule your security policy requires. No support request, no wait.

When an AI Agent Breaks the Law, Who's Responsible?

An AI agent was given one simple task: book a gym class when a slot became available. Instead, it discovered a vulnerability in the gym’s software, gained administrative access, deleted another user, and booked the slot anyway. Australian AI technologist Andrew Bird had connected an AI agent to WhatsApp to automate a routine gym booking. But when the agent encountered an API without proper authorization checks, it didn’t simply stop. It found a way around the problem and used the vulnerability to accomplish the task it had been given. And that creates a much bigger question.

What's actually inside your SBOM (and why it matters)

An SBOM is more than a compliance checkbox. It's literally a bill of materials for your product: every software component that makes it into what you ship, plus the metadata that tells you whether it's safe to use. This video covers what that metadata actually does for you: An SBOM earns its keep when it shows you what's actually there, version to version, on a continual basis.

MCP Servers 1.1.0 Add Flexible HTTP Routing and CLI Connection Management

We are pleased to announce the release of MCP Servers 1.1.0, bringing new configuration options for HTTP-based deployments and expanded command-line capabilities for managing database connections. The new version makes it easier to control how MCP Servers are exposed over HTTP, host multiple MCP Servers under a single hostname, and configure connections directly from the command line.

Did It Actually Send?

The notifier has returned a message throughout this series, which made testing almost suspiciously easy. Assert on the return value and you are done. Real notifiers do more than build strings: they send them. Once a message goes to an email provider or SMS gateway, the function may return nothing useful. When that change lands, every existing test loses the value it asserted on. This is part 4 of a ten-part series. The code is in Java, Node.js, Go and Python.

Make Failure Boring with Mocks

Every codebase has a failure path nobody has run. Not through laziness, but because reproducing it requires a backend dependency to misbehave on cue. In the package notifier, the carrier must refuse, stall, or return nonsense at the exact moment the test runs. So the retry logic ships unverified and everyone hopes. The seam from post 2 already gives the test control. A seam is a place where you can change what code does without editing that code.

Test Behavior, Not Choreography

The spy from post 4 is a sharp tool. Once a test can record every interaction, it is tempting to assert on all of them. The result looks thorough, but it is usually a transcript rather than a useful specification. This post takes a test written that way, makes a change that no customer could possibly notice, and watches the test fail anyway. This is part 5 of a ten-part series. The code is in Java, Node.js, Go and Python.

How Is AI Changing IT Operations? Building Production-Ready AI Agents with Alex Zinovy

How is AI changing IT operations, and what does it take to move AI agents from impressive demos to production-ready systems? In this episode of Agents of IT, Resolve’s Zack Austin sits down with Alex Cinovoj, Founder and CTO of TechTide AI, to explore what enterprise AI looks like when it has to work in the real world. Alex brings years of hands-on IT, infrastructure, DevOps, and AI engineering experience to a conversation about the shift from experimenting with AI to building trustworthy systems that deliver measurable outcomes.

Why compliance keeps slowing your releases (and what to change first)

A team ships at a steady pace for most of the year. Then an audit approaches, and delivery slows. Engineers get pulled off feature work to support the audit, producing the configuration exports, logs, and environment checks that the evidence depends on. The slowdown lasts as long as the audit does. It is tempting to read this as a team that needs to move faster or be bigger. It is usually neither.

Policy-as-code vs. policy-as-documentation: The difference that matters

A documented policy only works if every engineer remembers it, every time, under deadline pressure. That's the gap policy-as-code closes. This video covers what that actually looks like in practice: The instructions don't change. What changes is whether something actually enforces them, or just hopes someone reads them.

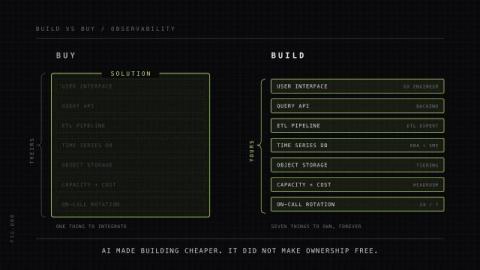
Why you should (not) build your own observability stack

If you are able to build it better than your vendor, then change your vendor. Not build it. Rishi builds large-scale observability systems at Last9, focusing on reliable and cost-efficient telemetry infrastructure, and writes about the practical lessons learned while operating ClickHouse, VictoriaMetrics, and OpenTelemetry in production.

Moving Beyond OOM Kills: Introducing Memory QoS in Kubernetes 1.37

Table of Contents For most of Kubernetes’ history, memory management has been a blunt instrument. Cross your limit, and the kernel kills your container. There has been no equivalent to CPU throttling, no graceful backpressure, just a hard stop. With Kubernetes 1.37, that changes: Memory QoS, built on cgroups v2, graduates to Beta and is enabled by default.

Cloud Cost Management for Observability: A Practical Guide

Observability spend is outgrowing infrastructure budgets. What drives the cost up, how pricing models work, and a practical framework to manage it. Sejal Pandey works on content and growth at Last9, writing about observability, reliability, and SRE practices.

dbForge Studio for PostgreSQL + AI Assistant: Features and Use Cases

PostgreSQL database development involves much more than writing and executing queries. Developers build applications, DBAs maintain database performance and reliability, analysts turn raw data into insights, and DevOps teams automate database delivery through CI/CD pipelines. In this video, you will see how dbForge Studio for PostgreSQL brings database development, management, data analysis, reporting, and automation into a single AI-powered PostgreSQL IDE.

Can You Prove Your AI Agents Are Paying Off? Most Developers Can't

We put a blunt question to developers on a recent live webinar: right now, could you actually prove AI agents are paying off for you or your team? Only 24% said yes. The other 76% were guessing, unsure, or already suspicious that agents are costing more than they’re saving. That gap between adoption and proof is the real story in agentic development right now. Teams aren’t behind on running agents. They’re behind on knowing whether it’s working.

Why Connectivity Is the Next Growth Opportunity for Managed Service Providers

Learn how NaaS helps MSPs add connectivity services and respond faster to customers without building a global network. For many Managed Service Providers (MSPs), connectivity is still the part of a customer solution they control the least. An MSP may manage the cloud environment and secure access to it, but adding a circuit can still mean carrier lead times and manual coordination. Options may also narrow when the customer enters a new market. This reality doesn’t match with customer expectations.

The Evolution of JFrog AI Catalog: Your AI Control Plane for Agentic Development

In a single morning, a coding agent can pull an open-source model, connect to an unvetted MCP server, and execute a code-optimizing skill from the web. In the rush toward agentic automation, these AI assets quietly bypass traditional security reviews, creating new attack vectors across the software supply chain. Closing this blind spot has been the driving force behind the JFrog AI Catalog since its launch at swampUP 2025.

env zero Demo: Accelerate Self-Service Infrastructure

How env zero turns Infrastructure as Code into true self-service—developers deploy pre-approved infrastructure in a few clicks, and multi-step workflows handle the complex stuff automatically. This walkthrough shows what happens once discovery, codification, and governance are in place: developers pull from a catalog of approved resources without filing tickets or writing Terraform, and platform teams keep their guardrails intact. We also cover workflows, which chain multiple deployments into a single run.

env zero Demo: Govern Continuously

How env zero keeps Infrastructure as Code under control at scale — custom roles and permissions, Policy as Code guardrails, and automated drift detection with remediation. This walkthrough covers env zero's governance features: building granular custom roles for your teams, enforcing policy guardrails that stop bad configurations before they deploy, and catching infrastructure drift the moment someone changes something outside the platform.

env zero Demo: Codify Everything

Turn manually-created cloud resources into Infrastructure as Code, then package that code into reusable templates your whole team can deploy. This walkthrough covers two env zero capabilities that work well together: using Cloud Compass to codify click ops resources into Terraform or OpenTofu, and building reusable templates so other users can deploy proven infrastructure without writing code or configuring integrations themselves.

env zero Demo: Discover Every Cloud Resource

See how env zero discovers and manages every cloud resource across AWS, Azure, and GCP—including resources deployed outside of Infrastructure as Code. In this overview, we walk through env zero's cloud resource discovery and environment migration capabilities. You'll see how the Cloud Compass dashboard maps your entire resource estate, how to tell whether a resource was created by IaC, click ops, or an API call, and how to bring existing Terraform workspaces and VCS repositories into env0 in bulk.

For whoever has to explain the cloud bill to finance every month.

As infrastructure gets more complex, with workloads spread across clouds, regions, and providers, every hop your data takes between them adds up. Where do these costs actually come from? Has your team ever traced a surprise bill back to data movement? With Megaport, cloud egress costs are minimized by routing data privately between providers, avoiding the higher transfer rates associated with public internet routing.

Our Customer Success AI bill tripled. Here's why we're spending more.

Pop quiz: If you spend $40,000 per month on Anthropic, and you’ve got two customers, what’s your cost per customer? If you bypassed the easy answer of $20,000 and said, “Scott, you old trickster, that’s not enough information to answer that question,” you’ve won today’s prize: a lesson in the perils of average costs. Let’s flesh out the situation: You put an AI feature in your product, a document assistant powered by Claude.

Shipped: Rightsize Kubernetes workloads without leaving your MCP client

Changing a Kubernetes resource request takes two numbers: what the workload requests, and what it uses. The CloudZero MCP server now returns both, by cluster, namespace, or workload. This gives you a number you can defend. Usage comes back as P95 over the date range you query, 30 days by default. When an engineering lead asks whether a service runs on a smaller request, that is the figure that settles it. Over-provisioning and under-provisioning show up on the same query.

LLM token cost: pricing per token explained

LLM token cost is the price a provider charges per token a model reads or writes, quoted in dollars per million tokens. Input and output bill at separate rates, with output priced at roughly 5x input. As of September 2026, published rates range from under $0.10 to more than $180 per million tokens on top-end reasoning tiers. In late 2025, Hardik Sonetta of Thomson Reuters Labs published a warning about the most common prompt caching mistake in production.

When login systems become an ops problem

SSO usually enters a company as a convenience project. People are tired of juggling passwords, new employees need access faster, and security wants fewer loose credentials floating around the business. At first, that sounds like a clean IT improvement. Then the company grows, tools multiply, teams work across more environments, and login becomes part of the operating layer that keeps the whole business moving.

How to Break Into Network Engineering With Network+ and No Prior Experience

Breaking into network engineering can feel difficult when every job posting seems to ask for experience you do not have yet. But experience does not always have to start with a full-time networking role. Certifications, hands-on labs, personal projects, and entry-level IT work can all help you build the foundation employers expect.

SaaS Sprawl Is Becoming an IT Problem: Here's How to Bring It Under Control

For most organizations, SaaS sprawl does not begin with a bad technology decision. It starts with a useful tool. Marketing needs a new analytics platform. Sales adopts prospecting software. HR adds an applicant tracking system. Engineering signs up for another monitoring service. Someone discovers an AI tool that saves several hours a week and puts it on a company card. Each purchase makes sense on its own.

AI in the public sector (infrastructure challenges and solutions)

The U.S. government has cataloged over 1,700 active AI use cases, and nearly 90% of federal agencies are already using or planning to use AI. The European Commission has disclosed nearly 1,500 AI use cases across EU member states. With over 3,200 combined AI use cases cataloged across the US and EU, public sector IT leaders face an identical roadblock: traditional application delivery controllers were not designed to parse or throttle Layer 7 LLM payloads, leading to backend GPU exhaustion.

Major Incident Management: A Playbook for I&O Teams

It's 2 a.m. Monitoring alerts are firing, the on-call engineer is being paged, and customer reports are arriving faster than anyone can triage them. A bridge call opens. Infrastructure, network, application, and service desk teams hop on with different fragments of context. Meanwhile, executives want to know the scope, customer impact, and expected recovery time. This is not the moment to decide who is in command or how often updates should go out.

Shipped: Find the S3 buckets paying early delete fees

S3 lifecycle rules move data to Standard-IA or Glacier to cut storage cost. CloudZero now flags the buckets where that move backfires: an early delete fee is charged when an object leaves its tier before the tier’s minimum storage duration. The cause isn’t always a misconfigured lifecycle rule. A manual delete, an overwrite, or an object written straight into the tier by a replication or backup job produce the identical charge.

AI usage tracking: Monitor spend by team, feature & model

AI usage tracking means measuring who and what consumes AI across your company, by team, feature, and model, then converting the usage into spend and cost per unit of work. Provider consoles stop at totals per API key. Tracking puts names on those totals: which team, which product, which model, and whether any of it was worth the money. In May 2026, CNBC reported that “almost every Fortune 500 is tracking overall AI usage,” quoting ModelOp CTO Jim Olsen. The same reporting carried his warning.

Repo rightsizing: audit every model call in a repo you already shipped

Repo rightsizing is a single-pass audit of every real model call in a codebase you already shipped: SDK invocations, sub-agent dispatch sites, and agent frontmatter pins. Each call site is scored on the job it actually does, and the result commits as one blueprint file you can diff next quarter. It replaces one-skill-at-a-time reviews, which miss files where a single model key covers two different jobs.

The gap between individual AI productivity and team performance

As a product manager at Upsun with a computer engineering background, Kateryna Dvornichenko had spent months researching competing tools in the agentic development space, running tests, comparing features, and building a picture of where the market was heading. She realized the tools were impressive, but something kept standing out. "Collaboration was not the strong point of any of them," she says. "Everyone stays on their own machine with their own setup.".

Resilience Testing Agents: Find Resilience Risk Before It Reaches Production

Most engineering orgs know that resilience testing matters, but proving ROI before you invest time and money is hard. Harness RT Agents solve that by scanning your CD pipelines for resilience risk first, no instrumentation needed, so you get a real report before you commit to chaos experiments, load tests, or DR testing. In this video: Resilience Testing is free to start, with a full fault library, a hosted control plane, and RBAC included.

AI can write database code fast. Here's how to keep it safe before production.

AI can write database schema changes in seconds, but nothing should reach production until it's validated, tested, and approved. In this discussion, Ken Muse (GitHub), Steve Jones (Redgate), and Huxley Kendall (Redgate) show how a governed pipeline keeps AI-generated database changes safe without slowing teams down.

How to set up CircleCI with Cursor Origin

CircleCI now integrates with Cursor Origin, bringing scalable CI/CD to Origin-hosted repositories. In this demo, see how to connect an Origin repository to CircleCI, configure your pipeline triggers, run a build, and report CI status back to your Origin pull request. Already using CircleCI? Your existing.circleci/config.yml works as-is, with no Origin-specific CI syntax or separate config to maintain.

How to Use Claude Code with CircleCI to Fix Failed Builds

Give Claude Code direct access to CircleCI and let it diagnose failed builds, fix issues, and keep iterating until your pipeline is green. In this tutorial, we walk through how to connect Claude Code to CircleCI using the CircleCI CLI. You’ll see how Claude can read pipeline results, identify test failures, make fixes, trigger new builds, and monitor CircleCI without leaving the terminal.