Using Sleuth at Sleuth [Stories from the Trenches]
For the final story from the trenches, we're sharing how we ourselves use Sleuth at Sleuth to track Accelerate / DORA metrics, find bottlenecks, and automate to deploy faster.


The latest News and Information on DevOps, CI/CD, Automation and related technologies.
Azure Government is a dedicated cloud for public sector organizations that want to leverage Azure’s suite of services in their highly regulated environments. As these organizations migrate their applications to Azure Government, they need to ensure that they can maintain visibility into the status and health of their entire infrastructure.
When you write enough Puppet code, you will eventually find yourself in need of a Facter fact or Puppet resource type that doesn’t exist in Puppet itself. Then, if you’re like me, you go to the Puppet Forge and see if someone else has written what you need. Oftentimes, you find what you need, add a new module to your Puppetfile or module metadata, and move on with your life.
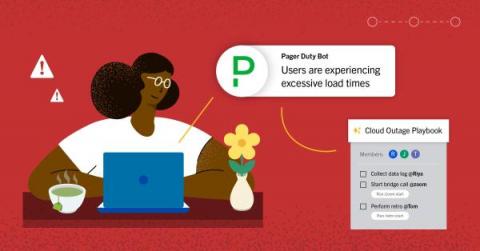
While service incidents can be wildly dissimilar, they tend to have one thing in common: a need for quick resolution. Response teams need a robust, repeatable process to follow that ensures fast, mistake-free execution, especially for those 4 AM calls. Having a documented checklist saved where the entire team can access and use it at any time could make the difference between quick resolution or compounding the problem.
The need for relevant and contextual telemetry data to support online services has grown in the last decade as businesses undergo digital transformation. These data are typically the difference between proactively remediating application performance issues or costly service downtime. Distributed tracing is a key capability for improving application performance and reliability, as noted in SRE best practices.
Cloud infrastructures have introduced increasing levels of complexity—you have to manage workloads across on-premises, private, and multiple public cloud environments. This requires you to migrate efficiently, optimize effectively, and stay rightsized on an ongoing basis, all while meeting evolving business requirements. With so many moving parts, it can be a massive challenge with lots of pitfalls that can cost you time and money and even put your business results in jeopardy.
Intel and Canonical collaborate to build and publish OpenVINO™ container images based on the Ubuntu ecosystem. This work aims to provide trusted, secure, and developer-friendly container images for AI/ML applications in many industries.