Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on DevOps, CI/CD, Automation and related technologies.

How to set AWS S3 Bucket Read Permissions with Relay

Cloud environments are susceptible to security issues. A big contributor is misconfigured resources. Misconfigured S3 buckets are one example of a security risk that could expose your organization’s sensitive data to bad actors. Policies and regular enforcement of best practices are key to reducing this security risk. However, manually checking and enforcing security is time-consuming and can fall behind with all the demands a busy DevOps team faces every day.

Our Groundbreaking Partnership with Docker Is a Boon for DevOps Teams

Today we’re announcing a big move that will yield substantial, concrete benefits for our customers and for the entire DevOps community: A groundbreaking partnership with Docker that exempts Cloud users of the JFrog Platform from Docker Hub’s image-pull rate limits. This agreement further boosts JFrog’s vibrant ecosystem of integration partners, built on the “too integrated to fail” principle that’s been a pillar of our company since its founding.

Distribute Software Releases Globally with JFrog on AWS

Release management is a topic that leaders in DevOps teams should be concerned with as organizations move toward implementing systems of automated continuous deployment. The practice will make your organization more efficient, but how do you implement it? Modernizing your infrastructure for the cloud is essential to distributing trusted releases globally. Many enterprises choose AWS as their platform, and seek to use AWS edge services to distribute their production applications to nearby end-points.

What Is Interconnection And Why Is It So Important To Enterprises?

Enterprise network connectivity has evolved in line with changing business needs over the last few decades and as we saw with the sudden shift to remote working in 2020, the evolution cycle is speeding up in response to environmental change. This makes interconnection more important than ever to the modern enterprise.

Tyler Wells on building a culture of reliability at Twilio

What does reliability look like at a company that has thousands of employees and provides critical communication services to over 150,000 customers? We talked with Tyler Wells, Senior Director of Engineering at Twilio, to learn how he and his team created a culture of reliability at Twilio. He talked in depth about his experiences developing reliability goals, building reliability practices, and aligning engineering teams on these objectives.

Achieving the Observability Imperative Requires AI

The shift to Observability Over the last six months, unified monitoring, log management, and event management vendors have reoriented their technology portfolios (often without any change to the underlying functionality) towards Observability. In so doing, a fair amount of confusion has been generated in the market.

How to build your own incident management process

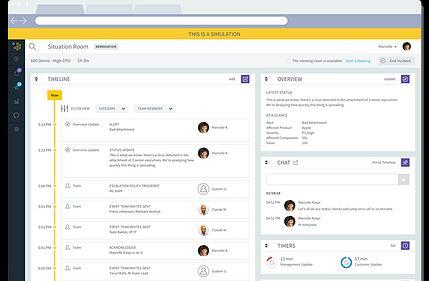
IT incident management is a fundamental operational process designed to ensure rapid service restoration. This process is typically assigned to the help desk but is also very much entrenched in the day-to-day of DevOps. When incident management goes right, service is restored quickly and the impact on productivity, continuity, and customer satisfaction is minimal.

Take the first step toward SRE with Cloud Operations Sandbox

At Google Cloud, we strive to bring Site Reliability Engineering (SRE) culture to our customers not only through training on organizational best practices, but also with the tools you need to run successful cloud services. Part and parcel of that is comprehensive observability tooling—logging, monitoring, tracing, profiling and debugging—which can help you troubleshoot production issues faster, increase release velocity and improve service reliability.