Operations | Monitoring | ITSM | DevOps | Cloud

Atlassian Transforms Product Development with AI

What used to take months now takes weeks, and it’s changing what it means to build great products. At Atlassian, product managers and designers are using Rovo and Jira Product Discovery to move faster at every stage of the development lifecycle. From running deep research across all their tools and documents, to capturing ideas, surfacing insights, and prioritizing what to build next. AI is transforming how product decisions get made.
Auvik Brings Multi-Vendor Network Intelligence to AI Agents in Cisco Cloud Control

Modern IT infrastructure is messy, spanning multiple vendors, cloud platforms, and on-premises systems, with critical data spread across separate tools. This patchwork makes troubleshooting harder for IT teams and AI agents alike, forcing them to piece together operational context from different domains and interfaces before they can act with a complete understanding of the environment. But what if AI agents could pull operational data from across your diverse IT environment and correlate it for you?

AI Spend Hit $297B. Nobody Knows Where It Goes.

AI spend doubled to $297B in two years — and most companies can't tell you what any of it shipped. Token spend is disconnected from outcomes on the dev side. Agents in production? The invoice is the only signal. Harness Cloud & AI Cost Management (CACM) gives teams unit economics at the inference level, cross-provider visibility across OpenAI, Anthropic, Bedrock, and Vertex AI, and request-level attribution to the agent, session, or workflow that triggered the spend.

Why Modern Executives Are Treating Online Reputation Like Business Insurance

Executives have always understood the importance of protecting valuable business assets. Buildings are insured against damage, data is protected through cybersecurity systems, and legal safeguards exist to minimize operational risk. Yet in today's digital economy, one of the most valuable corporate assets is no longer physical at all. It is reputation.

Your AI agent is fixing the wrong service

Everyone wants an AI agent factory in 2026. Autonomous agents fixing bugs and shipping features while you sleep. I’ve been building toward that myself. But the error rates don’t support the fantasy. The best AI coding agents in the world fix about 50% of real bugs on SWE-bench verified. Half the time they fail. And AI-generated code produces 1.7x more issues than human-written code.

How we cut Spark compute costs by 44% with agentic AI and Datadog Jobs Monitoring

Spark jobs only get more expensive and harder to debug as they scale. It’s a problem we’ve run into ourselves. Our Referential Data Platform team builds and maintains the knowledge graph that maps relationships between customers’ observability entities. ServiceQueryEdge is at the center of that graph, mapping service entities to their associated metric and log queries.

AI ROI is an allocation problem

AI spend is going parabolic, and the labels on the bill (OpenAI, Anthropic, Gemini) are about all a CXO gets to work with. The hard part of tying that spend to outcomes is structural. A major portion of AI spend isn’t COGS. It’s the spend on coding agents producing the software, the spend on building marketing content, the spend on custom sales tooling, the spend on Intercom agents and Sybill analysis.

Shifting Streams and AI Surges: What Our Data Reveals About the OTT Landscape

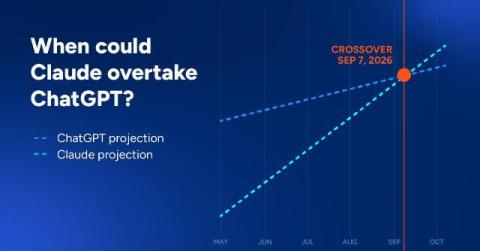
OTT data from early 2026 shows streaming hierarchies holding steady while AI platforms reshuffled rapidly. Claude has substantially increased traffic since January, overtaking Gemini, and is on pace to challenge ChatGPT by fall. Doug Madory digs into the data in this new analysis.

Inside the Grafana AI Team Weekly: AI Observability for the OTel demo and LLMSpec (May 12, 2026)

This is an excerpt from a real AI team weekly meeting where we talk about the stuff we build and occasionally also demo them! In this one, Principal Software Engineer Sven Großmann demos how he integrated AI Observability into the OTel demo, complete with the guards feature he introduced last week, and Principal Software Engineer Yas Ekinci gives a rare glimpse of LLMSpec, the internal counterpart of the o11ybench benchmark that we use to evaluate Assistant.