Operations | Monitoring | ITSM | DevOps | Cloud

Ai4 2026: Measuring AI spend is solved. Now it's time to prove its worth.

CloudZero had a full team on the ground at Ai4 in Las Vegas during the first week of August 2026. The team included CTO Erik Peterson, who spoke on a panel about AI cost economics. The same problem surfaced everywhere we went: teams can see what they’re spending, but not whether it’s working. DIY cost tooling that fails time and time again, agent sprawl, and a widening gap between finance and engineering kept coming up throughout the week.

AI-Related Outages Are Reshaping On-Call in 2026

AI-related outages just moved from a fringe worry to a mainline reliability problem, and the on-call rotation is where that shift lands first. A new StackGen analysis of nearly 178,000 public status-page records found that incidents disclosed by AI model and AI application companies now account for more than one in ten reported outages, a sixfold jump from 1.7 percent in 2023 to 10.7 percent so far in 2026.

Inference Optimization Techniques. Ray vs. vLLM vs. KubeRay

Serving large language models at scale is fundamentally a distributed systems problem. A single GPU, or even a single node, is rarely enough once you need multiple models, multiple replicas, tensor-parallel sharding across GPUs, or high-availability rollouts. Kubernetes solves general container orchestration well, but it has no native concept of a GPU-aware, actor-based compute cluster.

GPU Cloud security: Isolation, multi-tenancy, and protecting sensitive training data

GPU cloud security tends to get discussed as if it's the same problem as general cloud security. It isn't. GPUs sit between processes in ways CPUs don't. Training data passes through them in patterns that create specific exposure. Model weights derived from sensitive data are themselves sensitive material in ways most procurement processes don't recognize. And the multi-tenant nature of public GPU cloud creates failure modes that don't exist in CPU-only environments.

Homelab AI SRE Agent: AURA Debugs Container Permissions in Docker

A root cause is not a fix. AURA keeps working the problem, taking what you find on the host and coming back with the user ID mismatch behind the failure. What follows a root cause is normally manual: check the mount, compare ownership on the host against the user inside the container, and get it wrong at least once before it lands.

The MetricFire MCP Server | AI-Powered Monitoring

Monitor your infrastructure using natural language with the new MetricFire Model Context Protocol (MCP) Server. In this video, you'll learn how to connect the MetricFire MCP Server to AI assistants like GitHub Copilot and use simple prompts to search metrics, visualize data, create alerts, and manage your monitoring environment—without writing API calls. In this video, you'll learn how to.

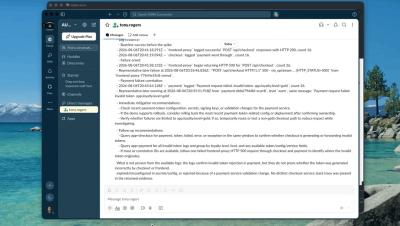
Paste a Slack Bug Report into an AI SRE Agent: AURA Finds the Cause

A coworker says checkout is broken and nothing else. That is the whole prompt. AURA reads the live logs and comes back with the payment service. Normally a message like this is the start of guessing at a service and opening dashboards until something looks wrong. Here it is the entire input: no service named, no error string, no time range.

Toil Reduction Outside the Data Center: Lessons From the Clinical Front Office

Ask an operations team where the week went, and you'll usually get a list of things that shouldn't have needed a person. Access requests provisioned by hand. A disk cleared for the ninth time this quarter. Certificates rotated one at a time because the renewal script was scoped, estimated, and never finished. None of it is difficult, and all of it is necessary. And at the end of the quarter there's nothing to point at, because the work left no trace beyond the absence of an outage.