Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on DevOps, CI/CD, Automation and related technologies.

Compute Confidently at the Edge with Rancher and Longhorn 1.1

Today’s announcement of Longhorn 1.1, a Cloud Native Computing Foundation (CNCF) Sandbox project, is exciting news for users of Rancher, SUSE’s Kubernetes management platform, and the Kubernetes community. Longhorn is an enterprise-grade, cloud native container storage solution that went GA in June 2020. Since then, adoption has increased by 235 percent.

How to monitor your AWS servers via MetricFire

In this article we explore the basics of monitoring Amazon Web Services (AWS) by feeding metrics to Grafana through Hosted Graphite’s agent and also through Hosted Graphite’s AWS add-on. This will allow us to monitor metrics from applications and servers hosted in AWS with clarity and depth. This article assumes you have created a Hosted Graphite account.

How to build your own incident management process

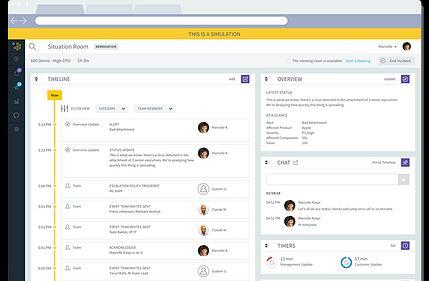
IT incident management is a fundamental operational process designed to ensure rapid service restoration. This process is typically assigned to the help desk but is also very much entrenched in the day-to-day of DevOps. When incident management goes right, service is restored quickly and the impact on productivity, continuity, and customer satisfaction is minimal.

The Future of Kubernetes on DevOps Radio

In this episode of DevOps Radio, Shipa’s CEO and Founder Bruno Andrade joins host Brian Dawson to discuss his thoughts on the future of Kubernetes. DevOps Radio is a CloudBees-sponsored podcast series. Hosting experts from around the industry, the show dives into what it takes to successfully develop, deliver and deploy software in today’s ever-changing business environment. From DevOps to Docker, each episode features real-world insights and a few stories, tips, industry scoop and more.

Achieving the Observability Imperative Requires AI

The shift to Observability Over the last six months, unified monitoring, log management, and event management vendors have reoriented their technology portfolios (often without any change to the underlying functionality) towards Observability. In so doing, a fair amount of confusion has been generated in the market.

Tyler Wells on building a culture of reliability at Twilio

What does reliability look like at a company that has thousands of employees and provides critical communication services to over 150,000 customers? We talked with Tyler Wells, Senior Director of Engineering at Twilio, to learn how he and his team created a culture of reliability at Twilio. He talked in depth about his experiences developing reliability goals, building reliability practices, and aligning engineering teams on these objectives.

What Is Interconnection And Why Is It So Important To Enterprises?

Enterprise network connectivity has evolved in line with changing business needs over the last few decades and as we saw with the sudden shift to remote working in 2020, the evolution cycle is speeding up in response to environmental change. This makes interconnection more important than ever to the modern enterprise.