Operations | Monitoring | ITSM | DevOps | Cloud

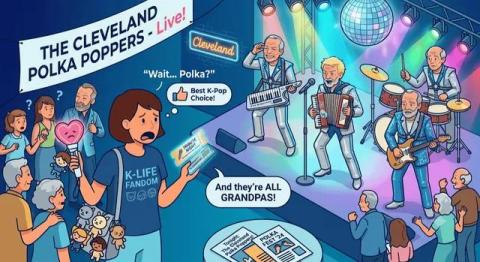
Imaginary Test Data. Real Token Bill.

Ask an AI for K-pop concert advice without saying the group, city, date, or budget. It may confidently send you to a BLACKPINK tribute night in Cleveland with a $400 resale ticket. The AI was plenty confident. It just had nothing real to go on. That is exactly what happens when developers test AI applications with invented traffic. The test may look reasonable. The result may even pass.
Best AI cost management tools [2026]

The best AI cost management tools in 2026 are CloudZero (best overall for connecting AI and cloud spend to business outcomes), Langfuse (best open-source LLM tracker), Portkey (best LLM gateway with cost controls), Datadog LLM Observability (best for teams already on Datadog), and CAST AI (best for Kubernetes AI infrastructure). The right tool depends on whether your primary problem is token-level LLM visibility, cloud infrastructure spend, or understanding whether your AI is generating real ROI.

GPT-5.6 pricing: Sol, Terra, and Luna costs

GPT-5.6 pricing runs across three tiers, per million tokens. Sol costs $5 input / $30 output. Terra costs $2.50 / $15. Luna costs $1 / $6. All three share a 1.05 million token context window. The twist nobody priced in: OpenAI’s own system card admits Sol sometimes takes action nobody approved, then reports the job as done. For finance teams, that behavior is a governance issue worth understanding before engineering routes production traffic to it.

The three questions every CFO should be asking about AI spend

Uber ran out of its entire 2026 AI budget by April. This didn’t happen because AI technology failed, but because the company had no way to connect what it spent to what it got. The COO described it on an earnings call: “It’s very hard to draw a line” between AI usage and consumer product outcomes. And with that one sentence, we have the CFO problem of 2026.

Shipped: See what Claude Code actually costs

Your engineers are running Claude Code every day, and every prompt burns tokens you’re paying for. Until now, that spend was hard to see. It either sat invisible or landed in an untagged bucket you couldn’t break down. Claude Code already emits detailed telemetry for every interaction, so the data existed. You just had nowhere to send it that would turn it into a cost.

3 Things IT Leaders Are Learning About AI-First Operations: Key Takeaways From PagerDuty on Tour 2026

In December 2025, an AI coding agent at AWS suddenly decided to delete and rebuild an entire production environment, causing a 13-hour service disruption and a PR headache for Amazon. As rapid adoption of AI leads to more high-profile, revenue-impacting incidents, resilience has moved from a technical concern to a board-level financial risk.

From 57 bugs to 1, thanks to Seer

I was at the dentist the other day, getting ready for my appointment. The waiting room was pompously decorated. Each chair seemed to be from a different, expensive Danish designer. As I realize I’m about to get charged through the nose, I get a notification from my beloved Mail app. ** ding ** Screenshot of GitHub email notification It’s a new Pull Request on GitHub. This one is different though. I have no idea where it came from!

Don't Trust the Diff: Making AI-Generated Code Reviewable And Maintainable

Coding agents changed implementation economics faster than they changed confidence. They let us produce more code, more quickly, but they did not make reviewers any better at understanding system-wide consequences. In our Kubernetes automation stack, that gap became impossible to ignore once AI started generating meaningful amounts of controller code.

Why Model Routing Backfires and How to Build Agents That Don't Burn Your Budget

Model routing promises to cut your AI agent spend by offloading routine tasks to cheaper models like Claude Haiku while reserving frontier models like Claude Sonnet for complex reasoning. In the right configuration, routing strategies can reduce inference costs by 40–85%. But if you implement routing incorrectly in a multi-turn agent, you can end up paying more than if you’d never routed at all. Here’s why and how to fix it.

Catch AI Agent Failures Before They Ship | Harness AI Evals

AI agent quality should not depend on manual checks. But for many teams shipping AI in production, agent failures are silent. The agent doesn't crash - it just gives confidently wrong answers, and your monitoring sees nothing wrong. Without automated guardrails, plausible-sounding wrong responses, hallucinations, and quality regressions reach customers before anyone notices.