Operations | Monitoring | ITSM | DevOps | Cloud

Infrastructure for AI Agents: Migrate in Hours, Not Months (Live Replay)

Replay and key takes from our October 20 live with TPC: why Day Two is 80% of infrastructure work, why shared staging breaks when agents write the code, how agents cut migrations from months to hours, and how to keep agents under control with policy tokens and audit logs. Romaric founded Qovery to make Kubernetes accessible to every engineering team. He writes about platform strategy, developer experience, and the future of cloud infrastructure.
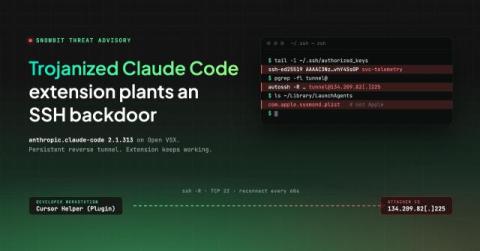
Threat Advisory - Trojanized Claude Code Extension: SSH Backdoor

A tampered build of the Claude Code editor extension (anthropic.claude-code 2.1.313) was published on the Open VSX store used by Vs code,Cursor and similar editors, quietly gives attackers persistent remote access to any computer that runs it, while the extension keeps working normally. Researchers don’t yet know how it was published (the listing belongs to an Anthropic employee) or who is behind it. They found no evidence that Anthropic’s official Marketplace release was affected.

AI observability: Why traditional monitoring isn't enough for AI systems

Traditional monitoring watches four things: whether the system is up (availability), how fast it responds (latency), how often it errors (error rate), and how hard the underlying resources are working (resource utilization). This system works because software is deterministic: the same input produces the same output, so a deviation means something broke, and it announces itself as a timeout.

Detect when your AI agent copies a self-replicating prompt injection

In September 2026, OpenAI reported finding self-replicating prompt injections. These attacks hide instructions in content an AI agent retrieves, directing it to take unauthorized actions and copy those instructions into emails, files, or messages. Copied instructions can then expose other agents or later sessions to the same attack, giving it the potential to spread like a computer worm.

Default to serverless for AI agents, then let production data decide what moves

Serverless should be the first execution model teams evaluate for AI agent workloads. Many agents spend much of their lifetime waiting, and always-on compute forces teams to pay for every idle minute. In a study of more than 35,000 production coding-agent sessions, the median session ran LLM or tool calls for only 20% of its lifetime. The rest of the time, it sat idle between steps, with its sandbox still allocated.

Can you see what your sales org did with $206,000 of AI last month?

Activity categorization classifies every AI request by the work it performs, such as meeting prep, code review or account research, then assigns that spend to the team, person, model and provider behind it. It turns a provider invoice that shows only totals by model and API key into a breakdown finance can allocate, charge back and budget from. CloudZero AI Signals does this as the spend happens.

Amazon told its engineers to stop chasing tokens

Amazon told its own engineers this week to stop tokenmaxxing. The memo circulated internally in September and Amazon published it on Tuesday, Oct. 27. Tokenmaxxing is the practice of using AI as heavily as possible with little regard for whether the output justifies the spend. The memo calls token usage, adoption rates, and code-change counts “deeply flawed” ways to measure a team.