Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on DevOps, CI/CD, Automation and related technologies.

Make Failure Boring with Mocks

Every codebase has a failure path nobody has run. Not through laziness, but because reproducing it requires a backend dependency to misbehave on cue. In the package notifier, the carrier must refuse, stall, or return nonsense at the exact moment the test runs. So the retry logic ships unverified and everyone hopes. The seam from post 2 already gives the test control. A seam is a place where you can change what code does without editing that code.
Did It Actually Send?

The notifier has returned a message throughout this series, which made testing almost suspiciously easy. Assert on the return value and you are done. Real notifiers do more than build strings: they send them. Once a message goes to an email provider or SMS gateway, the function may return nothing useful. When that change lands, every existing test loses the value it asserted on. This is part 4 of a ten-part series. The code is in Java, Node.js, Go and Python.

MCP Servers 1.1.0 Add Flexible HTTP Routing and CLI Connection Management

We are pleased to announce the release of MCP Servers 1.1.0, bringing new configuration options for HTTP-based deployments and expanded command-line capabilities for managing database connections. The new version makes it easier to control how MCP Servers are exposed over HTTP, host multiple MCP Servers under a single hostname, and configure connections directly from the command line.

Cycle achieves SOC 2 Type 1: Strengthening our commitment to data security and system availability

Cycle recently went through a System and Organization Controls (SOC) 2 Type 1 audit and we've got the report. It’s an important step in our continuous commitment to data security and system availability. But are we just checking boxes for the sake of boxes or is there more behind it?

AI didn't kill tech debt, it just changed the currency you pay it in.

Ganesh Datta on why every team still has a finite budget, now it's tokens instead of headcount. $500 to spend: ship the feature or fix the P2? The orgs building a framework for that call now will have it a lot easier when the CFO puts a cap on spend. From Braintrust by Cortex. Full episode out next Thursday.

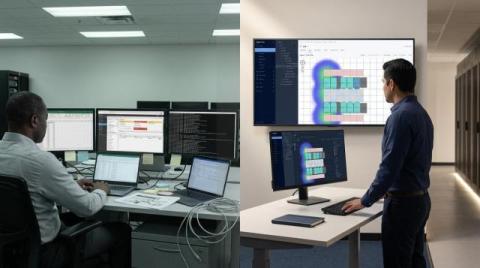
API-first DCIM: Reduce Integration Friction and Keep Control Across Tools

Disconnected tools slow your operations down more than missing data ever could. Every day, teams waste hours stitching together systems that don’t naturally talk to each other. API-first DCIM cuts through that drag, turning scattered signals into one clear operational view. With Hyperview DCIM, you connect faster, keep control, and make decisions without extra manual work.

How we create a Canonical Academy exam

Open source provides the world with access to cutting-edge software, and the learning that comes with it. But how do you validate someone’s skills in an open ecosystem? Canonical Academy is a highly rigorous, job-focused qualification platform designed to empower individuals and enterprises with industry-recognized credentials. The platform addresses a critical gap in tech: validating real-world, hands-on capability rather than rote memorization.

Cloud Cost Management for Observability: A Practical Guide

Observability spend is outgrowing infrastructure budgets. What drives the cost up, how pricing models work, and a practical framework to manage it. Sejal Pandey works on content and growth at Last9, writing about observability, reliability, and SRE practices.

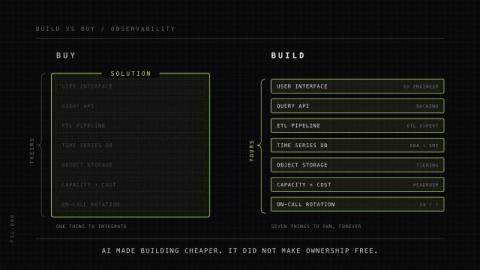
Why you should (not) build your own observability stack

If you are able to build it better than your vendor, then change your vendor. Not build it. Rishi builds large-scale observability systems at Last9, focusing on reliable and cost-efficient telemetry infrastructure, and writes about the practical lessons learned while operating ClickHouse, VictoriaMetrics, and OpenTelemetry in production.

Why compliance keeps slowing your releases (and what to change first)

A team ships at a steady pace for most of the year. Then an audit approaches, and delivery slows. Engineers get pulled off feature work to support the audit, producing the configuration exports, logs, and environment checks that the evidence depends on. The slowdown lasts as long as the audit does. It is tempting to read this as a team that needs to move faster or be bigger. It is usually neither.