Operations | Monitoring | ITSM | DevOps | Cloud

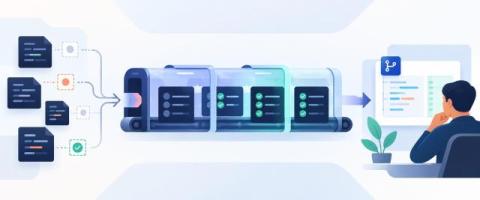
How we used Agentic Pipelines to turn test coverage into a daily habit

Engineers write tests for the logic that worries them and let the small details slide. One of our commerce engineering teams now has a scheduled agent that finds the thinly tested files, writes the missing tests, and opens a pull request for review. Nobody decides to skip a unit test. The core logic gets covered, the small details don’t make the cut, and most days that’s a fair trade.

Service Mesh Observability: Istio, Linkerd and Envoy Metrics

Service mesh observability guide: the metrics Istio, Linkerd and Envoy proxies emit, what ambient mode changes, and why tracing still needs app changes. Sejal Pandey works on content and growth at Last9, writing about observability, reliability, and SRE practices.

Not Saying No to the CEO Was Our Costliest Mistake

Not saying no to a bad call can cost you far more than an awkward conversation ever would. We were pitching schools on something nobody wanted, with no real answer to “why?” other than “the CEO said so.” Months of back-and-forth later, most of it ended up in a closet. If you think it’s the wrong call, speak up, and come with alternatives. Watch the full IT Leadership Lab session — linked above.

Managed DEX for Application Performance | Find and Resolve Issues Faster

See how Teneo Managed Digital Employee Experience (Managed DEX) helps IT teams identify the root cause of application performance issues and resolve problems faster. Teneo Managed DEX gives service desk and IT teams deeper visibility into application crashes, response times, hang time, wait time and user experience across different application versions. In this short video, see how Managed DEX can help teams.

Managed DEX for Service Desk Optimization | Improve IT Support with Teneo

See how Teneo Managed Digital Employee Experience (Managed DEX) helps IT and service desk teams identify and resolve employee technology issues faster. By giving service desk engineers greater visibility into the digital employee experience, Managed DEX helps teams understand what is affecting users, investigate problems more efficiently, and move from reactive troubleshooting toward proactive IT support.

How to End Tribal Knowledge and Make Every IT Practitioner an Expert

Every IT organization has a small group of people who hold the answers everyone else depends on, and that dependency carries a cost that never appears on a dashboard. It shows up in constant interruptions, on-call rotations that keep routing back to the same names, investigations rebuilt from scratch every time an incident resurfaces, and the pressure carried by the one person who knows how the environment behaves under stress.

Self Healing Agentic Pipeline | Bitbucket Blitz | Atlassian

Ever had a broken test stop your flow? In this Bitbucket Blitz video, we look at how to setup self-healing pipelines using Bitbucket and Bitbucket Agentic Pipelines. Instead of just failing and waiting for a human, the pipeline triggers an agent when a build or test breaks on a feature branch. The agent reads the logs, finds the root cause in the source code, creates a fix branch, and opens a pull request ready for review.

Harness AI Agents

AI is writing code faster than ever. But what happens after the code is written? Harness CEO Jyoti Bansal introduces four AI agents built to automate the software delivery lifecycle: Software Delivery Agent – Automate builds, deployments, and infrastructure management. Security Testing Agent – Find, prioritize, and fix vulnerabilities with AI. Runtime Protection Agent – Protect applications, APIs, and AI agents in production.

How to Ensure Reliability of Data in the Cloud

The reliability of data is crucial when managing files in the cloud, especially for businesses, enterprises, and even the data reliability of your own personal files. In this article, we’ll cover everything about data reliability: what it is, why it’s important, assessing the reliability of data, and cloud storage solutions to keep your data protected, accurate, and complete.
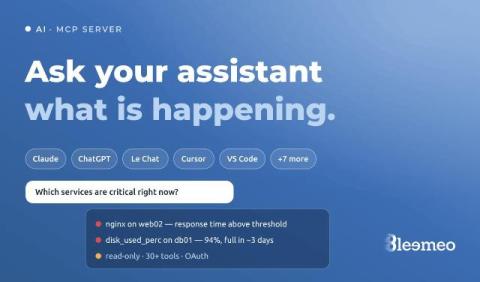
Ask Claude or Le Chat what is happening on your servers: the Bleemeo MCP server

The first minutes of an incident are spent asking questions a monitoring tool can answer but rarely in the form you asked them: which servers are in trouble right now, is it the same thing as last night, what did memory do on the web servers before it started? Each answer is a few clicks away, on a different page.