Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on Incident Management, On-Call, Incident Response and related technologies.

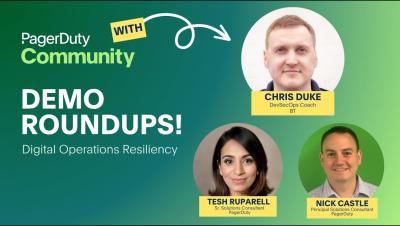
Demo Roundups! Digital Operations Resiliency

Guest Chris Duke, DevSecOps Coach at BT, explores why PagerDuty is the perfect ally for turning his organization outage-ready and shares some of their Incident Management best practices in an "Ask me Anything" session with Solutions Consultant Tesh Ruparell. Solutions Consultant Nick Castle shows how PagerDuty's Enterprise Incident Management, combined with AIOps and Automation capabilities, ensures fast incident resolution by automatically dispatching the right teams for quick fixes at scale, creating a proactive approach that helps maintain SLAs, drive innovation, and protect revenue.

Using LLMs for Automated IT Incident Management

Large language models are algorithms designed to understand, generate, and manipulate human language. State-of-the-art large language models include OpenAI’s GPT-4o, Anthropic Claude Sonnet 3.5, and Meta LLaMA 3.1. They are built using neural networks with billions or even trillions of parameters. They are trained on vast datasets that can include text from the internet, books, code, and other information sources.

Preparedness as a Competitive Advantage: Building Resilience Year Round

The recent global IT outage is a stark reminder that even the most advanced organizations can have bad days. Major disruptions can have significant downstream impacts that can lead to disappointed customers, lost revenue, deferred processes and even legal action if the downtime is considerable. With the rapid pace of technological change and the continued digital transformation intensified by AI, disruptions are no longer “unexpected.” They are part of the normal course of business.

Reduce Noise through Intelligent Alert Grouping

In an ideal world, every alert would signal a unique and critical issue. However, in reality, alerts often come in waves. Alert noise refers to the overwhelming volume of notifications that incident response teams receive, many of which may be redundant or irrelevant. This can lead to alert fatigue, where critical issues might be overlooked due to the sheer number of notifications. ‍

What does SLO stand for? A complete guide to Service Level Objectives (SLOs)

The world of tech is full of acronyms. SLOs are one of those that everyone talks about, but maybe not everyone fully gets. Whether you're nodding along in meetings or just hearing “SLO” for the first time, we’ve got you covered. In this post, we’ll break down what Service Level Objectives (SLOs) actually are, why they matter, and how they can help keep your systems (and your sanity) in check.

The ultimate guide to on-call schedules

An Ultimate Guide to on-call schedules? You might think this sounds overly grandiose for what’s essentially putting people into a list and rotating through them. But you’d be flat-out wrong. Getting your on-call setup correct is as real and as important as it gets, and getting things wrong can lead to prolonged incidents, burnt out employees, and damaged company reputation.

Custom Milestones: Empowering Enterprise Incident Management

Milestones have been central to our platform since day one, helping users track incident progress and drive automation. We're excited to introduce our enhanced Milestone feature, offering unparalleled customization. Now, you can fine-tune your incident management process to perfectly align with your organization's specific policies and workflows.

4 New Ways to Improve Incident Management with Event Orchestration

In an era where efficiency and smart technology integration are key, 71% of technical leaders report their companies are expanding their investments in artificial intelligence (AI) and machine learning (ML) this year. With the sheer volume of data coming into the enterprise and the need for timely response, monitoring every incoming alert around the clock is impractical, and human vigilance alone is too imprecise.

Myth vs. Reality: Lessons in Reliability from the July 19 Outage

It was 3AM at Newark Liberty International Airport. I was groggy, waiting in line to get my boarding pass, only to be met with a blue screen on the check-in kiosk. Needing some coffee, I learned the vendor was only accepting cash. There was clearly a big outage and I quickly checked our systems at PagerDuty. Major outages happen multiple times per year, so frequently that we have an internal dashboard (colloquially referred to as “the internets are broken”).

6 top incident management use cases for AI copilots

The news is filled with buzz about how companies approach AI. As a result, many organizations are trying to identify how AI can effectively support their business goals. There seem to be infinite use cases, but finding those that add the most value is often the first challenge. In the ITOps environment, generative AI copilots can effectively improve team efficiency, share knowledge, and support day-to-day tasks to deliver immediate value.