AWS Marketplace + FireHydrant: your path to easier compliance, consolidated spend, and faster procurement.
Over the last 18 months at incident.io, we’ve done a lot of migrations. Often, a new feature requires a change to our existing data model. For us to be successful, it’s important that we can seamlessly transition from the old world to the new as quickly as we can. There are few things in software where I’d advocate a ‘one true way,’ but the closest I come is probably migrations. There’s a playbook that we follow to give us the best odds of a smooth switchover.
At incident.io, we deal with small incidents all the time—we auto-create them from PagerDuty on every new error, so we get several of these a day. As a team, we’ve mastered tackling these small incidents since we practice responding to them so often. However, like most companies, we’re less familiar with larger and more severe incidents—like the kind that affect our whole product, or a part of our infrastructure such as our database, or event handling.
When a serious incident occurs, time is essential. Streamlining different components of the incident response and management process can help minimize the time it takes to resolve an incident. Proper streamlining also helps reduce downtime, restore functionality, and potentially curtail the overall impact of an incident-not to mention the costs incurred during these events. This article examines several areas of incident management, the potential challenges of manual implementation, and how an automation platform can alleviate these challenges to provide a streamlined incident response process.
Alert notification software is an essential tool for IT operations, as it enables teams to quickly respond to critical issues and ensure the smooth running of systems and services. With the increasing complexity of IT environments, it is more important than ever to have a robust alerting system in place. General robustness is essential as such alert notification system will quickly become an essential part of your operation stack.
In the age of Big Data and analytics, companies are increasingly using the power of numbers and data to improve their processes. In the incident management world, this means turning to KPIs, metrics, and other incident monitoring methods to recognize trends and take corrective action. To manage and improve your incident management processes, you have to keep an eye on KPIs and metrics.
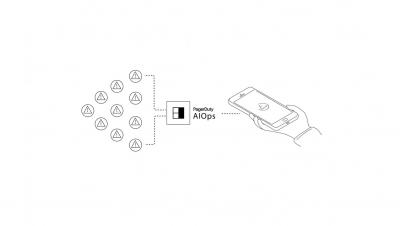
Most organizations suffer from some form of alert noise, shares Adam Blau, senior director of product marketing at BigPanda. “Alert noise is only going to increase as organizations support cloud-native applications spanning multiple public and private clouds, including ephemeral deployments and more. It’s not going to get easier for organizations to understand the signal from all those alerts being sent,” Blau said.
The PagerTree iOS (iPhone) app now supports Critical Alerts bypassing do not disturb and the mute switch! A new version of the PagerTree is available today that adds support for Apple's Critical Alerts.
A seemingly straightforward technical problem can often have explosive consequences. Say a tech team restarts a cloud server overnight; those few minutes of downtime might trigger a problem elsewhere and cause your app to crash. The following morning, customers can't access your services, you're trending on social media for all the wrong reasons and your customer service reps are left to pick up the pieces. Scenarios like this prove the value of incident management. But you need best practices that ensure incident management does what it's supposed to do. Otherwise, it's just another buzzword. Here are some best practices for incident management that you need to incorporate into your tech organization.
On-call availability is crucial for many industries, especially in IT. With the growing reliance on IT systems and services, their availability directly impacts the success and satisfaction of customers. To ensure round-the-clock availability, on-call services are vital for prompt responses to emergencies and issues.
Will artificial intelligence (AI) end up emphasizing the importance of human emotions? What’s next for company operating budgets? And is a reckoning coming for managed service providers (MSPs)? In a recent episode of our That’s great IT podcast, we invited an expert panel to discuss all of this and more. The panel consisted of three returning guests: They shared the top IT trends they’ve seen in their industries and how they expect those trends to play out in 2023.
In the world of enterprise major incident management, integrating partial or full automation across each stage of the incident response and management lifecycle makes a big difference to the speed incidents are addressed and the data you have to understand them afterward. Gartner coined the term “Incident Response Automation” in its 2020 report Automate Incident Response to Enhance Incident Management.
Working with technology means dealing with incidents or outages from time-to-time, so staying on top of problems is essential. Back in the spring of 2022, Clearco, the world’s largest e-commerce investor, had an alerting system set up to catch issues, except they had one problem: Clearco’s Customer Success team would learn of a problem before a notification even went off.
The outages span the giants of the Internet and some of the biggest failures of IT resilience we were subject to – from AWS’s trifecta of outages in December 2021 to the October ‘21 outage that took down Facebook, Instagram, WhatsApp, and interrelated services. We also look at some more intermittent outages that you may have missed.
You’ve probably heard the phrase “transparency is key” more than you can bear at this point—so let’s get this out of the way. Transparency is key. The phrase suddenly became that much more unbearable. But before you drop off, let me also communicate something else: transparency is often not enough. Often, companies make the mistake of leaning on transparency as a catchall solution to many of their internal comms issues.
Budgets are a touchy subject for anyone, and there’s no one-size-fits-all approach. However, the work ITOps does is integral to the success of your organization, so being confident in building and defending your budget is crucial to getting the resources you need. So what does success look like when it comes to ITOps budgets? In our recent podcast episode from our series, That’s great IT, I sat down with global IT leader Nigel Peacock to discuss the best ways to justify your ITOps budget.
Users have been generating increasing amounts of data in the past few years, partly due to rapid digitalization since the pandemic. As a result, increasing numbers of analytics applications are capitalizing on these data assets. However, building scalable systems is no trivial task and incidents are inevitable. Complex systems generate data in the form of logs, traces, metrics, and more, which organizations often find themselves sprinting through. Such logs are a powerhouse of valuable information.
We are pleased to announce that Interlink Software’s AIOps and Observability platform is now a fully validated third-party solution on VMware Marketplace residing in the Management and Monitoring category.
We’re all looking to maximize every dollar spent, every hire made, every hour logged. But there’s one cost center you might not be thinking about — incident management. This post explores the explicit and implicit costs associated with incidents.
Tech saw a lot of challenges in 2022. ITOps, NOC, and SRE teams grappled with shifts in staffing, a disappearance of those with tribal knowledge, a continuing transformation of consumer spending habits, and a general disruption of workplace culture. So what will 2023 look like for the industry? Likely, more volatility—but our panel of industry experts are here to help you navigate the choppy waters while also making some bold predictions. Change is the only constant in the tech sector.
Recent talks of an economic softening have left IT leaders concerned about the future of their enterprises. That concern is understandable — tech layoffs create near-daily headlines at this point, with top companies rolling back their operations and rolling up their sleeves to focus on mission-critical expenses. And for many in ITOps, that means cutting tools.
If you are a new IT professional or manage a young team of IT staff, you know it too well how intimidating it is to be assigned to an on-call rotation for the first time. You might be asking yourself questions such as, “Will an outage or breach unfold? Will I sleep through an alert?
Everyone loves a good mystery thriller. Ok, not everyone – but Hollywood certainly does. Whether it’s Sherlock Holmes or Hercule Poirot, audiences clearly enjoy a page-turning plot of hunting down the culprit for some heinous crime.
Automating processes and the tools that enable them is vital for empowering highly productive teams. The right automation tools and workflows help DevOps and SRE teams minimize repetitive tasks, improve monitoring capabilities, enable continuous integration/continuous deployment (CI/CD), and work with massive volumes of data.
For many businesses across the world, incident management is something that’s usually left to engineers. These teams are on the front lines, declaring, managing, and resolving all sorts of incidents across the org, regardless of where it originates or what form it takes. But there’s a glaring issue with this approach. Outside of technical teams, people across organizations aren’t accustomed or trained to use the word “incident” whenever an issue comes up.
As security becomes more advanced and available, companies must look for ways to be more efficient with their resources in order to stay competitive. With challenges that limit the capabilities of companies, such as limited employee resources and low customer tolerance for delays in services, reliable and affordable solutions are necessary. In this case, it means disrupting the traditional security industry. Organizations are achieving their goals by relying on automation and technology.
A software incident is an event or unplanned interruption that causes the software to deviate from its intended behavior, affecting the quality of service. With the ever-changing nature of the software industry, incidents are inevitable, particularly in teams that practice iterative software development cycles with constant releases to production. This necessitates a robust incident management strategy.
Unable to send, receive, or search email through Exchange Online? Microsoft Outlook suffered an outage for several hours last night, disrupting North America and worldwide email services.
Having your systems monitored by a reliable solution is important, but how do you ensure that the right people are informed about issues that arise? Identifying problems is the first step, but they also need to be routed to the appropriate individuals. Keep in mind that employees may not always be sitting in front of the dashboard. This means being available outside of normal working hours to quickly respond to emergencies and problems, including not only weeknights but also weekends and holidays.
Operations, customer support, engineers and most groups use inconsistent language. This is a serious problem. Imagine NASA doing that with astronauts or a navy with ships talking to each other, but not using the same terms. Something very bad will happen. In our space of incident management, we use words like broke, failed, outage, doesn’t work, dead…all describing the same condition.
Learn how to effectively respond to incidents and ensure business continuity with these incident management best practices.
Incidents can be a bit noisy. Especially when it’s one of higher severity, there are a lot of moving parts that can make it difficult to come away with the information you want at a glance. And if you’re someone who isn’t necessarily tapped into the day-to-day of incident response, such as a head of a department or executive, you’ll want to be able to glean the most actionable information in just a few seconds without having to dig through dense documents.
Site reliability engineers (SREs) are involved in scaling systems and making them reliable and efficient for organizations. But SREs often fail to build system resiliency when they do not have the right tools at their disposal. In this post, we’ll uncover the top 5 tools for SRE that can be used to drive the reliability and stability of software systems. It also examines how SREs can use the tools to improve operations tasks and infrastructure processes.
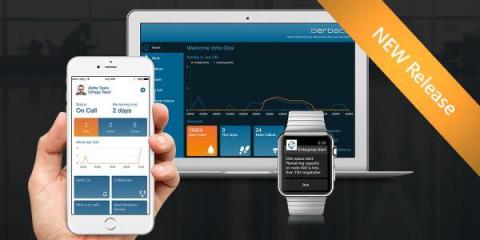
In this release, we have addressed a number of bugs that were impacting the performance and functionality of the system. In the Kernel, we have resolved an issue where the broadcast was not being stopped after the first user acknowledged it. Additionally, we have fixed a crash that was occurring when loading component infos and an error log that was being generated when the Kernel started in suspended mode.
The last few years have led to an increasingly digital world. We are all online, streaming, shopping, or simply surfing. In this new world, customer experience is more critical than ever. Customers want things to work as seamlessly as possible, and when things go wrong, so goes their trust and business. The key priority for many businesses is keeping those systems running as smoothly as possible to keep customers happy and build their loyalty.