Operations | Monitoring | ITSM | DevOps | Cloud

Chart a course for Operational Excellence with PagerDuty's Operational Maturity Model

A top priority for many technical leaders is improving the performance and efficiency of their teams to maximize results and minimize costs. With the PagerDuty Operational Maturity Model, IT teams can reduce the total cost of ownership with better efficiency, mitigate the risk of operational failure to ultimately protect customer experience, and shift from a reactive state towards a more proactive approach—by using the PagerDuty Operations Cloud.

The Unplanned Show, Episode 32: Platform Engineering with Paula Kennedy

Supporting developer velocity AND operational efficiency, stability, and security doesn't happen by accident. In this episode, Dormain will sit down with Paula Kennedy to discuss how platform engineering supports businesses go faster, decrease risk, and increase efficiency.

SIGNL4 Onboarding: Customizing Alerts and Notifications

The SIGNL4 Onboarding series walks users through the process's of SIGNL4 from Signup to Alerts to Settings. Today's video focuses on using Overrides to enable different alerting options during different dates and times. This video is packed with helpful tips to help you get the most out of your account.

PTO peace of mind: Sync Grafana OnCall with Google Calendar out-of-office events

Sometimes, the little things can make a big difference. We’ve added a new feature in Grafana Incident & Response Management (IRM) that lets you sync your Google Calendar out-of-office events with Grafana OnCall.

The rising costs of downtime

IT outages are a financial nightmare. Beyond revenue impact, unplanned downtime translates to lost productivity, frustrated customers, and potential reputation damage. To understand the true impact of these events, Enterprise Management Associates (EMA) conducted a comprehensive study with more than 400 IT professionals from varying company sizes and roles in North America, EMEA, and APAC regions.

Operational Excellence at the New York Stock Exchange: Our Q&A with NYSE's President

Mitigating the risk of operational failure is top of mind—and a top budget priority—for executives. A single unplanned event can have a disruptive effect across the organization, an outcome management teams work hard to avoid. For the New York Stock Exchange (NYSE), operational resilience is critical given the role it plays in the global economy and capital flows.
Takeaways from BigPanda 24

Last week saw several big milestones for BigPanda. We launched several new AI-driven capabilities (see below). And we had the privilege of meeting with more than 40 IT operations leaders from customers, including Disney, Nvidia, Autodesk, Lucid Motors, Intel, and Blue Shield, at our customer event, BigPanda 24. Representing some of the most innovative organizations in business and technology, these influencers joined us as part of our customer and technical advisory boards.

xMatters Vanguard Release

When all systems are firing, managing your incident management processes can feel a little out of this world. For this release, we've packed in more features than can fit into the City of Mystery. But never fear! You don't need to be part of a space program to join this intergalactic quest. All xMatters instances now include powerful new features and updates from our latest release: Learn more about these features and all the other exciting updates in our ‍ Vanguard Release Overview‍.

Reduce MTTR with BigPanda Similar Incidents

There’s wisdom in past experiences — if you can access it. During live incidents, teams often look for parallels to past situations in their investigation process. Finding the answers is a time-consuming and manual process. You first have to identify similar incidents, then review historical data for insights and details on how previous teams resolved them. There’s no time to waste when SLAs are at stake. Yet that’s how many operators spend their time.

Beginner's Guide to Kubernetes Troubleshooting

Kubernetes troubleshooting is a critical skill for developers and system administrators managing containerized applications. It involves diagnosing and resolving issues within a Kubernetes cluster, ensuring that applications run smoothly and efficiently. Troubleshooting can range from simple configuration errors to complex networking issues, requiring a deep understanding of Kubernetes architecture and components.

Status Page automation with Playbooks

"🚀 Automate Your Status Pages with Playbooks! 🚀 In this video, we're diving deep into the world of incident response automation. Join us as we explore how you can streamline your status page updates with Spike's powerful Playbooks feature. Learn step-by-step how to create and configure Playbooks to automate your status page notifications, ensuring your stakeholders are always kept in the loop during incidents. With a live demo and practical insights, you'll discover how easy it is to set up automated responses tailored to your organization's needs.

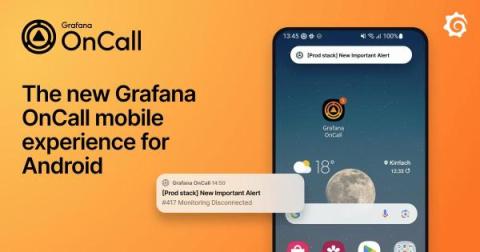
Grafana OnCall mobile app notifications: The new and improved experience for Android users

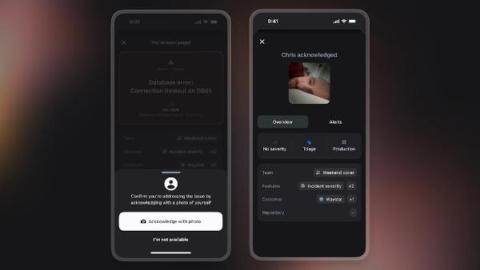
The Grafana OnCall mobile app is an essential tool for on-call engineers to monitor and respond to critical system events. Available for both iOS and Android, the app offers a range of features and notification settings that make the on-call experience easier and more intuitive — all in the palm of your hand.

Recapping our live event: On-call as it should be, present and future

The launch of On-call was an integral part of the incident.io mission to become the single place you turn when things go wrong, and recently we hosted a live virtual event to show how it all came together. In this event, incident.io Co-founder and CTO Pete Hamilton sat down with incident.io Product Manager Megan McDonald, Product Engineer Rory Bain, and fellow Co-founder and CPO Chris Evans to demo the product, discuss the journey of the creation, and expand on what’s next.

Expanding Critical Services with the PagerDuty Operations Cloud

For someone experiencing a mental health or substance abuse crisis, receiving timely access to care is critical. Recognizing a growing need for behavioral health intervention, San Diego County launched its Telecare Mobile Crisis Response Team (MCRT) to provide no-cost, in-person support. “With mental health crises on the rise, counties are trying to figure out how to implement something that supports folks in the community,” said Bre Lane, Program Administrator at MCRT.

Why action items shouldn't be the goal post-incident #incidentmanagement #podcast

In this clip, Colette explains why focusing on coming up with a list of action items post-incident is a big mistake. About the episode: What if we told you that everything you thought you knew about incident response was wrong. Well, at least some of it. That some of the things you’ve been doing for years might not actually be having the impact you thought they did. Or, even worse, that some of the assumptions you’ve been making have actually been having a negative impact on you, your team and your organization.

The issue with DORA metrics #incidentmanagement #podcast

In this clip, Colette explains what the underlying issue is with DORA metrics. About the episode: What if we told you that everything you thought you knew about incident response was wrong. Well, at least some of it. That some of the things you’ve been doing for years might not actually be having the impact you thought they did. Or, even worse, that some of the assumptions you’ve been making have actually been having a negative impact on you, your team and your organization.

Enhancing Team Collaboration: Unveiling the Intuitive Features of SIGNL4

Effective communication lies at the heart of successful teamwork, and SIGNL4 emerges as a powerful tool crafted to elevate collaboration within teams. In this blog post, we will explore five of the often small but all the more intuitive features that distinguish SIGNL4, positioning it as the preferred solution for teams aiming to enhance productivity and streamline communication.

AI-driven contextual mastery for incident response

Context is fundamental to well-run tech operations, which require an understanding of systems, services, architectures, and teams to interpret the real-time data streaming in from observability and change systems. The delivery of context is crucial for effective operations performance. And it’s a universally important skill set for tech Ops teams to master.

BigPanda delivers full context for faster, scalable AIOps

The teams that keep IT services running all share one thing: a need for data and knowledge that spans their systems and tools. Yet, they often lack the vital cross-system context necessary to analyze and collaborate effectively to remediate incidents quickly. BigPanda is proud to announce new features and capabilities that enable you to leverage historical incident records and institutional knowledge.

Overview of Playbooks - Incident response automation

Playbooks are a powerful tool to automate common actions in your incident response process. It's like a pre-programmed sequence of steps your team should take when specific incidents occur. Instead of scrambling to remember protocols or manually initiating a series of tasks, responders can activate a Playbook with a single click. This triggers a predefined set of actions, such as notifying team members, setting incident severity/priority, or creating support tickets, all tailored to the nature of the incident.

The Role of Automation in Incident Management: Improving Response Time and Accuracy

Organizations in the 21st century are growing at a staggering rate, expanding their operations over a global network and dealing with more data than ever before. These widespread operations and processes also mean that there are infinitely more possibilities for businesses to run into problems, have an incident occur, and have to deal with the resulting consequences.

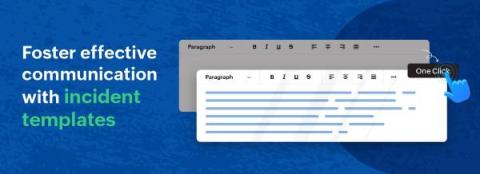
Deliver efficient communication through incident templates

Imagine this scenario: Imagine this scenario: You are a user of an online service, and suddenly you encounter a technical glitch. You head to the status page for updates, expecting clear information about the issue. However, you are met with vague or unstructured updates, leaving you uncertain about the severity and resolution timeline of the problem.

The role of psychological safety in incident response

Incidents impacting your customer and user-facing services can be stressful, both for the responders on your team who are working on a resolution, and for the other stakeholders in your business. For teams to solve incidents quickly and effectively, responders need to be able to trust each other and stakeholders have to trust the responders. This level of trust is hard to cultivate if your organization doesn’t have a significant amount of psychological safety.

Why EHR Secure Chats Don't Cut It: Top 10 Reasons

Electronic Health Records (EHRs) have evolved from mere repositories of patient data to indispensable tools at the forefront of patient care. They serve as the single source of truth across the patient care continuum, empowering care teams to make informed clinical decisions. Effective implementation of these systems leads to improved patient outcomes, reflected in lower hospital readmission rates and shorter average length of stays (LOS).

Our customers aren't just numbers-they're a priority

At incident.io, “We care about our customers” isn’t just a talking point. It’s a core part of how we operate. Whether it’s a big feature request or a small bug fix, we’ve been intentional about making sure that customers always feel heard and seen—no matter the ask. But it’s not just that.

Root Cause Analysis (RCA), Explained

Root Cause Analysis (RCA) is the best way to find out what causes an issue in your IT operations (ITOps). In other words, it is a great versatile analysis method for corrective action that is inherent to the ITIL framework. It’s a comprehensive approach that all managers can appreciate. In the IT industry, this method is invaluable since its ability to swiftly and effectively address problems is what distinguishes proactive IT Service Management (ITSM).

Mobile Alerts for Icinga at Net at Work

Net at Work is a German IT company with over 100 employees that provides its customers with solutions and tools for digital communication and collaboration. Their product NoSpamProxy offers reliable protection against spam and ransomware, legally compliant email encryption and more. Net at Work customers monitor NoSpamProxy with a network monitoring tool.

Stay up to date on the latest incidents with Bits AI

Since the release of ChatGPT, there’s been growing excitement about the potential of generative AI—a class of artificial intelligence trained on pre-existing datasets to generate text, images, videos, and other media—to transform global businesses. Last year, we released our own generative AI-powered DevOps copilot called Bits AI in private beta. Bits AI provides a conversational UI to explore observability data using natural language.

Introducing Playbooks automation

We're rolling out Playbooks, our latest in fully automating the incident response process. Imagine every action you (incident responders), had to manually take are now fully automated with Playbooks. Steps like initiating a war room (video conference), logging incidents, sending out alerts, and running diagnostic scripts are now executed with precision, every single time, are all now effortlessly automated without you lifting a finger.

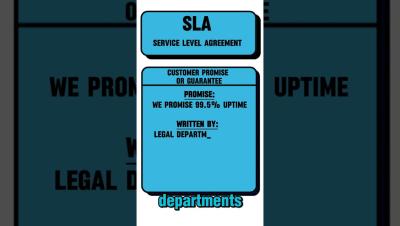
SLA Service Level Agreements #SLA #Service #Level #agreements

Service Level Agreements, or SLAs, are essentially a promise or guarantee from the service provider to the customer. They outline the expected level of service, detailing the products or services to be delivered as well as the consequences for missing these service levels. SLAs are typically drafted by legal departments with insights from product managers and are designed to be customer-facing. It sets the stage for accountability and sets clear expectations right from the start.

The Debrief: Building a strong culture of engineering #incidentmanagement #softwareengineer

Whether you’re a seasoned company with 10+ years of operations, or a startup that’s just getting off the ground, making sure you have a good culture of engineering is really important. Not only will this have a significant impact on the folks on your team, it’ll make a big difference with hiring. When everyone knows that your company is the place to be when it comes to culture, attracting really good talent becomes that much easier.

The Debrief: On-call was just the beginning-reflecting on Q1 2024 #incidentmanagement

Q1 2024 is officially behind us. So we figured that it was a great time for a bit of reflection on the exciting start to the year. In this episode, we sit down with our founders, Stephen, Chris, and Pete, to get a bit of perspective on how the last three months played out. We chat about On-call, our AI launch, and the hundreds of other features, bug fixes, and bits of polish and delight that we've shipped over the last 12 weeks.

SLA vs SLO vs SLI: Whats the Difference?

In this video, we cover the key differences between SLA, SLO, and SLI defining each term and giving real world examples of how they differ. This video was brought to you by PagerTree. On-Call. Simplified. Transcript: SLA vs SLO vs SLI Whats the difference? In this video, we will define these terms, compare them to one another and give real-world examples of how they work.

Shifting left on incident management

In the fast-paced world of software development and product delivery, incidents are often viewed as unwanted disruptions. Traditionally, incident management might only trigger for critical issues, like complete system outages, data loss of some kind, or security-related ones - you don’t need to go back that far for a few that were very serious: Heartbleed, xz utils, and more.

incident.io On-demand: On-call as it should be, present and future

Since the inception of incident.io, we set out to build the single destination companies turn when things go wrong. With the release of On-call, we’ve achieved just that. From waking your team up at 2am to gleaning insights from incidents, we’ve got you covered. From our sleek, intuitive mobile app to customizable workflows, incident.io is built for the way modern teams actually work—featuring a robust platform of Response, On-call, and Status Pages.

#6 Virtual Meetup: PagerDuty Session: James Pickles (Solutions Consultant @ PagerDuty).

Elevate your biz & enhance your automation skills! Get together with the Rundeck by PagerDuty Process Automation crew and learn how automation is leading the way to innovation and fast tracking business for the future!🚀 Hear success automation stories from Diego Infiesta (IT Infrastructure Manager @ Ryanair) & Hans Erasmus (Director @ HBPS Consulting), and dive into the world of open-source automation with James Pickles (Solutions Consultant @ PagerDuty).

How Incidents Foster Leadership

To become battle-tested, you need to go through battles, not just read books or mentor newcomers. Both are helpful but the stakes are low. On the other hand, high stake jobs, such as running a big project or managing a team, are hard to get when you lack experience. So how can we solve this dilemma? Enter incident response.

The Challenges of Rising MTTR - And What to Do

Data volumes are soaring. Environments are increasingly intricate. The risk of applications and systems encountering breakdowns is sky-high, and the mean time to recovery (MTTR) for production incidents is moving in the wrong direction. Disruptions not only jeopardize critical infrastructure but also have a direct impact on the bottom line of organizations. Swift recovery of affected services becomes paramount, as it directly correlates with business continuity and resilience.

Why you need an incident lead

In this clip, Adrian explains why it's important to have a dedicated incident lead. More about this episode: Today, good incident communication isn't a nice to have—it's an absolute must. But where do you even start? To help answer that question, we sat down with the VP of Engineering at SumUp, ⁠Adrián Moreno Peña⁠, to get his perspective on how organizations of all sizes can share stellar comms no matter the situation.

How SumUp benefitted from using incident.io

In this clip, Adrian explains how SumUp benefitted from using the incident.io platform. More about this episode: Today, good incident communication isn't a nice to have—it's an absolute must. But where do you even start? To help answer that question, we sat down with the VP of Engineering at SumUp, ⁠Adrián Moreno Peña⁠, to get his perspective on how organizations of all sizes can share stellar comms no matter the situation.

Building trust through incident communication with Adrián Moreno, VP of Engineering at SumUp

Today, good incident communication isn't a nice to have—it's an absolute must. But where do you even start? To help answer that question, we sat down with the VP of Engineering at SumUp, ⁠Adrián Moreno Peña⁠, to get his perspective on how organizations of all sizes can share stellar comms no matter the situation. We discuss: What it means to communicate during incidents Why Status Pages are critical in helping to build trust How you can have good comms even without a lead...and much more.

incident.io is leading the charge in incident management for G2's Spring report

We’re ecstatic to announce that we’ve been ranked #1 in G2’s Relationship Index for Spring 2024. G2's Relationship Index is a measure of several factors, including: This award means a lot to us as it’s a direct result of the partnerships we’ve built with customers—and it’s a recognition we’re very proud of. From the beginning, we’ve been laser-focused on being the single place you turn to when things go wrong.