Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on Incident Management, On-Call, Incident Response and related technologies.
Network topology: Definition and role in observability

Network topology describes how a network‘s nodes, connections, and devices physically arrange and interconnect, as well as how they communicate. The arrangement or configuration of a network’s components plays a crucial role in ensuring smooth ITOps with minimum downtime. Any issues in the network can disrupt operations, leading to potentially dire consequences. To prevent this, you need to understand your network functionality and structure.

Demo Roundups! Scale Support Teams with PagerDuty's CX Operations

PagerDuty’s Solutions Consulting Team Lead Michael Aravopoulos presents an exclusive live demo showcasing PagerDuty's Customer Service Operations capabilities. Identify and address issues before they affect your customers Automate incident discovery and response to deliver streamlined digital experiences Facilitate communication and coordination between customer service and technical team.

Effective Slack on-call protocols for engineers

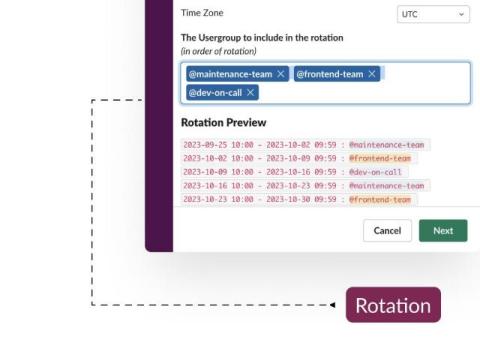
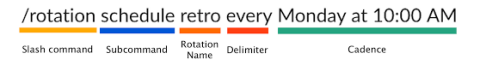
Talks about being on call are usually met with complaints. Here's how to alter the narrative and develop a stronger, more compassionate process. A few years ago, I took oversight of a significant portion of our infrastructure. It was a complex undertaking that, if not managed and regulated properly, could have resulted in major disruptions and economic consequences over a large area.

Protocols for Transfer while using Slack

This article likely addresses challenges and considerations in implementing transfer protocols within an on-call and incident management workflow. Transfer protocols are crucial for ensuring the seamless handover of responsibilities and information between on-call personnel during shift changes or the escalation of incidents. Ensuring that all relevant details and context are effectively passed on helps prevent misunderstandings and delays in resolving critical issues.

Steps to AIOps maturity: Establish actionable incidents

Lack of communication between IT operations and ITSM teams results in data silos. And data silos make it challenging, if not impossible, to solve problems efficiently. One-third of ITOps professionals say that gathering business context is the biggest challenge to effective incident response and management, according to EMA Research.

Evaluating Opsgenie Alternatives in 2024

In today’s digital age, customer expectations are at an all-time high, with demands for instant support, flawless user experiences, and constant service availability. This environment of heightened expectations pushes organizations to innovate and streamline their operations continuously. Ensuring seamless service delivery hinges on the ability to detect and resolve issues swiftly, whether they are server crashes, software bugs, or unexpected outages.

The Debrief: Debriefing on the Crowdstrike incident

In this episode, Norberto (VP of Engineering) and Lawrence (Product Engineer) delve into the recent CrowdStrike incident that began on July 19th. Rather than focus on technical specifics, they provide a thoughtful exploration of key aspects that matter to us at incident.io, such as effective communication, overall response strategies, and proactive problem-solving during crises.

Beyond MTTR: 7 incident metrics that matter and 3 that don't

Pets.com was an online pet supply retailer founded in 1998, during the dot-com craze. In February 2000, it raised $83 million to go public based mainly on metrics like user acquisition, website traffic, and brand recognition. However, the profit margins were minimal and the marketing costs exorbitant, which led Pets.com to file for bankruptcy nine months after its IPO. The industry now recognizes these metrics as vanity metrics.

Execution Incident management on Slack

‍ ‍The article discusses streamlining on-call and incident management, focusing on the implementation of a new workflow. One key issue highlighted is the complexity of integrating various tools and platforms used for incident response, which can lead to fragmented communication and delayed resolutions. Another challenge is ensuring the efficiency of escalation protocols, where delays or missteps can impact response times.