Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on Monitoring for Websites, Applications, APIs, Infrastructure, and other technologies.

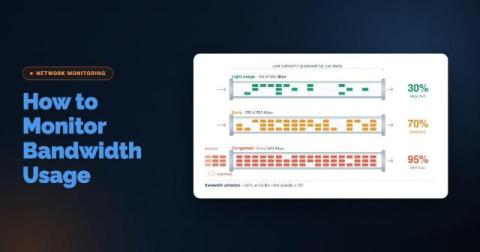
How to Monitor Bandwidth Usage: Techniques, Tools & Troubleshooting

Your Internet link averages 40% utilization, yet users still complain that calls drop and SaaS apps crawl every morning at 9:00. Averages are where bandwidth problems hide. A five-minute polling interval can smooth a 30-second saturation spike into a flat, healthy-looking line. A total-usage graph also won't tell you whether the traffic is a backup job, a compromised endpoint, or an ISP delivering less than you're paying for.
Cribl On Your Coffee Break Episode 20 - Keep learning, keep growing, keep Cribl-ing!

As we wrap up our month-long series, we look at the resources that will help you keep learning and growing - from Cribl University to Sandboxes to the Cribl Community and beyond. By the time the month is over, you will have a pretty good idea of what Cribl can do, and how to do it. You’ll also have consumed more caffeinated beverages than is strictly appropriate...

What DEX Leaders at Truist and GSK See That Your Dashboard Doesn't

An HR colleague at GSK was having trouble with her screen. The default fix was the obvious one: give her a bigger monitor. She turned it down. What she truly needed was an accessibility tool to magnify what was already on the screen she had. Sarah Jones, Senior Director, Global Site Operations and Executive Services at GSK, shared that example in a recent HR Grapevine feature on Women in DEX, the global collective Nexthink launched in March.

Latest Log Management Strategies in 2026: From Raw Logs to Business Value

Discover the latest log management strategies for 2026 and learn how AI and automation turn raw logs into actionable insights. See how modern log management can reduce investigation time, improve incident response, control costs, and strengthen visibility across hybrid and multi-cloud environments.

How to Fix Slow DNS Lookups Across Clients, Resolvers and Networks

Why does every page, login and business application hesitate before anything loads, even when bandwidth graphs look healthy? That pause usually comes from name resolution: no connection starts until its hostname has been translated into an IP address, and whatever time that translation takes is added to the request. Slow DNS seldom shows up as a clear error.

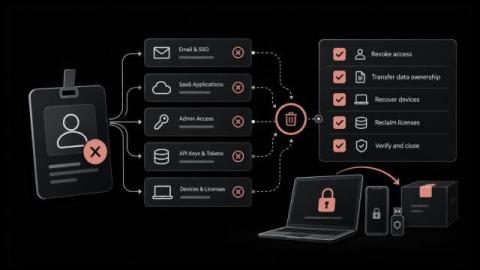
IT Offboarding and How to Revoke Access Without Leaving Security Gaps

When someone leaves your organization, how sure are you that every account they could reach was closed? Most IT offboarding starts by disabling the employee's main login account, and that step usually works. The risk comes from the other accounts, tools and devices the person used that the main account does not control. These include personal API tokens, shared vendor portal logins, laptops still with a courier and SaaS tools bought on a department card.

Extend Datadog RUM and Product Analytics to Shopify and Salesforce

Many revenue-critical interactions, such as ecommerce checkouts and customer portals, run on Shopify and Salesforce. But engineering teams have less control over the frontend runtime on these platforms, and this lack of control can make user monitoring difficult to implement and maintain. These monitoring limitations can leave gaps in visibility across important parts of the user journey.

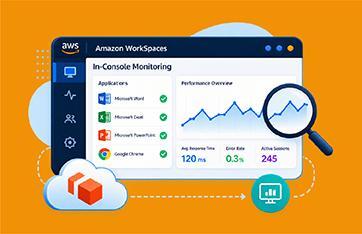
Amazon WorkSpaces Applications In-Console Monitoring

Recently, Amazon announced WorkSpaces Applications in-console monitoring. This is a big shift forward for AWS, who is quietly building market share with their Amazon WorkSpaces Applications (previously called Amazon AppStream 2.0) virtual applications offering. This announcement validates that observability matters for Amazon WorkSpaces Applications customers – they need to see what’s going on in their virtual application and desktop fleets, hosts and sessions.

Best Kubernetes monitoring tools compared in 2026: A buyer's guide for SRE, platform engineering, and ITOps teams

Monitoring Kubernetes in production is structurally different from monitoring traditional servers: pods are ephemeral, nodes autoscale, and the layered resource model—containers, pods, nodes, namespaces, deployments, services—creates an observability challenge that tools built for static infrastructure were never designed to handle.
Sponsored Post

How to cut AI infrastructure spending without reducing GPU capacity

Every infrastructure leader running AI workloads is staring at the same problem: GPU spending keeps climbing, the finance team wants a justification, and the operations team is caught between proving the infrastructure is necessary and explaining why the returns aren't keeping pace with the investment. The instinctive response is to either procure more capacity to handle growing demand or cut back on what's already deployed. Neither actually solves the problem.