Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on Incident Management, On-Call, Incident Response and related technologies.

How to Investigate a Production Incident Using an AI Agent (AppSignal MCP)

An incident has hit your product. I've been there: you're context-switching between hosting, CI/CD, codebase, AppSignal for monitoring, and whatever else your product depends on to minimize downtime and potential losses. You're trying to piece everything together, but it takes a lot of time, and that's something you don't have. AI agents connected to your tooling and your monitoring data via MCP free up that time for you.

Reduce duplicate alert noise with Alert Deduplication

A single incident can generate the same alert several times in quick succession. These duplicate alerts create unnecessary noise and alert fatigue, and make it harder for on-call teams to focus on the issue that needs their attention. OnPage Alert Deduplication reduces repeat notifications while preserving visibility into every incoming alert.

What data sources does agentic ITOps use

Agentic IT operations have arrived. It’s no longer a question of if enterprise IT departments will adopt agentic ITOps, but how quickly. The question we hear most often at BigPanda isn’t “what are agentic ITOps,” it’s “what data do we actually need to get started?” That’s the right question to ask. Agentic AI is only as good as the data and context that feeds it. Real-time observability and telemetry data from machines. Structured ITSM and workflow records.

AI Is Outpacing Code Review. Here's How to Catch Up (Without Slowing Down)

In a 2025 analysis spanning over 100 large language models, Veracode found that nearly half (45%) of AI-generated code causes known security issues and vulnerabilities. Novel risks are being introduced into your operations systems faster than humans can manage or review. At the same time, studies suggest that human review isn’t all that effective, especially beyond 400 lines of code. But AI-generated code isn’t inherently bad. It just doesn’t always work across your whole system.

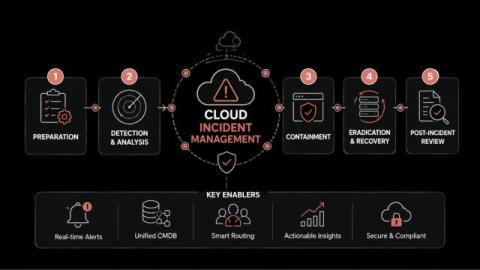
Cloud Incident Management: Process, Tools, and Practices

How do you resolve an outage your organization has no authority to fix? A managed database drops into read-only mode and stops accepting writes. There's no host to reach, no configuration file to edit, and no restart command available to your engineers. Cloud incident management begins at that boundary, where the response depends on a support channel and a provider status page. Plenty of what you already know still applies here.

How to build a resilient incident management workflow using ilert

Your payment API suddenly returns 503 errors. Within seconds, your infrastructure monitors, application checks, and dependency monitors begin generating their own alerts. And while the dashboards keep flashing, the clock is still running. Your customers are waiting, internal teams are asking for updates, and engineers are trying to separate the real problem from the noise before the situation gets worse.

5 Ways IT Leaders Are Using AI to Improve Operations in 2026

As the world is racing to plug AI into nearly every part of business, especially software engineering, the stakes to maintain operational integrity have never been higher. AI-generated code and AI-agents ship faster than human SREs can prepare for, which can create costly issues down the line: incidents get harder to predict and more expensive to recover from.

We turned off Pub/Sub and nobody noticed

Like many modern software stacks, the incident.io platform is predominantly event-driven. For example, whenever you send us an alert, post a message to our agent on Slack, or update an entry in your Catalog - these are all events that then get enqueued on a message topic, meaning any of our downstream components that are interested in that event can subscribe and react asynchronously, such as sending a push notification or posting a reply to you in Slack.

We made our blog easier to read

Two weeks ago, we asked ourselves a simple question: How can we improve the reading experience of Spike’s blog? There are about two hundred articles on the blog, covering alerting, on-call, incident response, and more. Kaushik and I discussed each of these topics thoroughly before turning them into articles. But when someone landed on the blog, they couldn’t easily discover these articles. It was mostly one long scroll, and though we had some categories, they weren’t organized well.

Cloud Outage Resilience: On-Call Lessons for 2026

Cloud outage resilience has quietly become the most important reliability topic of the year. Analysts now treat large scale cloud downtime as a matter of when, not if. Forrester has predicted at least two major multi day hyperscaler outages in 2026, and the reasoning is hard to argue with. AWS, Azure, and Google Cloud together account for well over half of enterprise cloud spending, so when any one of them stumbles, a huge slice of the digital economy stumbles with it.