Operations | Monitoring | ITSM | DevOps | Cloud

The latest News and Information on Incident Management, On-Call, Incident Response and related technologies.

Building Investigations: what it takes to build an AI SRE

At incident.io, we've spent the last two years building Investigations, our AI SRE. When you get paged, it starts investigating straight away, looking across your telemetry, recent deploys, past incidents, docs and code, and posts what it's found in your incident channel (or on your phone, if it's 2am and you're still deciding whether you need to get out of bed). By the time you open your laptop, you're starting at step six of triage rather than step one.

Top 10 RMM (Remote Monitoring and Management) Tools for IT Teams in 2026

Managing a growing IT environment requires more than reacting to problems as they appear. IT teams and managed service providers (MSPs) need continuous visibility into endpoints, servers, networks and other infrastructure so they can identify potential issues, perform maintenance and resolve problems remotely. That is where remote monitoring and management (RMM) software comes in. RMM tools provide IT teams with a centralized way to monitor and manage distributed IT environments.

BigPanda Analytics: AI-driven insights and faster answers across all your ITOps data

See how BigPanda Analytics turns IT operations analytics into instant answers, no hand-built reports required. IT leaders are used to waiting on a report someone on the ops team had to hand build, and every follow-up question starts the cycle over again, while the business keeps moving. This demo shows how IT executives get direct access to IT operations analytics: prebuilt dashboards, AI-powered insights, and a natural language research tool that answers questions in real time.

Your On-Call Rotation Has a Single Point of Failure, and It Gets the Flu Every Winter

Most teams design on-call for the failures they can see in a dashboard. A region goes down, a deploy goes sideways, a certificate expires at 2 a.m. The rotation exists so that someone is always there to catch it. Far fewer teams design for the failure that takes out the catcher: the on-call engineer wakes up with a fever, and the plan for that is usually a Slack message and hope. Treat a sick engineer the way you would treat any other dependency outage. It is predictable, it is seasonal, and it has a blast radius that grows with every shortcut in the rotation design.

MTTR Is Not a Time Problem. It Is a Context Problem

Your Mean Time to Resolution (MTTR) has likely stayed flat for three or four quarters. The investment was real: scheduling tools, dispatch optimization, new training modules, and more technicians. Operations reviews still dissect response time, travel time, and wrench time. The metric still refuses to move. Most field service leaders measure MTTR from the start of the repair to the moment the asset returns to service.

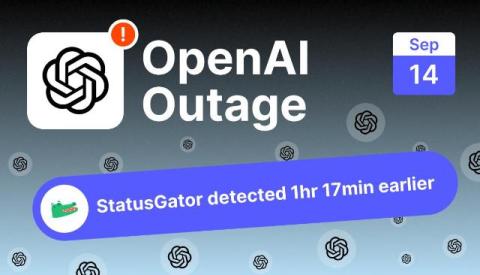
OpenAI outage on September 14, 2026: "some tools are temporarily unavailable" errors hit ChatGPT worldwide

ChatGPT’s tools and workspace features failed for users around the world on September 14, 2026, with the message “Some tools are temporarily unavailable” blocking spreadsheet and document creation, Codex, Projects, file reading, and dictation while core chat largely kept working. StatusGator sent an Early Warning Signal at 14:41 UTC, 1 hour and 17 minutes before OpenAI publicly acknowledged the incident at 15:58 UTC.

The Context Switching Cost of On-Call Work, and How Teams Reduce It

Ask an engineer what on-call costs them and most will describe a page at three in the morning. Those nights are real, and they are also comparatively rare on a healthy rota. Teams plan for them, compensate for them, and talk about them openly. The larger cost is quieter and almost never discussed, because it does not look like an incident. It is what happens to an ordinary Tuesday when you are carrying the pager: work arrives in fragments, nothing deep gets finished, and by Friday you have been busy for five days without being able to say what you built.

Swarm Investigation: Watch AI Agents Resolve Incidents in Minutes | BigPanda

Swarm investigation puts an entire team of AI agents on a major incident at once, cutting root cause discovery from hours to minutes. Every minute of a major incident costs real money, and traditional investigation, whether it's one engineer chasing a hypothesis or a team coordinating across tools, can't keep pace. This video shows how BigPanda's Swarm investigation dispatches AI agents to query systems, compare signals, and validate root cause in real time. See how autonomous incident response turns hours of manual troubleshooting into minutes.